Updated and tested:
- one single Host
- lab-Pool (3 Hosts) - NFS Storage
- lab-Pool (4 Hosts) - iscsi Storage
Everthing seems to work as expected.
(new VM, live-migration, snapshots, clone VMs, import/export VMs)
Updated and tested:
Everthing seems to work as expected.
(new VM, live-migration, snapshots, clone VMs, import/export VMs)
Hi @all,
sorry for my late reply, but i was on site at a customer yesterday.
I can confirm its working again as expected.
Not only this, but it also cleaned up all the additional Replikas now.
Great work and thanks for all your efforts.
Kind regards
Alex
@probain
I have a similar, even not the same Problem right now.
Maybe there is the same root-cause, so im linkin it here.
https://xcp-ng.org/forum/topic/11540/continuous-replication-isnt-deleting-old-replikas-anymore-since-update
Kind Regards
Alex
Hi @all,
running XO from source - (Commit fa020) on a fully update XCP-NG 8.2.
I have 2 CR Jobs on 2 XCP-Hosts, replicating all running VMs vice versa with a retention of 2 three times a day.
This worked for Months flawlessly, so i always have on srv01 2 replikas of each running VM on srv02 and vice versa.
Since Friday (did an Update of XenOrchestra that day), replication is still running fine but the old replikas are not deleted anymore, resulting in 12 existing replikas today.
I've tried to delete the old schedule and re-create it.
I've tried to delete the replication-job, and re-create it.
I've tried adjusting the retetion
I deleted all Replikas and startet the jobs from scratch.
None of the above have had any discernable affect.
Any Idea where to start investigating?
I searched the forum, but could not find any existing topic like this, except one similar, but not the same Problem.
https://xcp-ng.org/forum/topic/11539/snapshots-are-no-longer-being-pruned-commit-58f02
Maybe it could be the same root cause, so i am linking it here.
Thanks for suggestions in advance!
Alex
@stormi
Did some Testing over the Weekend too.
Setup with 2 Hosts in a Pool and shared iSCSI-LMV Storage with multipath 8 paths per LUN.
Anything seems to work fine (migrate/import/cross-pool-migrate/snapshots/backups).
Even our longtime Problem (snapshots taking much too long) is getting much better (still not good, but much better).
Apologies for the long silence on my end — real life got in the way and I couldn't dig into this for a while. Finally found the time now to go through it again properly, helped a lot by the details others have already posted here in the meantime.
I don't think this adds a new root cause, but it does corroborate what @kagbasi-wgsdac described — same "mass collapse onto a single anchor UUID" pattern, and in my case too that anchor is a real, still-in-use base disk, not a dangling/non-existent OpaqueRef (referencing vatesfr/xen-orchestra#9578).
Environment: 2-host pool, shared NFS SR, XO recently updated to the latest version (didn't change anything regarding this issue, as expected since it's XAPI-side).
Ran a read-only xe vdi-list params=uuid,name-label,is-a-snapshot,snapshot-of,snapshot-time directly against the pool master. Result: 47 of 196 VDIs match the pattern (is-a-snapshot: false but snapshot-of populated). All 47 point to the exact same single anchor UUID — which resolves to one specific, actively-used base VDI, not a missing reference.
snapshot-time on most affected VDIs is the epoch default (1970-01-01T00:00:00Z), but a handful show plausible real dates (e.g. late 2025 / early 2026) — suggesting those entries originally had a legitimate snapshot-of relationship that got overwritten by whatever corrupted the metadata.
Currently-running VMs affected (100% of each VM's disks affected in every case):
| VM | OS | Disks | Sizes |
|---|---|---|---|
| VM-1 | Windows Server 2016 | 1 | 50 GB |
| VM-2 | Windows Server 2016 | 3 | 50 / 200 / 450 GB |
| VM-3 | Windows Server 2019 | 3 | 100 / 100 / 100 GB |
| VM-4 | Windows 11 Pro | 2 | 50 / 100 GB |
| VM-5 (decommissioned) | Windows Server 2016 | 2 | 100 / 50 GB |
| VM-6 | Ubuntu 24.04 | 2 | 10 / 10 GB |
| VM-7 | Ubuntu 24.04 | 2 | 10 / 10 GB |
| VM-8 | Windows Server 2025 | 3 | 25 / 25 / 64 GB |
| VM-9 | Ubuntu 24.04 | 2 | 10 / 10 GB |
On top of that, ~28 more affected VDIs are orphaned/unattached objects ("base copy" leftovers, old ISO references) — same pattern, no VBD attached.
Not touching any of this (no snapshot-fixer.py, no manual vdi-param-set) given the risk of severing legitimate snapshot relationships that's already been flagged here. Happy to provide a full anonymized xe vdi-list dump if that's useful for tracking down the root cause.
Big thanks to everyone who kept digging into this and shared their findings here — especially @kagbasi-wgsdac for the detailed write-up that pointed me in the right direction, and of course @poddingue and the whole Vates team for staying on top of this and keeping us updated despite no clear timeline yet. Really appreciate the effort that goes into this, especially for something as tricky as a metadata corruption bug across production pools.
Kind Regards and thx again
Alex
Thanx for your replies.
And sorry, i havent seen your first reply between my last posts with the link to your existing Thread.
So, i think this is some kind of a bigger thing.
Will handle with care, but i have to leave for today.
Maybe i have time to test the snapshot and revert workarounds on the weekend.
But these are all production VMs.
Have to coordinate.
I have 2 NFS-SRs in the Pool.
Will try to migrate VMs from one to the other and see if this helps.
Kind Regards and thx again
Alex
Thanks for your Reply.
Just one little correction.
Also in XO6, the Disks are missing in the VM-VDI Tab.
Its exactly the same in XO5 and XO6.
Only in XCP-ng Center i see the Disks.
I noticed an additional thing.
In the Health-Dashboard, i see one orphaned "base copy" for each Disk that is adressed by this behaviour.
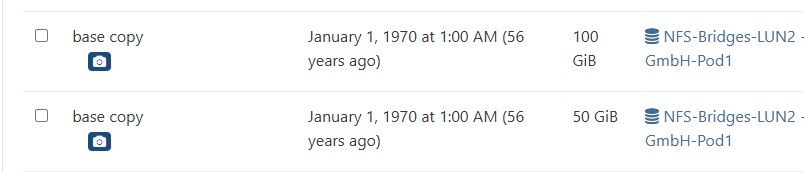
Exactly the amount of Disks of all my VMs with this problem.
(in the screenshot only the two of the VM of the former screenshots)
I am shure there are no orphaned VDIs, its just the base-copies of all my active Disks.
I think this could be possibly extremely dangerous, if someone has the same problem and removes the orphanes at this point.
But maybe i am too paranoid here?
@Pilow
Indeed.
Thats exactly the Point.
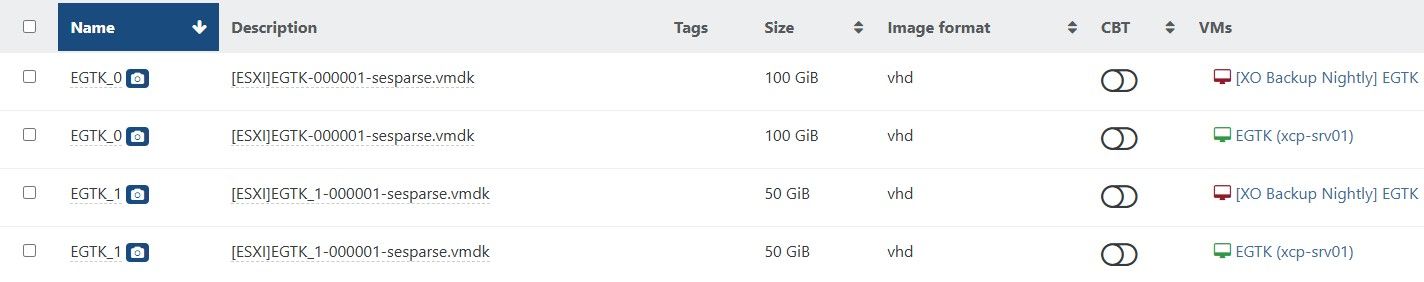
All my VMs that ran into my nightly Backups, have this.
To test it i created a new VM that didnt get a snapshop yet.
In the new VM i see the Disks.
Hi @all,
i noticed a strange behaviour in one environment with one pool (2 Hosts and NFS Storage) and 2 single node xcp-ng servers.
XenOrchestra from sources, connected directly to the pool and the 2 Servers.
When i open a VM in XenOrchestra, resident on an a single node, i see the VM Disks in xo and similar in XCP-ng Center.
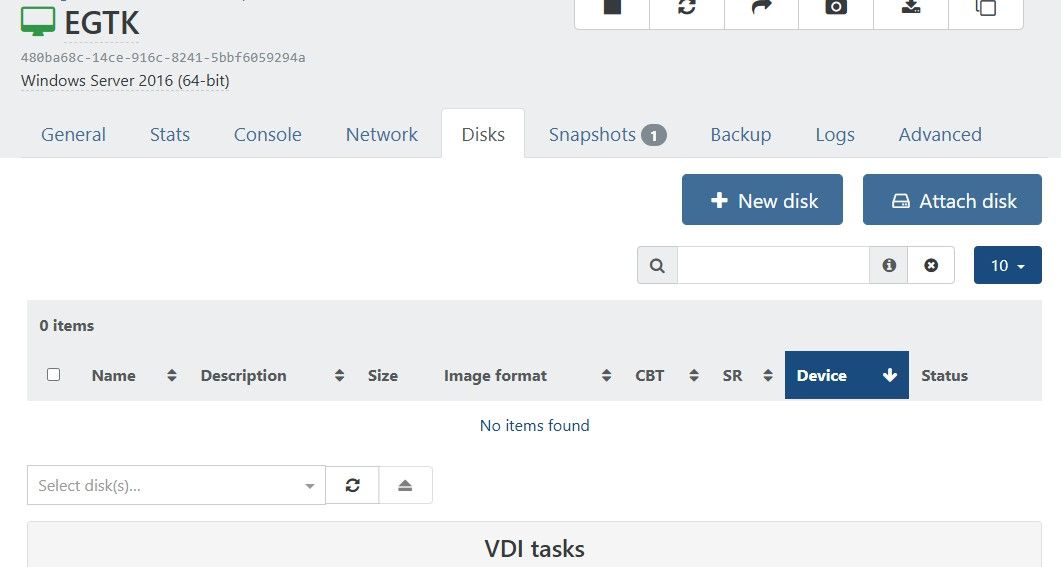
When i open a VM in the same XenOrchestra resident on the pool (no matter if disks are on nfs shared storage or local storage of a Host), i dont see the disks in XenOrchestra (looks like no disks attached).
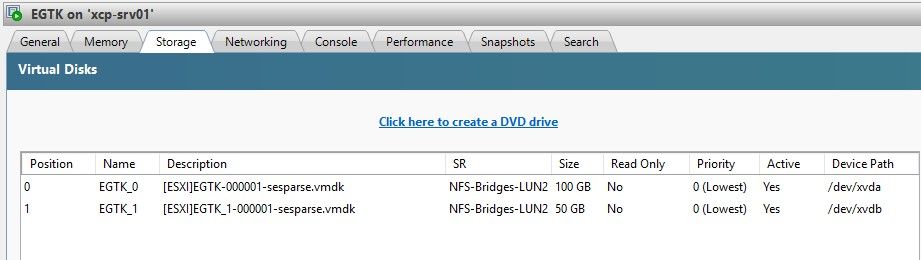
But in XCP-ng Center the disks are there and the VMs are running fine.
I did a full update today of XenOrchestra to actual commit and also upgraded the pool today (rebootet master first, then slave).
But the issue is still the same.
Is there anyone who has the same issue?
Screenshots of one of the VMs on the Pool:
in XenOrchestra
in XCP-ng Center
Hi @all,
sorry for my late reply, but i was on site at a customer yesterday.
I can confirm its working again as expected.
Not only this, but it also cleaned up all the additional Replikas now.
Great work and thanks for all your efforts.
Kind regards
Alex
@probain
I have a similar, even not the same Problem right now.
Maybe there is the same root-cause, so im linkin it here.
https://xcp-ng.org/forum/topic/11540/continuous-replication-isnt-deleting-old-replikas-anymore-since-update
Kind Regards
Alex
Hi @all,
running XO from source - (Commit fa020) on a fully update XCP-NG 8.2.
I have 2 CR Jobs on 2 XCP-Hosts, replicating all running VMs vice versa with a retention of 2 three times a day.
This worked for Months flawlessly, so i always have on srv01 2 replikas of each running VM on srv02 and vice versa.
Since Friday (did an Update of XenOrchestra that day), replication is still running fine but the old replikas are not deleted anymore, resulting in 12 existing replikas today.
I've tried to delete the old schedule and re-create it.
I've tried to delete the replication-job, and re-create it.
I've tried adjusting the retetion
I deleted all Replikas and startet the jobs from scratch.
None of the above have had any discernable affect.
Any Idea where to start investigating?
I searched the forum, but could not find any existing topic like this, except one similar, but not the same Problem.
https://xcp-ng.org/forum/topic/11539/snapshots-are-no-longer-being-pruned-commit-58f02
Maybe it could be the same root cause, so i am linking it here.
Thanks for suggestions in advance!
Alex
crosstestet with XOA
All working fine as expected.
So it seems that first Host has some Problems and is not providing any useful data when it comes to exporting the first delta snapshot.
Unfortunately i have to change to customer support right now and have to stop my testings for today.
I will keep going tomorrow.
Thx for your support so far.
ok, so i tested with XOA.
fully new (empty) NFS-Export mounted as remote in XOA.
i will crosstest now with a VM on the working Host.