Hello @ronan-a
I will reproduce the case, i will re-destroy one hypervisor and retrigger the case.
Thank you @ronan-a et @olivierlambert 
If you need me to tests some special case don't hesit, we have a pool dedicated for this
 H
Offline
CTO & Associate @Gladhost
Hello @ronan-a
I will reproduce the case, i will re-destroy one hypervisor and retrigger the case.
Thank you @ronan-a et @olivierlambert
If you need me to tests some special case don't hesit, we have a pool dedicated for this
Hello, @ronan-a
I will reinstall my hypervisor this week.
I will reproduce it and then, resend you the logs.
Bonne journée,
Hello @poddingue , you right.
Yes i saw this article, but it was unrelated to my issue.
I agree your guess.
How can i mark the topic as Solved ?
Hello, @DustinB
The https://vates.tech/xostor/ says:
The maximum size of any single Virtual Disk Image (VDI) will always be limited by the smallest disk in your cluster.
But in this case, maybe it can be stored in the "2TB disks" ? Maybe others can answer, i didn't test it.
This test permit to cover the following scenario:
Impact:
Expected results:
We didn't tests other filesystem than XFS for Linux based operating system because we use only XFS.
[hdevigne@VM1 ~]$ htop^C
[hdevigne@VM1 ~]$ echo "coucou" > test
-bash: test: Input/output error
[hdevigne@VM1 ~]$ dmesg
-bash: /usr/bin/dmesg: Input/output error
[hdevigne@VM1 ~]$ d^C
[hdevigne@VM1 ~]$ sudo -i
-bash: sudo: command not found
[hdevigne@VM1 ~]$ dm^C
[hdevigne@VM1 ~]$ sudo -i
-bash: sudo: command not found
[hdevigne@VM1 ~]$ dmesg
-bash: /usr/bin/dmesg: Input/output error
[hdevigne@VM1 ~]$ mount
-bash: mount: command not found
[hdevigne@VM1 ~]$ sud o-i
-bash: sud: command not found
[hdevigne@VM1 ~]$ sudo -i
As we predicted it, the vm is completly fucked-up
Windows VM crash and reboot in loop.
Linstor controller was on node 1, so we will not be able to see linstor nodes status, but we supposed they are in "disconnected" and in "pending eviction", but that doesn't matter a lot, disks are in read only, vm are fucked up after writing, it was our expected bevahior.
Re-plug node 1 and node 2.
Windows boot normally
Linux VM stays in a "broken state"
➜  ~ ssh VM1
suConnection closed by UNKNOWN port 65535
We didn't test a duration up to the eviction states of linstor nodes, but the documentation show that a linstor node restore would works ( see https://docs.xcp-ng.org/xostor/#what-to-do-when-a-node-is-in-an-evicted-state )
We didn't use HA at this time in the cluster, that could helped a bit in the recovery process. but in a precedent experience that i didn't "historize" like this one, the HA was completely down because it was not able to mount a file, i will probably write another topic on the forum to bring my results public.
Having HA change the criticity of the following note.
Thanks to @olivierlambert, @ronan and other people on the discord canal for answering to daily question which permit to this kind of tests to be made. As promissed, i put my result online
Thanks for XOSTOR.
Futher tests to do: Retry with HA
@olivierlambert our opnsense resets the TCP states so the firewall block packet because it forgot about the tcp session.
And then, a timeout occured in the middle of the export.
Hello @olivierlambert
I confirm my issue came from my Firewall so, not related to XO.
However, it could be great to make logs more "clear", i mean:
Error: read ETIMEDOUT"
Become
Error: read ETIMEDOUT while connect to X.X.X.X:ABC
That would permit to understand more quickly my "real and weird" issue 
Best regards,
Hello @poddingue
Thanks for your investigation, this confirm my guess.
I removed them manually to reclaim disk space.
But in my opinion, the health should detect "useless directory". in the vdi directories. But this is "required" only if the backup metadata was clean without the directory cleaned.
Hello @florent ,
You mean, "check" right ? because if it's doesn't check, the job is finished before the merge and the merge run in background in xen orchestra.
Best regards,
Hello, @Pilow
Thanks for the tips !
But it would be great to see it in the Task UI to find more easily the trick.
Hello @poddingue
Thanks for your investigation, this confirm my guess.
I removed them manually to reclaim disk space.
But in my opinion, the health should detect "useless directory". in the vdi directories. But this is "required" only if the backup metadata was clean without the directory cleaned.
Hello,
I have a backup plan which backups all vms with a tag: backup=yes ( exemple ) to a NFS remote.
The backups appear in the Health section, and then, i click on delete ( to cleanup the space ).
But ... nothing is deleted on the remote.
the only things i can found a list of directory to clean in the xen-orchestra logs
xen-orchestra  | 2026-09-26T15:32:05.190Z xo:backup-archive INFO you could delete orphan VDI directory {
xen-orchestra  |   path: '/xo-vm-backups/e92f154d-0b9d-2c69-fb04-d8bf58b6e8f0/vdis/756c7d04-3b06-4b5d-b66d-b6ef6c4d53b1/e9228694-76f1-43e9-9e2e-18a1c91f5a01'
xen-orchestra  | }
Why XO doesn't clean the data in the remote ?
And now, how to make it clean ? ( i upgraded the xo, and then, i don't have my previous logs which mentions the list of directory to clean )
Thanks !
Hello @Maelstrom96.
This should be possible in the future version of XCP-NG built on top of alma 9
Hello @poddingue , you right.
Yes i saw this article, but it was unrelated to my issue.
I agree your guess.
How can i mark the topic as Solved ?
Hello.
Problem Solved.
My case:
Yesterday, i removed two hosts ( host 3 & host 4 ) whith local storages SR attached ( LVM ).
In XCP-NG, i "forgot" Host 3 & host 4, the hosts from the pool, but it doesn't forge the associated SR !
But Live migrating a VM from host 1 to host 2 ( of the same pool ) bot with local SR, FAIL because there is no SR plugin attached of Local Storage 4 ( hosts 4 ) neither Local storage 3 ( host 3 ).
So, i also forget theses 2 SRs and now it's ok.
i don't understand why SR not connected to anyone can prevent migration about vm from other to other sr.
Hello.
I have this error while trying to migrate VM from a host to another host. ( same versions ).
Jul 10 10:58:06 server xapi: [debug||3148384 ||storage_utils] Got failure: checking for redirect, call was: -> SR.scan({sr:S(a2e6300f-10f2-ec61-bcfb-6a1d62a00bff);dbg:S(Async.VM.migrate_send R:afa4f5b49fd9)}), results.contents: ["No_storage_plugin_for_sr","a2e6300f-10f2-ec61-bcfb-6a1d62a00bff"]
Jul 10 10:58:06 server xapi: [debug||3148384 ||storage_utils] Not a redirect: -> SR.scan({sr:S(a2e6300f-10f2-ec61-bcfb-6a1d62a00bff);dbg:S(Async.VM.migrate_send R:afa4f5b49fd9)})
Jul 10 10:58:06 server xapi: [error||3148384 ||storage_interface] Storage_error ([S(No_storage_plugin_for_sr);S(a2e6300f-10f2-ec61-bcfb-6a1d62a00bff)]) (File "ocaml/xapi-idl/storage/storage_interface.ml", line 451, characters 49-56)
Jul 10 10:58:06 server xapi: [error||3148384 ||storage_migrate] Storage_migrate.MigrateLocal.prepare Caught error Storage_error ([S(No_storage_plugin_for_sr);S(a2e6300f-10f2-ec61-bcfb-6a1d62a00bff)]) while preparing for SXM
Jul 10 10:58:06 server xapi: [error||3148384 ||storage_migrate] Caught Storage_error ([S(Migration_preparation_failure);S(Storage_error ([S(No_storage_plugin_for_sr);S(a2e6300f-10f2-ec61-bcfb-6a1d62a00bff)]))]) during SXM:
Jul 10 10:58:06 server xapi: [error||3148384 ||task_server] Task 3 failed; Storage_error ([S(Internal_error);S(Storage_error ([S(Migration_preparation_failure);S(Storage_error ([S(No_storage_plugin_for_sr);S(a2e6300f-10f2-ec61-bcfb-6a1d62a00bff)]))]))])
Jul 10 10:58:06 server xapi: [debug||3148384 ||storage] TASK.signal 3 = ["Failed",["Internal_error","Storage_error ([S(Migration_preparation_failure);S(Storage_error ([S(No_storage_plugin_for_sr);S(a2e6300f-10f2-ec61-bcfb-6a1d62a00bff)]))])"]]
Do you know what No_storage_plugin_for_sr mean ?
It's a simple local storage
Hello there
I start to use slowly XO6 since many features was added.
But i observe this:
I have a VM with 3 backups jobs associated:
But in the UI, i see this:
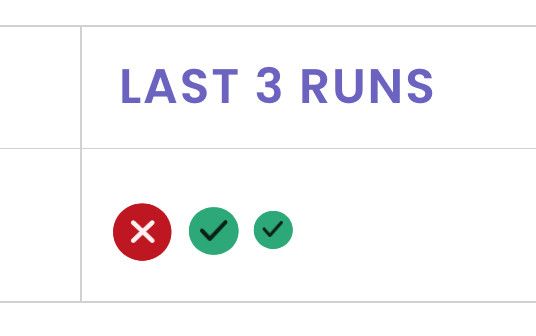
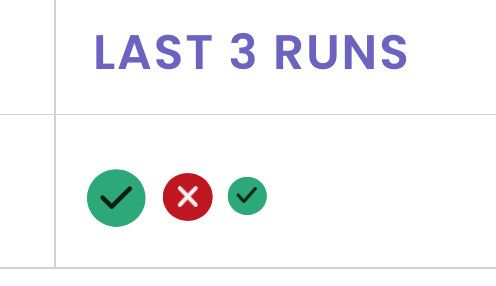
The jobs should be order from the "most recent" to "older one" ( or vice versa, i don"t have opinion on it ).
But showing the fail as the first make us thinks that the last jobs fail, that's not the case.
I should have:
Thank you
Hello,
All is in the title

Is this normal ?
Thanks !
Hello,
To gave more details abouit my case:
AMD EPYC 4464P 12-Core Processor6.12.0-211.18.1.el10_2.x86_64