Subcategories

  • All Xen related stuff

    627 Topics
    6k Posts
    D
    @hrvojer There are many bugs in older versions of the Xen PV drivers. I suggest running Windows without guest tools and drivers if you can take the performance and functionality hit (no suspend/migration on UEFI VMs, no metric reporting, etc).
  • The integrated web UI to manage XCP-ng

    29 Topics
    367 Posts
    olivierlambertO
    The same as @john.c and also XO Lite tends to be less a priority because less critical than the full fledged XO (the priority is to replace entirely XO 5 in the next releases). Why you would need XO Lite outside basic actions? It's mostly meant to bootstrap XO itself and do basic operations (which is already the case, at least with many basic features already). Initially, the goal hasn't moved: replacing XenCenter. We are moving in that direction, but again, I think it's more important to get XO 6 finished first. I'm curious to understand more the use case of XO Lite in your context @unreal-shizzle ?
  • Section dedicated to migrations from VMWare, HyperV, Proxmox etc. to XCP-ng

    132 Topics
    1k Posts
    J
    @mpiton Thanks for a fantasticly quick answer, and detailed as well. I will test this immediately! Update: I can confirm that this was indeed the problem!
  • Hardware related section

    178 Topics
    2k Posts
    S
    @yannsionneau Yes it works Thank you very much, great job Tested on Ryzen 9 9950X / AMD Raphael iGPU Tested the new experimental iGPU passthrough packages. - CPU: AMD Ryzen 9 9950X - iGPU: AMD Raphael (1002:13c0) - XCP-ng: 8.3 - Guest: Bazzite AMD - VBIOS: extracted from the ACPI VFCT and supplied as /root/vbios.bin - iGPU passthrough: working - AMD amdgpu driver: working - Physical HDMI output: working - Bazzite desktop displayed successfully on the physical HDMI port. Ubuntu 24.04.2 was able to initialize the GPU and Vulkan/RADV detected the Raphael iGPU, but the HDMI output went black when the graphical desktop started. Bazzite worked and provided a stable display output. So on my Ryzen 9 9950X, the experimental packages appear to successfully enable Raphael iGPU passthrough and physical HDMI output.
  • The place to discuss new additions into XCP-ng

    255 Topics
    3k Posts
    dicode-nlD
    New version: https://github.com/dicode-nl/xcp-ng-ceph-rbd/releases/tag/v20260903 This one includes native Ceph rbd SXM over SMAPIv3! GitHub updated with the latest commits and changes. As always, use with caution. I did run a lot of test scenario's but please do test yourself and let me know your findings!
  • 0 Votes
    2 Posts
    74 Views
    poddingueP
    The docs have a section for this symptom, Windows Server 2025 hanging at 0% CPU: https://docs.xcp-ng.org/troubleshooting/windows-pv-tools#windows-server-2025-hangs-randomly-with-0-cpu . Besides the Viridian flags you've already set, it says to revert useplatformclock and useplatformtick with bcdedit if they were ever set in the guest. Your earlier thread showed a VM created from the "Other install media" template, so it's worth checking which template this one came from, since the Windows templates bring their own Viridian settings. I don't think the QEMU SIGTERM is the cause, though: when I force-shut down a VM on a lab host, qemu-dm logged that exact terminating on signal 15 line, sent by xenopsd-xc (ps -o comm -p 1526469 will tell you on yours), so yours most likely just matches your forced shutdown around 10:20 on 5 Oct. If it freezes again after that, the memory dump procedure further down the same page (https://docs.xcp-ng.org/troubleshooting/windows-pv-tools#how-to-gather-kernel-memory-dumps-for-in-depth-troubleshooting) is likely what people who know Windows guests better than me would want to see.
  • [SOLVED] Just FYI: current update seams to break NUT dependancies

    Solved
    40
    0 Votes
    40 Posts
    9k Views
    F
    So, for everyone who wants to install NUT as a service follow these steps. Modifying the systemd files can make you system unbootable! It should not happen, but there is chance since we are also modifying some "natively shipped files". So an update can break your working configuration again and that is not the fault of XCP-NG!!! As prerequisite it requires the installation and testing of this step-by-step guide https://xcp-ng.org/forum/post/104253. Make sure everything runs before proceeding to the following steps! Now: ################################# Remove "nut-driver.target" dependency ################################# Remove "nut-driver.target" dependency from "nut-server.service" by calling nano /lib/systemd/system/nut-server.service and remove nut-driver.target from routine. I prefer to duplicate and comment to keep the modified rows in the original code. It then should look like this. DO NOT COPY AND PASTE, read, compare and modify carefully! [Unit] Description=Network UPS Tools - power devices information server #After=local-fs.target network.target nut-driver.target After=local-fs.target network.target # We don't Require drivers to be successfully started! This would be # a change of behavior compared to init SysV, and could prevent from # accessing successfully started, at least to audit a system. #Wants=nut-driver.target Wants= # The `upsd` is a networked service (even if bound to a `localhost`) # so it requires that the OS has some notion of networking already. # Extending the unit does not require *this* file to be edited, you # can instead drop in an additional piece of configuration, e.g. add # a `/etc/systemd/system/nut-server.service.d/network.conf` with: # [Unit] # Requires=network-online.target # After=network-online.target Requires=network.target Before=nut-monitor.service PartOf=nut.target [Service] EnvironmentFile=-/etc/ups/nut.conf SyslogIdentifier=%N # Note: foreground mode by default skips writing a PID file (and # needs Type=simple); can use "-FF" here to create one anyway: ExecStart=/usr/sbin/upsd -F ExecReload=/usr/sbin/upsd -c reload -P $MAINPID [Install] WantedBy=nut.target ################################# Add Service for ups-driver ################################# nano /etc/systemd/system/ups-driver.service [Unit] Description=NUT UPS Driver After=network-online.target Wants=network-online.target Before=nut-server.service [Service] Type=oneshot ExecStart=/usr/sbin/upsdrvctl start ExecStop=/usr/sbin/upsdrvctl stop RemainAfterExit=yes [Install] WantedBy=multi-user.target ################################### Add Requirement for nut-server ################################# mkdir -p /etc/systemd/system/nut-server.service.d nano /etc/systemd/system/nut-server.service.d/ups-driver.conf [Unit] Requires=ups-driver.service After=ups-driver.service ################################### Add Requirement for nut monitor ################################# mkdir -p /etc/systemd/system/nut-monitor.service.d nano /etc/systemd/system/nut-monitor.service.d/nut-server.conf [Unit] Requires=nut-server.service After=nut-server.service ################################### Enable services ################################### systemctl daemon-reload systemctl enable ups-driver.service systemctl enable nut.target systemctl enable nut-server.service systemctl enable nut-monitor.service systemctl start nut-monitor.service ################################### Analyze & debugging commands ################################### systemctl list-dependencies nut-monitor.service systemd-analyze critical-chain nut-monitor.service systemctl show nut-monitor.service -p Requires -p Wants -p After systemctl show nut-server.service -p Requires -p Wants -p After
  • 1 Votes
    6 Posts
    239 Views
    dthenotD
    @racom.jiristerba Sorry, I missed answering your questions the first time Is the tapdisk QCOW2 commit failure “The device is not writable: Permission denied” a known issue with these package versions on shared LVM/iSCSI storage? Yes, it's a known issue, most of them will be fixed with the latest update, you might need to activate the VDI again but a migration during RPU will be enough Why does rollback attempt to deactivate the active guest LV while tapdisk still holds it open? It's because in the case of VHD, it's the case but with QCOW2 we don't stop the tapdisk process accessing the VDI, it's a change that was missed Is the qcow2OLD_<UUID> naming seen in rollback expected, compared with QCOW2-OLD_<UUID> seen during successful cleanup? It's a pre-existing bug that I already have on my TODO list Is there a supported update, hotfix, or workaround for this configuration? Installing the latest release sm-3.2.12-25.1 during updates (and maybe launching a xe sr-scan uuid=<SR UUI> after updating it so it auto-resolve the undo) should be enough What additional logs are required to identify the original failure of the second QCOW2 VM? I don't think we need any more logs since the errors I'm seeing should already be fixed. If you have any more issues after installing the newest packages, I will take another look What is the recommended recovery procedure without a guest outage, and how should we validate the disk chains before resuming snapshot backups? The sr-scan after updating should do it automatically, it shouldn't need any manipulation. Looking at the storage logs in /var/log/SMlog for any irregularities could help to see problems.
  • XCP-ng Shutdown Hangs When an SR Is Unavailable

    Unsolved
    3
    0 Votes
    3 Posts
    101 Views
    poddingueP
    This came up in https://xcp-ng.org/forum/topic/11728 last winter, with the same kind of setup, an ISO SR served by a VM on the host. Olivier's answer there was to eject the CDs from the VMs, unplug the ISO SR's PBD, and only then shut the host down, using xe vm-cd-eject --multiple and xe pbd-unplug uuid=<PBD UUID> for the first two steps (the PBD one is in the CLI reference: https://docs.xcp-ng.org/appendix/cli_reference#pbd-unplug). @mickwilli then added the unplug to his UPS shutdown script, and his host shut down cleanly after that. I haven't tried it with an SMB share myself, so I can't promise it behaves like his NFS one, but your NUT script on the Pi looks like the natural place for those two steps, just before the shutdown command.
  • Enable Maintenance Mode = Host Not Enough Memory

    Unsolved
    5
    0 Votes
    5 Posts
    212 Views
    J
    @poddingue Our HA-pool is a 3 host system, yes. I'll add a note about our plans to go paid in that feedback-item. Thanks for the tip. In the meantime, I'm testing and reporting as much as I can. In order to hopefully help the product be better for all. Cheers!
  • Reducing vCPU isn't done live on Windows

    Solved
    4
    0 Votes
    4 Posts
    206 Views
    olivierlambertO
    I wasn't even aware about this being a Windows limitation by itself
  • 1 Votes
    4 Posts
    256 Views
    dthenotD
    @samuelolavo Hello, Could the fact that this is a local LVM SR on a non-master host be relevant to how make_chain_rw is being handled? Yes, it's indeed what's happening. The check for the SRMaster (for a shared SR it's the master but for a local it's supposed to be done on the host directly) is failing and always saying False. I'll fix this. Thank you for the help
  • sr iso disconnect and crashed my hosts

    12
    0 Votes
    12 Posts
    3k Views
    H
    @olivierlambert We are still seeing similar issues on fully updated xcp-ng 8.3 host. We do reboot every time it happens. Is there anything we can do to fix this otherwise or prevent this from happening (beside manually disconnecting the cifs iso storage before the san goes for a reboot)?
  • `/run/sr-mount` parent directory created 0700 on some hosts, 0755 on others

    Unsolved
    4
    0 Votes
    4 Posts
    314 Views
    dthenotD
    @Dan Hello, So our investigation found that this change was introduced with commit https://github.com/xcp-ng/sm/commit/00637dd52e845d6016add9718fc9cc694aec9f0d It was aimed at EXTSR in particular, it appear that the first SR to be plugged is the one choosing the mode of sr-mount since util.makedirs also create the parent directory with the given mode. I have created a card for the issue on our side.
  • Nested virtualization - Prevent migration

    Unsolved
    1
    0 Votes
    1 Posts
    128 Views
    No one has replied
  • VM Display Resolution

    3
    0 Votes
    3 Posts
    280 Views
    poddingueP
    It was too tempting not to test, so I went and tested the other half. On an 8.3 host I set the preferred resolution to 800x600 in the OVMF menu on a UEFI Debian VM, turned that VM into a template, and cloned it. The clone came up at 800x600. A control clone of the same original, with nothing set, came up at 1024x768. So your workaround holds, the resolution really does ride along into VMs built from the template. For anyone who wants to poke at it, the setting is a UEFI variable called PlatformConfig under GUID 7235c51c-0c80-4cab-87ac-3b084a6304b1. It only appears in NVRAM once you commit it in the menu, and it stores width and height as plain little-endian integers, which is why it travels with the VM record. One thing I didn't expect: the OVMF help text says the mode list is filtered against video RAM size, but the VM I used had the default 4 MB and still offered everything up to 1280x1024. So you may not need to raise videoram for the common ones. Fair warning though, I measured the console at the firmware stage rather than after the distro's own driver takes over, so a guest that sets its own mode later could still override it. At least, that's my understanding.
  • Smart Reboot blocked in XO, and no Rolling Pool Update

    Unsolved
    9
    0 Votes
    9 Posts
    644 Views
    D
    @poddingue said: What I can't tell you is what set that particular combination on your VM in the first place. Does it ring a bell? I have no Idea. I had it on "Protect from accidental shutdown" but turned that off again, later. Doing this again (on, off) helped, as you said. Thank you so much!
  • VM autostart stopped working

    Unsolved
    8
    0 Votes
    8 Posts
    790 Views
    O
    @poddingue Thank you for the analysis. I'd give you a rep if I could
  • Sudden boot issues, emergency shell, root-lfgrma does not exist

    Solved boot dracut
    2
    0 Votes
    2 Posts
    212 Views
    S
    After a good sleep, I resolved half of my issue. I got my LSI Cards messed up, I accidentally hidan internal LSI3108 (Address 01:00.0) instead of the PCI Card LSI3008 (Address 05:00.0)... My Boot Drives run off of the internal card. From the fallback kernel, I was able to Modify /etc/grub-efi.cfg to remove the internal card form the hidden list. I now have a separate issue, but will make another post.
  • Autostart behaviour after upgrade 8.2 -> 8.3

    Solved
    6
    1
    0 Votes
    6 Posts
    525 Views
    poddingueP
    I put both of your questions on a spare host, because I couldn't answer either from memory. On colons: xe creates a key literally called auto_poweron:true with an empty value, so the entries you saw were three separate keys and none was the real auto_poweron, and typing false afterwards just made another one. It exits 0 and prints nothing every time, which I'd call a rough edge rather than a feature, though other-config is free-form by design so I don't know that the CLI is meant to validate keys at all. On the sleep: with rc.local executable and no sleep, it fired at 16 seconds of uptime and xe appliance-start came back with Error: Connection refused (calling connect ), exit 1, in under a tenth of a second. The VM stayed halted and nothing was reported anywhere, since rc.local has no terminal to print to. rc-local.service only orders after basic.target and network.target, nothing toolstack-related, while xapi-wait-init-complete.service took 30 seconds on that host, which is presumably why 60 was barely enough for you. There's an xapi-init-complete.target that looks like the right thing to order a unit against instead of guessing at a delay, though I haven't tried it so treat that as a lead rather than advice. The executable-bit half is in the docs now, it went onto the troubleshooting page after you reported it: https://docs.xcp-ng.org/troubleshooting/common-problems
  • 0 Votes
    5 Posts
    378 Views
    M
    Hard reboot sorted itself out
  • Get a price quote on a plan

    2
    0 Votes
    2 Posts
    213 Views
    DanpD
    Hi, I found your original request. I will make sure someone from the Sales team responds ASAP. Regards, Dan
  • CPU Usage of empty server

    Unsolved
    15
    3
    0 Votes
    15 Posts
    2k Views
    marcoiM
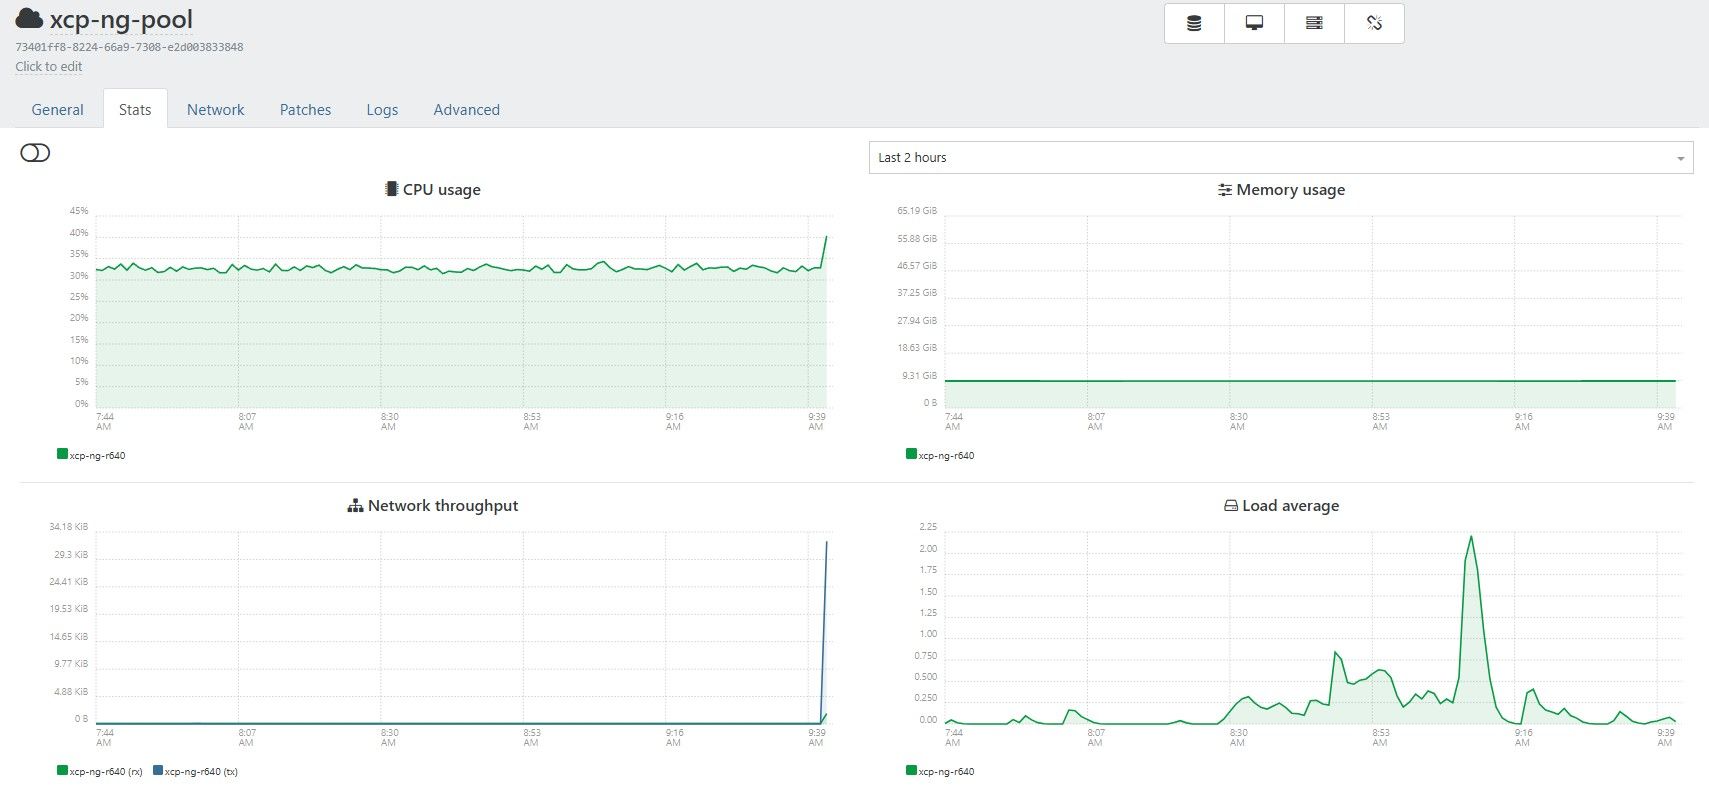
    i think im seeing the same with fake cpu spikes. I started a second pool yesterday to patch and left it on over night. typically i just shut it down once done so the servers dont get too far behind patching. Under the pool stats im seeing spikes but under hosts nothing. It doesnt really bother me, but figure i add to the thread that im also seeing it. [image: c75fecec-d618-4f05-a931-edea6bc6ecce-image.jpeg] [image: 1b9ea5aa-d349-4ff8-af89-30a970d36fbb-image.jpeg] [image: 0f579999-cd96-4216-a0d4-d637ea5febf1-image.jpeg]
  • The Lowest Priority Bug Ever? (/etc/udev/rules.d/z10-xen-vcpu-hotplug.rules)

    Unsolved
    10
    0 Votes
    10 Posts
    2k Views
    poddingueP
    Two PRs out of the lowest priority bug ever, that made my morning.
  • Unable to live migrate VM between 2 local storages SR

    Solved
    5
    0 Votes
    5 Posts
    689 Views
    poddingueP
    I converted the topic to a question, then marked it solved. Thanks!