Subcategories

  • All Xen related stuff

    627 Topics
    6k Posts
    H
    Hi all, We have a production Windows Server 2012 R2 VM (SQL Server) that has crashed three times with the same bugcheck in xenvbd.sys. Looking for advice and for a safe download of the last 2012 R2-compatible tools. Environment XCP-ng 7.6.0 (yes, we know it's EOL; [OPTIONAL - keep or delete: a host refresh/upgrade is already being planned]. Right now we need a stopgap for this VM.) Storage: LVM over FC (HPE MSA 1040), multipath VM: Windows Server 2012 R2 (build 9600.18505), 8 vCPU, 64 GB RAM (static, dynamic min = max) PV drivers: Citrix xenvbd.sys 8.1.0.130 (old Citrix tools) Crashes (identical each time) 2026-06-17, 2026-09-01, 2026-10-08 BUGCHECK 0xD1 DRIVER_IRQL_NOT_LESS_OR_EQUAL (0x18, 0x2, 0x1, xenvbd+0x8795) Write to NULL+0x18: lock xadd dword ptr [rcx+18h],eax with rcx = 0 Stack (from MEMORY.DMP): nt!KiRetireDpcList -> nt!KiExecuteAllDpcs -> xenvbd+0xf464 -> xenvbd+0x6f55 -> xenvbd+0xfecb -> xenvbd+0x8795 i.e. crash in a DPC, apparently in the I/O completion path. Context The VM ran with 16 GB RAM from 2023-09 to 2026-02 with zero crashes (no restarts at all in ~29 months). On 2026-02-06 RAM was raised to 64 GB (SQL max server memory 14 GB -> 48 GB). First crash 4 months later; intervals between crashes so far: 131, 76, 37 days. Host logs at the time of the last crash: no FC/SCSI/multipath errors. The only event on this VM's VDIs was one SMGC coalesce with a clean tapdisk pause/unpause about 12 minutes before the crash. Questions Is this a known xenvbd bug fixed in later versions (e.g. the 9.2.1 fix "A storage error can cause Windows VMs to crash", or the grant table exhaustion fix in 9.3.1)? A reply in the XSA-468 thread pointed to XenServer VM Tools 9.2.3 as the last version supporting 2012/2012 R2. Where can it be downloaded from an official source? downloads.xenserver.com only offers 9.6.0, and the same URL pattern for 9.2.3 returns 404. Could the RAM increase (16 -> 64 GB) plausibly trigger this with old xenvbd (grant tables, larger I/O)? Is there a workaround that doesn't require a driver update (e.g. a host-side setting)? We know 2012 R2 is EOL; we are looking for a safe stopgap. Thanks!
  • The integrated web UI to manage XCP-ng

    29 Topics
    367 Posts
    olivierlambertO
    The same as @john.c and also XO Lite tends to be less a priority because less critical than the full fledged XO (the priority is to replace entirely XO 5 in the next releases). Why you would need XO Lite outside basic actions? It's mostly meant to bootstrap XO itself and do basic operations (which is already the case, at least with many basic features already). Initially, the goal hasn't moved: replacing XenCenter. We are moving in that direction, but again, I think it's more important to get XO 6 finished first. I'm curious to understand more the use case of XO Lite in your context @unreal-shizzle ?
  • Section dedicated to migrations from VMWare, HyperV, Proxmox etc. to XCP-ng

    132 Topics
    1k Posts
    J
    @mpiton Thanks for a fantasticly quick answer, and detailed as well. I will test this immediately! Update: I can confirm that this was indeed the problem!
  • Hardware related section

    178 Topics
    2k Posts
    S
    Yes it works Thank you very much, great job Tested on Ryzen 9 9950X / AMD Raphael iGPU Tested the new experimental iGPU passthrough packages. - CPU: AMD Ryzen 9 9950X - iGPU: AMD Raphael (1002:13c0) - XCP-ng: 8.3 - Guest: Bazzite AMD - VBIOS: extracted from the ACPI VFCT and supplied as /root/vbios.bin - iGPU passthrough: working - AMD amdgpu driver: working - Physical HDMI output: working - Bazzite desktop displayed successfully on the physical HDMI port. Ubuntu 24.04.2 was able to initialize the GPU and Vulkan/RADV detected the Raphael iGPU, but the HDMI output went black when the graphical desktop started. Bazzite worked and provided a stable display output. So on my Ryzen 9 9950X, the experimental packages appear to successfully enable Raphael iGPU passthrough and physical HDMI output.
  • The place to discuss new additions into XCP-ng

    255 Topics
    3k Posts
    dicode-nlD
    New version: https://github.com/dicode-nl/xcp-ng-ceph-rbd/releases/tag/v20260903 This one includes native Ceph rbd SXM over SMAPIv3! GitHub updated with the latest commits and changes. As always, use with caution. I did run a lot of test scenario's but please do test yourself and let me know your findings!
  • Question about migration when creating VM

    9
    0 Votes
    9 Posts
    2k Views
    psafontP
    @olivierlambert Ideally XCP-ng (xapi) could add this to a queue, and wait for some time before cancelling the task because it took too long. This also needs some kind of feedback that can be given to the user / client, which I think currently is quite undercooked (how to report is waiting on other migrations to the same host when a client asks?). For the time I think XO being aware that it can retry the operation would be simpler, especially because it already has code to do it for other operations
  • Weird XAPI service looping (GPU passthrough)

    Solved
    3
    0 Votes
    3 Posts
    843 Views
    olivierlambertO
    Maybe a bad command that overwrote the file, anyway glad you managed to make it work!
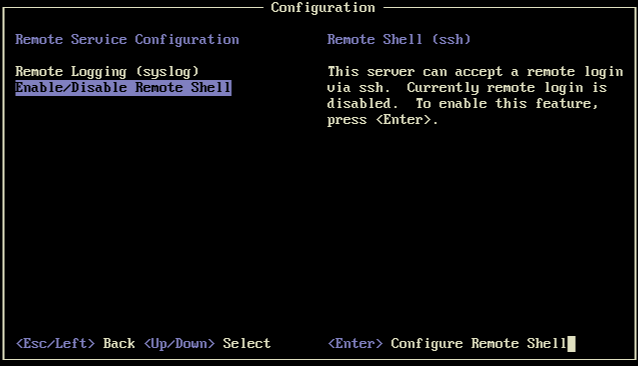
  • xsconsole UI Bug/Randomness?

    4
    2
    0 Votes
    4 Posts
    804 Views
    C
    The unusual one happened to occur on a Master (though not all Masters have this reverse ordering).
  • Netbox integration

    4
    0 Votes
    4 Posts
    1k Views
    olivierlambertO
    Right now, it's XO -> Netbox only. As soon as you want something bidirectional, the complexity is exponential. I'm not closed to the idea, but we need to carefully think about the how and what's really expected functionally speaking from our users
  • XCP-ng DR on Azure

    4
    -1 Votes
    4 Posts
    891 Views
    olivierlambertO
    It's not a trivial scenario indeed. Dom0 is a PV guest (in other words: a VM) on top of an hypervisor (Xen), on top of an hypervisor (HyperV). As you can see, more layers means more problems
  • Snapshot Question

    2
    0 Votes
    2 Posts
    646 Views
    R
    Sorry, I'm asking if I should be good deleting the snapshots
  • Unbootable VHD backups

    19
    1
    0 Votes
    19 Posts
    4k Views
    D
    @AtaxyaNetwork said in Unbootable VHD backups: @Schmidty86 Try to detach the disk and reattach, it should be xvda in order to be bootable That's what I was thinking as well, but obviously something is off with this VM. @Schmidty86 is the old host still online? If so you might be able to perform a Live Migration or a replication job to copy it from the old host to the new.
  • CBT Error when powering on VM

    28
    0 Votes
    28 Posts
    7k Views
    R
    AlmaLinux 8.10
  • RHEL UEFI boot bug

    5
    1
    0 Votes
    5 Posts
    2k Views
    kiuK
    Hello, thank you for your reply @bogikornel @TrapoSAMA . Here are my processor specifications: Intel Xeon E5-1620 v2 (8) @ 3.691GHz. Unfortunately @Andrew , I have to use RHEL 10 on my server ^^ but thank you for providing the link. I will change my processor/server.
  • DR error - (intermediate value) is not iterable

    2
    0 Votes
    2 Posts
    812 Views
    N
    I worked with ChatGPT on this for a bit. We have narrowed it down to an issue with the NFS Storage that I ship the backups to. "When you recreated storage and moved data back, OMV is technically exporting a different underlying filesystem object than before. NFS clients that had an old handle cached (your XCP-ng host) try to access it and get ESTALE. That explains the initial backup errors and why deleting/re-adding the SR is failing now." I had to remove the NFS storage from XCP-ng, then delete the NFS share from OMV, then add the NFS share back to OMV, and then add it back to XCP-ng. I probably could have resolved this with a reboot, but I didn't wanna. This issue is resolved now.
  • 0 Votes
    31 Posts
    9k Views
    D
    As @Andrew said, your host itself is unhealthy, you might be able to disassemble the CPU and heatseat, clean it up and add some new paste to address the issue with the CPU overheating (if the paste is shot). As for the memory issue, run a memtest on the host and see what is reported.
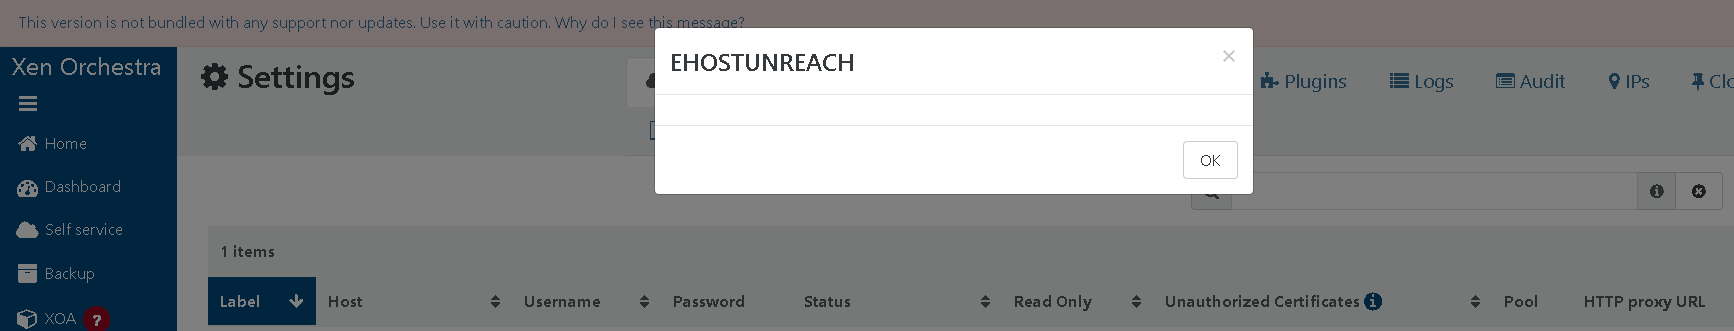
  • Connection failed "EHOSTUNREACH"

    4
    1
    0 Votes
    4 Posts
    967 Views
    A
    @santos_luan Check if there is any firewall issue on the XO-ce side.
  • Security Assessments and Hardening of XCP-ng

    security assessment
    11
    1 Votes
    11 Posts
    4k Views
    olivierlambertO
    Just quickly chiming in to confirm what @bleader said. We'll be happy to assist you further, especially to put you in contact with our head of security at Vates to discuss our future certification plans (he's a former ANSSI employee BTW).
  • 0 Votes
    7 Posts
    4k Views
    olivierlambertO
    CPU speed is great to enhance all Xen operations (using grants for example). But tapdisk got a lot of room to be better outside that, thanks to multiqueue and so on. However, it's not clear if it's better to improve tapdisk or making something different. This is an active topic of reasearch.
  • Windows Server not listening to radius port after vmware migration

    6
    0 Votes
    6 Posts
    1k Views
    nikadeN
    @acebmxer said in Windows Server not listening to radius port after vmware migration: After migrating our windows server that host our Duo Proxy manager having an issue. [info] Testing section 'radius_client' with configuration: [info] {'host': '192.168.20.16', 'pass_through_all': 'true', 'secret': '*****'} [error] Host 192.168.20.16 is not listening for RADIUS traffic on port 1812 [debug] Exception: [WinError 10054] An existing connection was forcibly closed by the remote host After the migration I did have to reset the IP address and I did install the Xen tools via windows update. Any suggestions? I am thinking I may have the same issue if i spin up the old vm as the vmware tools were removed which i think effected that nic as well.... On your VM that runs the Duo Auth Proxy service, check if the service is actually listening on the external IP or if its just listening on 127.0.0.1 If its just listening on 127.0.0.1 you can try to repair the Duo Auth Proxy service, take a snapshot before doing so. Also, if you're using encrypted passwords in your Duo Auth Proxy configuration you probably need to re-encrypt them, just a heads up, since I just had to do so after migrating one of ours. Edit: Do you have the "interface" option specified in your Duo Auth Proxy configuration?
  • 0 Votes
    5 Posts
    1k Views
    H
    We have some sites with a single-host XCP-ng pool backed by a small UPS. We install nut directly in dom-0. I'm aware of the policy for adding anything to dom-0 but we believe this usecase fits in the recommendations (simple enough, no vast dependencies, marginal resources usage, no interference ...). With proper testing works pretty well. nut inside a dedicated RPi definitely makes sense for a site with multiple hosts backed by the same UPS.
  • Unable to Access MGMT interface/ No NICS detected

    24
    4
    0 Votes
    24 Posts
    9k Views
    C
    @AtaxyaNetwork I'll check it out! Im currently on chrome. So ill see if they have something close to it. Thank you!
  • Migration compression is not available on this pool

    9
    0 Votes
    9 Posts
    2k Views
    henri9813H
    Hello, We tried the compression feature. You "can see" a benefit only if you have a shared storage. ( and again, the migration between 2 nodes is already very fast, we don't see major difference, but maybe a VM will a lot of ram ( >32GB ) can see a difference. If you don't have a shared storage ( like XOSTOR, NFS, ISCSI ), then you will not see any difference because there is a limitation of 30MB/s-40MB/s ( see here: https://xcp-ng.org/forum/topic/9389/backup-migration-performance ) Best regards,
  • Multi gpu peer to peer not available in vm

    4
    0 Votes
    4 Posts
    1k Views
    olivierlambertO
    Hmm I'm not sure it's even possible due to the nature of isolation provided by Xen Let me ask @Team-Hypervisor-Kernel
  • Internal error: Not_found after Vinchin backup

    56
    0 Votes
    56 Posts
    18k Views
    olivierlambertO
    So you have to dig in the SMlog to check what's going on