Subcategories

  • All Xen related stuff

    627 Topics
    6k Posts
    J
    OP here... So by saying this is "solved" then there's nothing specific or special to do in XCP-ng to make these work in pass-through to guests and that everything related to any operational or performance issues is directly a guest OS issue?
  • The integrated web UI to manage XCP-ng

    29 Topics
    367 Posts
    olivierlambertO
    The same as @john.c and also XO Lite tends to be less a priority because less critical than the full fledged XO (the priority is to replace entirely XO 5 in the next releases). Why you would need XO Lite outside basic actions? It's mostly meant to bootstrap XO itself and do basic operations (which is already the case, at least with many basic features already). Initially, the goal hasn't moved: replacing XenCenter. We are moving in that direction, but again, I think it's more important to get XO 6 finished first. I'm curious to understand more the use case of XO Lite in your context @unreal-shizzle ?
  • Section dedicated to migrations from VMWare, HyperV, Proxmox etc. to XCP-ng

    132 Topics
    1k Posts
    J
    @mpiton Thanks for a fantasticly quick answer, and detailed as well. I will test this immediately! Update: I can confirm that this was indeed the problem!
  • Hardware related section

    178 Topics
    2k Posts
    J
    Third update: It looks more and more that I had goofed something up in my testing. So please disregard everything in the post below. The driver does work to make our LPe37000/LPe38000 series FC-cards work. Which is nice. Thanks! ~~Good morning So I might've found an issue with this driver release. That I'm trying to troubleshoot and collect data on. We have two LUNs presented to our dev-pool (xcp-dev), running on R650xs. When I have attached one LUN to xcp-dev I can't see the other LUN. This works on our older R350s Removing the attached LUN, makes a LUN visible again. But now we're getting some strange behaviour. And looking into if it is misconfigured from the Dell Powerstore, or if it is on the host(s) itself.~~ Details: multipath is enabled Host on xcp-dev 98:00.0 Fibre Channel [0c04]: Emulex Corporation LPe37000/LPe38000 Series 32Gb/64Gb Fibre Channel Adapter [10df:f500] (rev 11) Subsystem: Emulex Corporation Device [10df:f522] Kernel driver in use: lpfc Kernel modules: lpfc14 98:00.1 Fibre Channel [0c04]: Emulex Corporation LPe37000/LPe38000 Series 32Gb/64Gb Fibre Channel Adapter [10df:f500] (rev 11) Subsystem: Emulex Corporation Device [10df:f522] Kernel driver in use: lpfc Kernel modules: lpfc14 Update: ~~After managing to revert my previous tests and forget the existing (wrong) LUN from xcp-dev. I can now confirm a problem. There are three LUNs. Let's call them 101, 102, 103 When I attach one LUN (103) to xcp-dev, I am no longer able to see the other LUNs. That means I can't add a second one. I am expecting to be able to see 102 available. However, on old-dev, that has two LUNs attached already (101 & 102). It can see 103 as expected.~~ host on old-dev 02:00.0 Fibre Channel [0c04]: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] (rev 03) Subsystem: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] Kernel driver in use: lpfc Kernel modules: lpfc 02:00.1 Fibre Channel [0c04]: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] (rev 03) Subsystem: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] Kernel driver in use: lpfc Kernel modules: lpfc Second Update: This might be unrelated. Seems that we're having weird behaviour with the LUNs in general. Please disregard the statement above for now
  • The place to discuss new additions into XCP-ng

    255 Topics
    3k Posts
    dicode-nlD
    New version: https://github.com/dicode-nl/xcp-ng-ceph-rbd/releases/tag/v20260903 This one includes native Ceph rbd SXM over SMAPIv3! GitHub updated with the latest commits and changes. As always, use with caution. I did run a lot of test scenario's but please do test yourself and let me know your findings!
  • 0 Votes
    3 Posts
    178 Views
    I
    @poddingue thanks, In my case there is an update from Microsoft which destroy the RDP/Console. below is the link for it. I patched the fix and it's now working fine. Also I try to use proper template for windows based vms so that all the params gets in the guest by default. https://support.microsoft.com/en-us/servicing/os/windows-server/2026/09/kb5129235-windows-server-2025-update
  • 1 Votes
    7 Posts
    397 Views
    R
    Thanks for the help; this error has been resolved following the installation. However, we have a new issue regarding CBT. We are experiencing recurring CBT failures with the following configuration: Veeam Backup & Replication: 13.1.1.18 Hypervisor: XCP-ng 8.3, three hosts Identical packages on all hosts: sm-3.2.12-25.1.xcpng8.3 blktap-3.55.5-11.1.xcpng8.3 xapi-core-26.1.19-1.1.xcpng8.3 These packages were installed on October 3, 2026, before the failures occurred. Affected VM: NMNM-V-S-L007 Source disk UUID: 2f546ede-efcb-4ccf-8c23-2ea5a5e0d01f Storage: LVM over iSCSI, SR name 70TB_HDD SR UUID: 26d9572f-01c1-9cfd-79de-ca96eab601cf The backup job finishes with a Warning. The failing operation is VDI.list_changed_blocks, which returns: SR_BACKEND_FAILURE_460 Failed to calculate changed blocks for given VDIs. [opterr=Source and target VDI are unrelated] The logs show repeated failures on October 12 and 13, 2026. During cleanup of an older snapshot, CBT metadata is merged directly into the live disk despite the existence of a newer snapshot. This suggests a possible inconsistency in the CBT parent/child relationships, although the root cause has not been confirmed. The reference snapshot used on October 13 was deleted only after the CBT failures, so its subsequent absence does not explain those failures. Attached logs: cbt-old-vdi-history.txt cbt-source-disk-history.txt cbt-chain-cleanup.txt Please investigate CBT chain handling during snapshot creation and deletion, verify the installed Xen plug-in version, and advise whether a relevant hotfix or a supported procedure to re-establish CBT tracking is available. Thank you.cbt-old-vdi-history.txt cbt-chain-cleanup.txt [cbt-source-disk-history.txt.zip](Invalid file type .zip. Allowed types are: .png, .jpg, .bmp, .txt, .diff, .patch, .jpeg)
  • Timezone updates for tzdata 2026e

    3
    1 Votes
    3 Posts
    245 Views
    gduperreyG
    Hello, We have received your request and thank you for the feedback on this matter. A task card has been created and assigned to one of our teams. It has not yet been assigned to a specific developer, but we will be sure to get back to you once it has been addressed and resolved.
  • XCP-ng Shutdown Hangs When an SR Is Unavailable

    Unsolved
    5
    0 Votes
    5 Posts
    1k Views
    ForzaF
    If a mount uses the hard mount option, it will lock any process touching it, including unmount during shutdown, if the mount source is unavailable. It is a kernel thing and I believe there is no solution for it at present.
  • [SOLVED] Just FYI: current update seams to break NUT dependancies

    Solved
    40
    0 Votes
    40 Posts
    10k Views
    F
    So, for everyone who wants to install NUT as a service follow these steps. Modifying the systemd files can make you system unbootable! It should not happen, but there is chance since we are also modifying some "natively shipped files". So an update can break your working configuration again and that is not the fault of XCP-NG!!! As prerequisite it requires the installation and testing of this step-by-step guide https://xcp-ng.org/forum/post/104253. Make sure everything runs before proceeding to the following steps! Now: ################################# Remove "nut-driver.target" dependency ################################# Remove "nut-driver.target" dependency from "nut-server.service" by calling nano /lib/systemd/system/nut-server.service and remove nut-driver.target from routine. I prefer to duplicate and comment to keep the modified rows in the original code. It then should look like this. DO NOT COPY AND PASTE, read, compare and modify carefully! [Unit] Description=Network UPS Tools - power devices information server #After=local-fs.target network.target nut-driver.target After=local-fs.target network.target # We don't Require drivers to be successfully started! This would be # a change of behavior compared to init SysV, and could prevent from # accessing successfully started, at least to audit a system. #Wants=nut-driver.target Wants= # The `upsd` is a networked service (even if bound to a `localhost`) # so it requires that the OS has some notion of networking already. # Extending the unit does not require *this* file to be edited, you # can instead drop in an additional piece of configuration, e.g. add # a `/etc/systemd/system/nut-server.service.d/network.conf` with: # [Unit] # Requires=network-online.target # After=network-online.target Requires=network.target Before=nut-monitor.service PartOf=nut.target [Service] EnvironmentFile=-/etc/ups/nut.conf SyslogIdentifier=%N # Note: foreground mode by default skips writing a PID file (and # needs Type=simple); can use "-FF" here to create one anyway: ExecStart=/usr/sbin/upsd -F ExecReload=/usr/sbin/upsd -c reload -P $MAINPID [Install] WantedBy=nut.target ################################# Add Service for ups-driver ################################# nano /etc/systemd/system/ups-driver.service [Unit] Description=NUT UPS Driver After=network-online.target Wants=network-online.target Before=nut-server.service [Service] Type=oneshot ExecStart=/usr/sbin/upsdrvctl start ExecStop=/usr/sbin/upsdrvctl stop RemainAfterExit=yes [Install] WantedBy=multi-user.target ################################### Add Requirement for nut-server ################################# mkdir -p /etc/systemd/system/nut-server.service.d nano /etc/systemd/system/nut-server.service.d/ups-driver.conf [Unit] Requires=ups-driver.service After=ups-driver.service ################################### Add Requirement for nut monitor ################################# mkdir -p /etc/systemd/system/nut-monitor.service.d nano /etc/systemd/system/nut-monitor.service.d/nut-server.conf [Unit] Requires=nut-server.service After=nut-server.service ################################### Enable services ################################### systemctl daemon-reload systemctl enable ups-driver.service systemctl enable nut.target systemctl enable nut-server.service systemctl enable nut-monitor.service systemctl start nut-monitor.service ################################### Analyze & debugging commands ################################### systemctl list-dependencies nut-monitor.service systemd-analyze critical-chain nut-monitor.service systemctl show nut-monitor.service -p Requires -p Wants -p After systemctl show nut-server.service -p Requires -p Wants -p After
  • Enable Maintenance Mode = Host Not Enough Memory

    Unsolved
    5
    0 Votes
    5 Posts
    302 Views
    J
    @poddingue Our HA-pool is a 3 host system, yes. I'll add a note about our plans to go paid in that feedback-item. Thanks for the tip. In the meantime, I'm testing and reporting as much as I can. In order to hopefully help the product be better for all. Cheers!
  • Reducing vCPU isn't done live on Windows

    Solved
    4
    0 Votes
    4 Posts
    285 Views
    olivierlambertO
    I wasn't even aware about this being a Windows limitation by itself
  • 1 Votes
    4 Posts
    318 Views
    dthenotD
    @samuelolavo Hello, Could the fact that this is a local LVM SR on a non-master host be relevant to how make_chain_rw is being handled? Yes, it's indeed what's happening. The check for the SRMaster (for a shared SR it's the master but for a local it's supposed to be done on the host directly) is failing and always saying False. I'll fix this. Thank you for the help
  • sr iso disconnect and crashed my hosts

    12
    0 Votes
    12 Posts
    3k Views
    H
    @olivierlambert We are still seeing similar issues on fully updated xcp-ng 8.3 host. We do reboot every time it happens. Is there anything we can do to fix this otherwise or prevent this from happening (beside manually disconnecting the cifs iso storage before the san goes for a reboot)?
  • `/run/sr-mount` parent directory created 0700 on some hosts, 0755 on others

    Unsolved
    4
    0 Votes
    4 Posts
    371 Views
    dthenotD
    @Dan Hello, So our investigation found that this change was introduced with commit https://github.com/xcp-ng/sm/commit/00637dd52e845d6016add9718fc9cc694aec9f0d It was aimed at EXTSR in particular, it appear that the first SR to be plugged is the one choosing the mode of sr-mount since util.makedirs also create the parent directory with the given mode. I have created a card for the issue on our side.
  • Nested virtualization - Prevent migration

    Unsolved
    1
    0 Votes
    1 Posts
    145 Views
    No one has replied
  • VM Display Resolution

    3
    0 Votes
    3 Posts
    357 Views
    poddingueP
    It was too tempting not to test, so I went and tested the other half. On an 8.3 host I set the preferred resolution to 800x600 in the OVMF menu on a UEFI Debian VM, turned that VM into a template, and cloned it. The clone came up at 800x600. A control clone of the same original, with nothing set, came up at 1024x768. So your workaround holds, the resolution really does ride along into VMs built from the template. For anyone who wants to poke at it, the setting is a UEFI variable called PlatformConfig under GUID 7235c51c-0c80-4cab-87ac-3b084a6304b1. It only appears in NVRAM once you commit it in the menu, and it stores width and height as plain little-endian integers, which is why it travels with the VM record. One thing I didn't expect: the OVMF help text says the mode list is filtered against video RAM size, but the VM I used had the default 4 MB and still offered everything up to 1280x1024. So you may not need to raise videoram for the common ones. Fair warning though, I measured the console at the firmware stage rather than after the distro's own driver takes over, so a guest that sets its own mode later could still override it. At least, that's my understanding.
  • Smart Reboot blocked in XO, and no Rolling Pool Update

    Unsolved
    9
    0 Votes
    9 Posts
    788 Views
    D
    @poddingue said: What I can't tell you is what set that particular combination on your VM in the first place. Does it ring a bell? I have no Idea. I had it on "Protect from accidental shutdown" but turned that off again, later. Doing this again (on, off) helped, as you said. Thank you so much!
  • VM autostart stopped working

    Unsolved
    8
    0 Votes
    8 Posts
    936 Views
    O
    @poddingue Thank you for the analysis. I'd give you a rep if I could
  • Sudden boot issues, emergency shell, root-lfgrma does not exist

    Solved boot dracut
    2
    0 Votes
    2 Posts
    254 Views
    S
    After a good sleep, I resolved half of my issue. I got my LSI Cards messed up, I accidentally hidan internal LSI3108 (Address 01:00.0) instead of the PCI Card LSI3008 (Address 05:00.0)... My Boot Drives run off of the internal card. From the fallback kernel, I was able to Modify /etc/grub-efi.cfg to remove the internal card form the hidden list. I now have a separate issue, but will make another post.
  • Autostart behaviour after upgrade 8.2 -> 8.3

    Solved
    6
    1
    0 Votes
    6 Posts
    627 Views
    poddingueP
    I put both of your questions on a spare host, because I couldn't answer either from memory. On colons: xe creates a key literally called auto_poweron:true with an empty value, so the entries you saw were three separate keys and none was the real auto_poweron, and typing false afterwards just made another one. It exits 0 and prints nothing every time, which I'd call a rough edge rather than a feature, though other-config is free-form by design so I don't know that the CLI is meant to validate keys at all. On the sleep: with rc.local executable and no sleep, it fired at 16 seconds of uptime and xe appliance-start came back with Error: Connection refused (calling connect ), exit 1, in under a tenth of a second. The VM stayed halted and nothing was reported anywhere, since rc.local has no terminal to print to. rc-local.service only orders after basic.target and network.target, nothing toolstack-related, while xapi-wait-init-complete.service took 30 seconds on that host, which is presumably why 60 was barely enough for you. There's an xapi-init-complete.target that looks like the right thing to order a unit against instead of guessing at a delay, though I haven't tried it so treat that as a lead rather than advice. The executable-bit half is in the docs now, it went onto the troubleshooting page after you reported it: https://docs.xcp-ng.org/troubleshooting/common-problems
  • 0 Votes
    5 Posts
    451 Views
    M
    Hard reboot sorted itself out
  • Get a price quote on a plan

    2
    0 Votes
    2 Posts
    266 Views
    DanpD
    Hi, I found your original request. I will make sure someone from the Sales team responds ASAP. Regards, Dan
  • CPU Usage of empty server

    Unsolved
    15
    3
    0 Votes
    15 Posts
    2k Views
    marcoiM
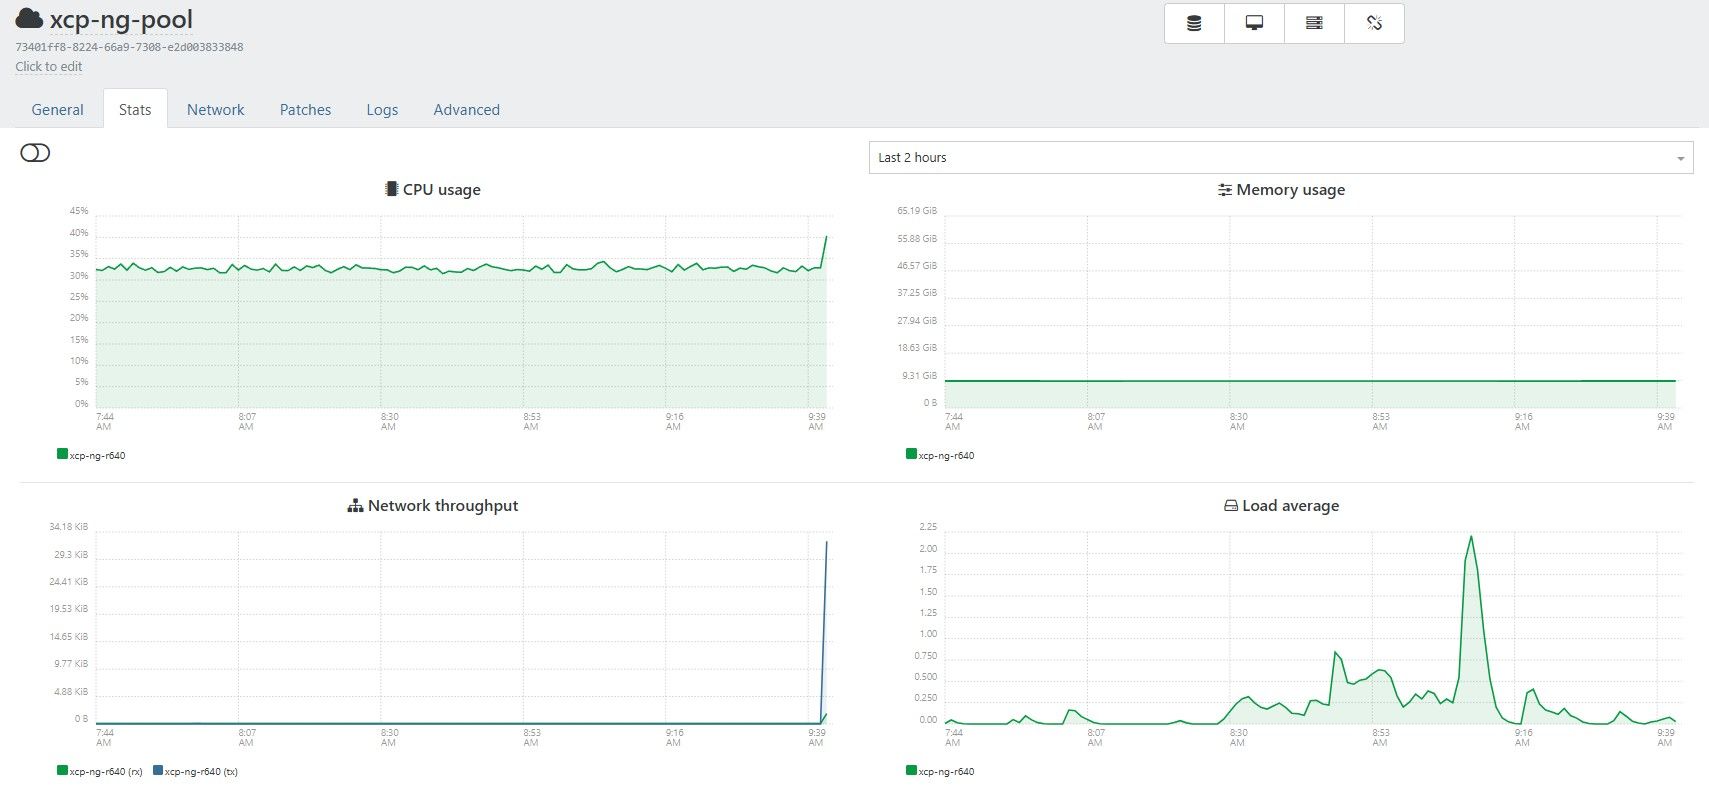
    i think im seeing the same with fake cpu spikes. I started a second pool yesterday to patch and left it on over night. typically i just shut it down once done so the servers dont get too far behind patching. Under the pool stats im seeing spikes but under hosts nothing. It doesnt really bother me, but figure i add to the thread that im also seeing it. [image: c75fecec-d618-4f05-a931-edea6bc6ecce-image.jpeg] [image: 1b9ea5aa-d349-4ff8-af89-30a970d36fbb-image.jpeg] [image: 0f579999-cd96-4216-a0d4-d637ea5febf1-image.jpeg]
  • The Lowest Priority Bug Ever? (/etc/udev/rules.d/z10-xen-vcpu-hotplug.rules)

    Unsolved
    10
    0 Votes
    10 Posts
    2k Views
    poddingueP
    Two PRs out of the lowest priority bug ever, that made my morning.