XenOrchestra not showing VM Disks on Pool (on single Server working) - XCP-ng Center is showing them
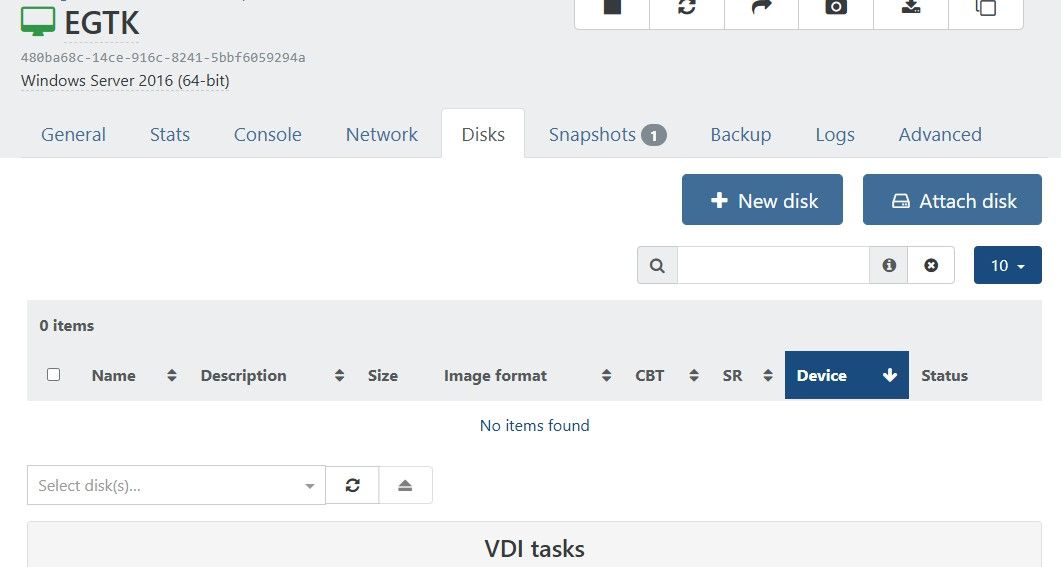
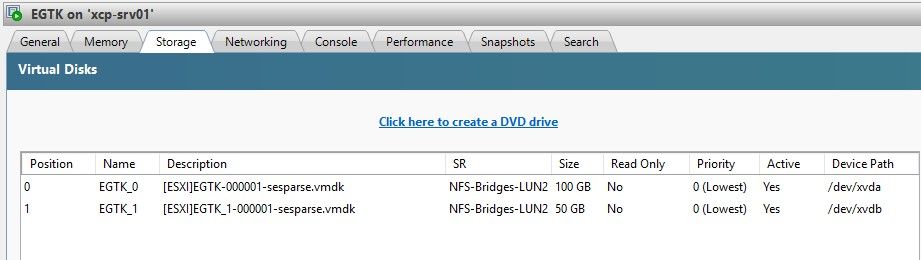
-
Thanx for your replies.
And sorry, i havent seen your first reply between my last posts with the link to your existing Thread.So, i think this is some kind of a bigger thing.
Will handle with care, but i have to leave for today.
Maybe i have time to test the snapshot and revert workarounds on the weekend.
But these are all production VMs.
Have to coordinate.
I have 2 NFS-SRs in the Pool.
Will try to migrate VMs from one to the other and see if this helps.Kind Regards and thx again
Alex -
Same problem here. But I noticed it only appears with the latest updates from XCP-ng 8.3. The log file shows me the following packages were updated / installed on my host:
May 07 19:44:54 Updated: xen-libs-4.17.6-6.2.xcpng8.3.x86_64
May 07 19:44:54 Updated: gnutls-3.3.29-10.2.xcpng8.3.x86_64
May 07 19:44:54 Updated: 1:net-snmp-libs-5.9.3-8.2.xcpng8.3.x86_64
May 07 19:44:54 Updated: ipmitool-1.8.19-11.2.xcpng8.3.x86_64
May 07 19:44:54 Updated: openssh-9.8p1-1.2.3.xcpng8.3.x86_64
May 07 19:44:54 Updated: openssh-clients-9.8p1-1.2.3.xcpng8.3.x86_64
May 07 19:44:54 Updated: openssh-server-9.8p1-1.2.3.xcpng8.3.x86_64
May 07 19:44:54 Updated: 1:net-snmp-agent-libs-5.9.3-8.2.xcpng8.3.x86_64
May 07 19:44:55 Updated: 1:net-snmp-5.9.3-8.2.xcpng8.3.x86_64
May 07 19:44:55 Updated: blktap-3.55.5-6.7.xcpng8.3.x86_64
May 07 19:44:55 Updated: message-switch-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:55 Updated: xcp-ng-xapi-plugins-1.16.0-1.xcpng8.3.noarch
May 07 19:44:55 Updated: xen-hypervisor-4.17.6-6.2.xcpng8.3.x86_64
May 07 19:44:55 Updated: xen-dom0-libs-4.17.6-6.2.xcpng8.3.x86_64
May 07 19:44:56 Updated: vhd-tool-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:56 Updated: squeezed-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:56 Updated: xen-tools-4.17.6-6.2.xcpng8.3.x86_64
May 07 19:44:56 Updated: xen-dom0-tools-4.17.6-6.2.xcpng8.3.x86_64
May 07 19:44:57 Updated: xcp-rrdd-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:57 Updated: xapi-tests-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:57 Updated: xo-lite-0.20.0-1.xcpng8.3.noarch
May 07 19:44:57 Updated: wsproxy-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:58 Updated: xapi-storage-script-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:58 Updated: xcp-networkd-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:59 Updated: forkexecd-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:59 Updated: sm-cli-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:44:59 Updated: xapi-rrd2csv-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:00 Updated: rrdd-plugins-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:01 Updated: xapi-nbd-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:01 Updated: sm-fairlock-3.2.12-17.8.xcpng8.3.x86_64
May 07 19:45:01 Updated: sm-3.2.12-17.8.xcpng8.3.x86_64
May 07 19:45:01 Updated: xenopsd-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:01 Updated: xenopsd-cli-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:02 Updated: xenopsd-xc-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:05 Updated: xcp-ng-pv-tools-8.3-17.xcpng8.3.noarch
May 07 19:45:05 Installed: 3:traceroute-2.1.5-2.xcpng8.3.x86_64
May 07 19:45:05 Updated: xapi-xe-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:05 Updated: qcow-stream-tool-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:08 Updated: xapi-core-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:08 Updated: xcp-ng-deps-8.3-14.noarch
May 07 19:45:08 Updated: gnutls-utils-3.3.29-10.2.xcpng8.3.x86_64
May 07 19:45:08 Updated: gnutls-devel-3.3.29-10.2.xcpng8.3.x86_64
May 07 19:45:09 Updated: varstored-guard-26.1.3-1.10.xcpng8.3.x86_64
May 07 19:45:12 Updated: kernel-4.19.19-8.0.46.2.xcpng8.3.x86_64So I guess one of these packages could be the culprit?
-
Another interesting observation. On a VM where we took a snapshot today (post Windows Update install) and deleted an older snapshot, the disk shows up (both v5 and v6).
-
Dug a little deeper. For a VM where the disks are not shown the following XO API call fails:
/rest/v0/vms/a519e879-3971-9210-51b6-7df14336e7b7/vdis
{
  "error": "no such VDI ac37700d-3157-4df7-b8e8-e1799a994591",
  "data": {
    "id": "ac37700d-3157-4df7-b8e8-e1799a994591",
    "type": [
      "VDI"
    ]
  }
}
Also the VDI cannot be retrieved over the XO API:
/rest/v0/vms/a519e879-3971-9210-51b6-7df14336e7b7
...
 "$VBDs": [
    "4ea8a3cd-0d1b-dc60-4d9c-fd70e060f06c",
    "9f4ca686-9fc2-35a9-c3e9-c871c9f68aba"
  ],
...
/rest/v0/vbds/9f4ca686-9fc2-35a9-c3e9-c871c9f68aba { "type": "VBD", "attached": false, "bootable": false, "device": "xvda", "is_cd_drive": false, "position": "0", "read_only": false, "VDI": "ac37700d-3157-4df7-b8e8-e1799a994591", "VM": "a519e879-3971-9210-51b6-7df14336e7b7", "id": "9f4ca686-9fc2-35a9-c3e9-c871c9f68aba", "uuid": "9f4ca686-9fc2-35a9-c3e9-c871c9f68aba", "$pool": "93d361b7-f549-53b7-a3aa-c9695bf0abe4", "$poolId": "93d361b7-f549-53b7-a3aa-c9695bf0abe4", "_xapiRef": "OpaqueRef:1d424d94-f540-2eb4-9e52-2a9b21ec0a19" }/rest/v0/vdis/ac37700d-3157-4df7-b8e8-e1799a994591 { "error": "no such VDI ac37700d-3157-4df7-b8e8-e1799a994591", "data": { "id": "ac37700d-3157-4df7-b8e8-e1799a994591", "type": "VDI" } }However the VDI can be listed using the xe cli:
$ xe vm-list uuid=a519e879-3971-9210-51b6-7df14336e7b7
uuid ( RO)           : a519e879-3971-9210-51b6-7df14336e7b7
     name-label ( RW): XXX
    power-state ( RO): halted
$ xe vbd-list vm-uuid=a519e879-3971-9210-51b6-7df14336e7b7 uuid ( RO) : 4ea8a3cd-0d1b-dc60-4d9c-fd70e060f06c vm-uuid ( RO): a519e879-3971-9210-51b6-7df14336e7b7 vm-name-label ( RO): XXX vdi-uuid ( RO): <not in database> empty ( RO): true device ( RO): xvdd uuid ( RO) : 9f4ca686-9fc2-35a9-c3e9-c871c9f68aba vm-uuid ( RO): a519e879-3971-9210-51b6-7df14336e7b7 vm-name-label ( RO): XXX vdi-uuid ( RO): ac37700d-3157-4df7-b8e8-e1799a994591 empty ( RO): false device ( RO): xvda$ xe vdi-list uuid=ac37700d-3157-4df7-b8e8-e1799a994591 uuid ( RO) : ac37700d-3157-4df7-b8e8-e1799a994591 name-label ( RW): XXX Disk 0 name-description ( RW): Created by XO sr-uuid ( RO): 977b7e63-bb84-57b2-3e0d-206afea553bf virtual-size ( RO): 34359738368 sharable ( RO): false read-only ( RO): falseSeems almost like something changed in the XCP-ng API which XO cannot consume.
-
Another confirmed data point, with package delta and the specific malformed field.
Host: XCP-ng 8.3.0, xapi 26.1 (build 26.1.4), Xen 4.17.6-9.
Setup: XO from sources (community). All VDIs vanished from the per-VM Disks tab (XO 5 and XO 6);
xeand the SR Disks tab show them fine; VMs run normally. Trigger was the 8.3 host update + reboot this morning — XO build unchanged since May 28, disks visible yesterday.Host update delta (today): all 26.1.3-1.10 → 26.1.4-3.1 (xapi-core, xenopsd, sm-cli, sm-fairlock, xapi-storage-script, vhd-tool, message-switch, etc.), plus sm 3.2.12-17.8 → 17.9 as an independent bump.
The malformed field. An affected live OS disk (VM running):
is-a-snapshot: false
snapshot-of:   <populated, points to another VDI>
snapshot-time: <populated>
A normal base VDI should have an empty
snapshot-of. After the update,snapshot-of/snapshot-timeare populated on real, non-snapshot base VDIs, and XO filters anything with a non-emptysnapshot-ofout of the per-VM Disks view — which is the disappearance.The VDI that
snapshot-ofpoints to is a legitimate base image in my environment (a heavily-reused Win2022 build template with a large genuine snapshot/clone lineage), so I can't tell from the host side whether the parentage links themselves changed or only thesnapshot-ofon live VDI labeling did. Either way, the consumer-visible effect is the same.REST confirms:
/rest/v0/vms/<uuid>/vdis→[]; /rest/v0/vdis/<uuid>→"no such VDI" for the VBD's referenced UUID, whilexe vdi-listshows it.Caution for others: since live disks now carry snapshot-like metadata, be careful with Health-dashboard "orphan" cleanup and snapshot deletion on affected VMs until this is understood.
Workaround that restored the per-VM Disks view: snapshot → revert → delete-snapshot (tested on a powered-off VM, immediate).
Happy to provide more diagnostics.
Quick Follow-up:
Additional symptom, same root cause: ISO-SR VDIs are also affected. Pre-existing ISOs disappeared from the XO ISO picker (only ISOs uploaded after the patch still show). An affected ISO's
vdi-param-listshows:is-a-snapshot: false snapshot-of: 937c3945-... (same anchor UUID as an affected VM disk on a different SR) snapshot-time: 19700101T00:00:00Z (Unix epoch — clearly synthetic)Notably the spurious
snapshot-ofon both an ISO VDI and an unrelated VM OS disk points to the same anchor UUID, with an epoch timestamp — so this looks like the update is stamping pre-existing VDIs with a bogussnapshot-ofrather than any real lineage. VHD chains/GC are clean (GC reports no work).Tagging a related GitHub Issue for easy correlation - https://github.com/vatesfr/xen-orchestra/issues/9578
-
@olivierlambert Any chance you can have someone please take a look at this thread? The issue persists and is creating problems for me. If someone out there has figured out the solution, kindly share, thanks.
-
Hi,
I think it's a known problem, let me ping @poddingue so he gives you a quick recap on the situation (or someone from the team storage)
-
@olivierlambert Thanks for the response, much appreciated.
I'm getting ready to file a bug report, as I noticed this morning that this issue is now causing a
VDI-IN-USEerror; preventing me from starting a VM. Fortunately, that VM isn't critical, so I want to report it and help with the troubleshooting that will lead to a fix before it spreads. -
Here's the short version: this looks like the known "VDIs show up as snapshots" bug, and you haven't done anything wrong.
What happens is a metadata flag on the VDI,is-a-snapshot, gets flipped to true after some of the recent 8.3 host updates, so XO (both 5 and 6) thinks those disks are snapshots and hides them from the per-VM Disks tab, even though the VDIs are fine andxe/ XCP-ng Center still show them.
A few older threads track the same thing, the main one is https://xcp-ng.org/forum/topic/11715/vdi-not-showing-in-xo-5-from-source . From what's said there, the fix is expected in two parts: stopping it from happening again, and a way to repair the flag on VDIs that are already affected.
I don't have a timeline and could be off on the details, so please don't take that as official.
In the meantime people have made the disks reappear by migrating the affected VDI to another SR, or snapshot then revert then delete the snapshot, but it's a visual fix and can come back.
The VDI_IN_USE you're now hitting on start does sound worth its own detailed report, so yes please file it with the xapi/sm versions and that malformedis-a-snapshotfield, and it'd be good to loop in @Team-Storage. Sorry you're stuck on this. -
@poddingue Thanks for the response. I got side tracked with another issue and didn't get that bug report filed, I'll do that as soon as possible.
It feels like I'm playing with a hand grenade...lol, quite scary!
-
@poddingue Bug report filed as requested — https://github.com/xcp-ng/xcp/issues/825 — and tagging @Team-Storage per your suggestion.
Full evidence bundle is attached to the issue (versions, sweep output,
vhd-utilvsxecomparison, SMlog). Summary of what I found:One correction to the mechanism, and I think it matters. The recap describes
is-a-snapshotbeing flipped totrue. On my system that isn't what's happening —is-a-snapshotisfalseon every affected VDI. The field being wrongly written issnapshot-of, which is getting populated on base disks that aren't snapshots at all. XO's disappearing-disks symptom is consistent with either (it filters on a non-emptysnapshot-of), but if the storage team is hunting for a badis-a-snapshotwrite, that may be the wrong field. Every affected VDI here looks like:is-a-snapshot: false <-- correct snapshot-of: <populated with an unrelated VDI's UUID> <-- wrongA VDI that is a snapshot of itself. The clearest single artifact:
uuid:          806f7f42-083f-4a40-b3f1-0700d00bab5a
name-label:    WinSrv2022SHB_Disk1_Data
is-a-snapshot: false
snapshot-of:   806f7f42-083f-4a40-b3f1-0700d00bab5a   <-- itself
snapshot-time: 20260709T11:19:15Z
sm-config:     vhd-parent: c86e3247-...   <-- bears no relation to the snapshot-of value
No valid code path produces
snapshot-of = self. Whatever writes this field isn't validating the target.It's still actively corrupting new VDIs — this is not just legacy damage. That self-referential VDI was created 2026-07-09, a week after my patch + reboot. Sweeps 9 days apart went from ~180 → 191 affected VDIs on one SR, and a fourth anchor UUID appeared that didn't exist in the first sweep. Newly created VHDs keep landing in the affected set. So "stop it happening again" is the urgent half of the two-part fix, at least in my case.
The bogus targets cluster onto a tiny anchor set, and the anchors point at each other:
Count Anchor 97 937c3945(→a893fdb4)50 a893fdb4(→ea150883)37 ea1508837 806f7f42(→ itself, new since Jul 9)That looks less like corrupted lineage and more like the field being filled from an incorrect/uninitialised source.
On-disk VHDs are completely healthy.
vhd-util checksays valid, parent locators are consistent, GC reports no work. The two VDIs the DB calls parent/child are, on disk, siblings under a common parent. The corruption is purely in the XAPI database — which is good news for recoverability.The
VDI_IN_USEis not a real lock.current-operationsis empty,xe task-listis empty, no tapdisk holds it.VM.startfails because it's walking a snapshot relationship that doesn't exist on disk. Reproduces fromxeon the pool master with XO entirely out of the path — which is why I filed againstxcp-ng/xcprather than the XO tracker.Versions: XCP-ng 8.3.0, xapi 26.1.11 (
xapi-core-26.1.11-1.2),sm-3.2.12-17.9,sm-fairlock-3.2.12-17.9, blktap 3.55.5-9.1, build20260618.I have not attempted to bulk-clear the fields — on-disk data is intact and I'd rather not do a mass write against the XAPI DB on a live SR without guidance. Backing store snapshotted as a safety net.
Happy to run whatever diagnostics would help. And +1 to the hand-grenade feeling — the affected set growing on its own is the part that worries me.
-
@kagbasi-wgsdac , thank you so much for the issue creation and the details, that will help for sure!

-
@poddingue You're most welcome, sir.
-
@poddingue Bug report filed as requested — https://github.com/xcp-ng/xcp/issues/825 — and tagging @Team-Storage per your suggestion.
Full evidence bundle is attached to the issue (versions, sweep output,
vhd-utilvsxecomparison, SMlog). Summary of what I found:One correction to the mechanism, and I think it matters. The recap describes
is-a-snapshotbeing flipped totrue. On my system that isn't what's happening —is-a-snapshotisfalseon every affected VDI. The field being wrongly written issnapshot-of, which is getting populated on base disks that aren't snapshots at all. XO's disappearing-disks symptom is consistent with either (it filters on a non-emptysnapshot-of), but if the storage team is hunting for a badis-a-snapshotwrite, that may be the wrong field. Every affected VDI here looks like:is-a-snapshot: false <-- correct snapshot-of: <populated with an unrelated VDI's UUID> <-- wrongA VDI that is a snapshot of itself. The clearest single artifact:
uuid:          806f7f42-083f-4a40-b3f1-0700d00bab5a
name-label:    WinSrv2022SHB_Disk1_Data
is-a-snapshot: false
snapshot-of:   806f7f42-083f-4a40-b3f1-0700d00bab5a   <-- itself
snapshot-time: 20260709T11:19:15Z
sm-config:     vhd-parent: c86e3247-...   <-- bears no relation to the snapshot-of value
No valid code path produces
snapshot-of = self. Whatever writes this field isn't validating the target.It's still actively corrupting new VDIs — this is not just legacy damage. That self-referential VDI was created 2026-07-09, a week after my patch + reboot. Sweeps 9 days apart went from ~180 → 191 affected VDIs on one SR, and a fourth anchor UUID appeared that didn't exist in the first sweep. Newly created VHDs keep landing in the affected set. So "stop it happening again" is the urgent half of the two-part fix, at least in my case.
The bogus targets cluster onto a tiny anchor set, and the anchors point at each other:
Count Anchor 97 937c3945(→a893fdb4)50 a893fdb4(→ea150883)37 ea1508837 806f7f42(→ itself, new since Jul 9)That looks less like corrupted lineage and more like the field being filled from an incorrect/uninitialised source.
On-disk VHDs are completely healthy.
vhd-util checksays valid, parent locators are consistent, GC reports no work. The two VDIs the DB calls parent/child are, on disk, siblings under a common parent. The corruption is purely in the XAPI database — which is good news for recoverability.The
VDI_IN_USEis not a real lock.current-operationsis empty,xe task-listis empty, no tapdisk holds it.VM.startfails because it's walking a snapshot relationship that doesn't exist on disk. Reproduces fromxeon the pool master with XO entirely out of the path — which is why I filed againstxcp-ng/xcprather than the XO tracker.Versions: XCP-ng 8.3.0, xapi 26.1.11 (
xapi-core-26.1.11-1.2),sm-3.2.12-17.9,sm-fairlock-3.2.12-17.9, blktap 3.55.5-9.1, build20260618.I have not attempted to bulk-clear the fields — on-disk data is intact and I'd rather not do a mass write against the XAPI DB on a live SR without guidance. Backing store snapshotted as a safety net.
Happy to run whatever diagnostics would help. And +1 to the hand-grenade feeling — the affected set growing on its own is the part that worries me.
Has this issue been validated on a storage server built around Debian 13, LVM and ext4 or just TrueNAS when connected to XCP-ng version 8.3.0. As part of the XAPI DB corruption. Can anyone answer this please or give a clue?
-
@john.c Unfortunately, I cannot answer your question in the affirmative. I only use XCP-ng with TrueNAS.
@Team-Storage have y'all had a chance to take a look at the bug report I filed? This issue is quite serious.
-
@john.c See this post - https://xcp-ng.org/forum/post/105564
-
The July updates batch that went out on 28 July carries
xapi-26.1.11-1.3.xcpng8.3, and @kagbasi-wgsdac has since confirmed on https://github.com/xcp-ng/xcp/issues/825 that three days after patching his disks are all visible again and reverting a snapshot no longer duplicates VDIs.
The blog entry for that batch names the fix as non-snapshotted VBDs staying attached afterVM.revert, a regression fromxapi-26.1.4-3.3: https://xcp-ng.org/blog/2026/07/28/july-2026-updates-1-for-xcp-ng-8-3-lts/. Host reboots are needed. That stops new damage, but it does not unstamp VDIs that were already hit, so if disks are still hidden after you patch you probably still want the repair script at https://xcp-ng.org/forum/post/105564.
My post above also had the mechanism wrong, and @kagbasi-wgsdac corrected it: the field being wrongly written issnapshot-ofon base disks, notis-a-snapshot.
If anyone is still watching disks disappear on a fully updated pool, please say so here, because that would be something new rather than the tail of this one. -
I'm seeing a recurrence of the snapshot_of / hidden-disks issue after patching to
xapi-26.1.16-1.2(both hosts, rebooted). Unusual element this time:snapshot-fixer.py dry-runflags ~260 VDIs across the SR that all cite a singleOpaqueRefwhich resolves to no VDI (xe vdi-list | grep <ref>returns nothing). Holding off on rewrite until I understand whether that single-dangling-ref pattern is safe, given the set appears to include base VDIs of legitimate snapshots.Full technical detail and questions posted on GitHub: https://github.com/xcp-ng/xcp/issues/844.
-
 P poddingue marked this topic as a question
-
Apologies for the long silence on my end — real life got in the way and I couldn't dig into this for a while. Finally found the time now to go through it again properly, helped a lot by the details others have already posted here in the meantime.
I don't think this adds a new root cause, but it does corroborate what @kagbasi-wgsdac described — same "mass collapse onto a single anchor UUID" pattern, and in my case too that anchor is a real, still-in-use base disk, not a dangling/non-existent OpaqueRef (referencing vatesfr/xen-orchestra#9578).
Environment: 2-host pool, shared NFS SR, XO recently updated to the latest version (didn't change anything regarding this issue, as expected since it's XAPI-side).
Ran a read-only xe vdi-list params=uuid,name-label,is-a-snapshot,snapshot-of,snapshot-time directly against the pool master. Result: 47 of 196 VDIs match the pattern (is-a-snapshot: false but snapshot-of populated). All 47 point to the exact same single anchor UUID — which resolves to one specific, actively-used base VDI, not a missing reference.
snapshot-time on most affected VDIs is the epoch default (1970-01-01T00:00:00Z), but a handful show plausible real dates (e.g. late 2025 / early 2026) — suggesting those entries originally had a legitimate snapshot-of relationship that got overwritten by whatever corrupted the metadata.
Currently-running VMs affected (100% of each VM's disks affected in every case):
VM OS Disks Sizes VM-1 Windows Server 2016 1 50 GB VM-2 Windows Server 2016 3 50 / 200 / 450 GB VM-3 Windows Server 2019 3 100 / 100 / 100 GB VM-4 Windows 11 Pro 2 50 / 100 GB VM-5 (decommissioned) Windows Server 2016 2 100 / 50 GB VM-6 Ubuntu 24.04 2 10 / 10 GB VM-7 Ubuntu 24.04 2 10 / 10 GB VM-8 Windows Server 2025 3 25 / 25 / 64 GB VM-9 Ubuntu 24.04 2 10 / 10 GB On top of that, ~28 more affected VDIs are orphaned/unattached objects ("base copy" leftovers, old ISO references) — same pattern, no VBD attached.
Not touching any of this (no snapshot-fixer.py, no manual vdi-param-set) given the risk of severing legitimate snapshot relationships that's already been flagged here. Happy to provide a full anonymized xe vdi-list dump if that's useful for tracking down the root cause.
Big thanks to everyone who kept digging into this and shared their findings here — especially @kagbasi-wgsdac for the detailed write-up that pointed me in the right direction, and of course @poddingue and the whole Vates team for staying on top of this and keeping us updated despite no clear timeline yet. Really appreciate the effort that goes into this, especially for something as tricky as a metadata corruption bug across production pools.
Kind Regards and thx again
Alex
Hello! It looks like you're interested in this conversation, but you don't have an account yet.
Getting fed up of having to scroll through the same posts each visit? When you register for an account, you'll always come back to exactly where you were before, and choose to be notified of new replies (either via email, or push notification). You'll also be able to save bookmarks and upvote posts to show your appreciation to other community members.
With your input, this post could be even better 💗
Register Login