• 1 Votes
    4 Posts
    169 Views
    Bastien NolletB
    Here's the fix, which should be merged in the following days/weeks, and should be in the next XO release: https://github.com/vatesfr/xen-orchestra/pull/10809
  • 9 Votes
    46 Posts
    18k Views
    bvitnikB
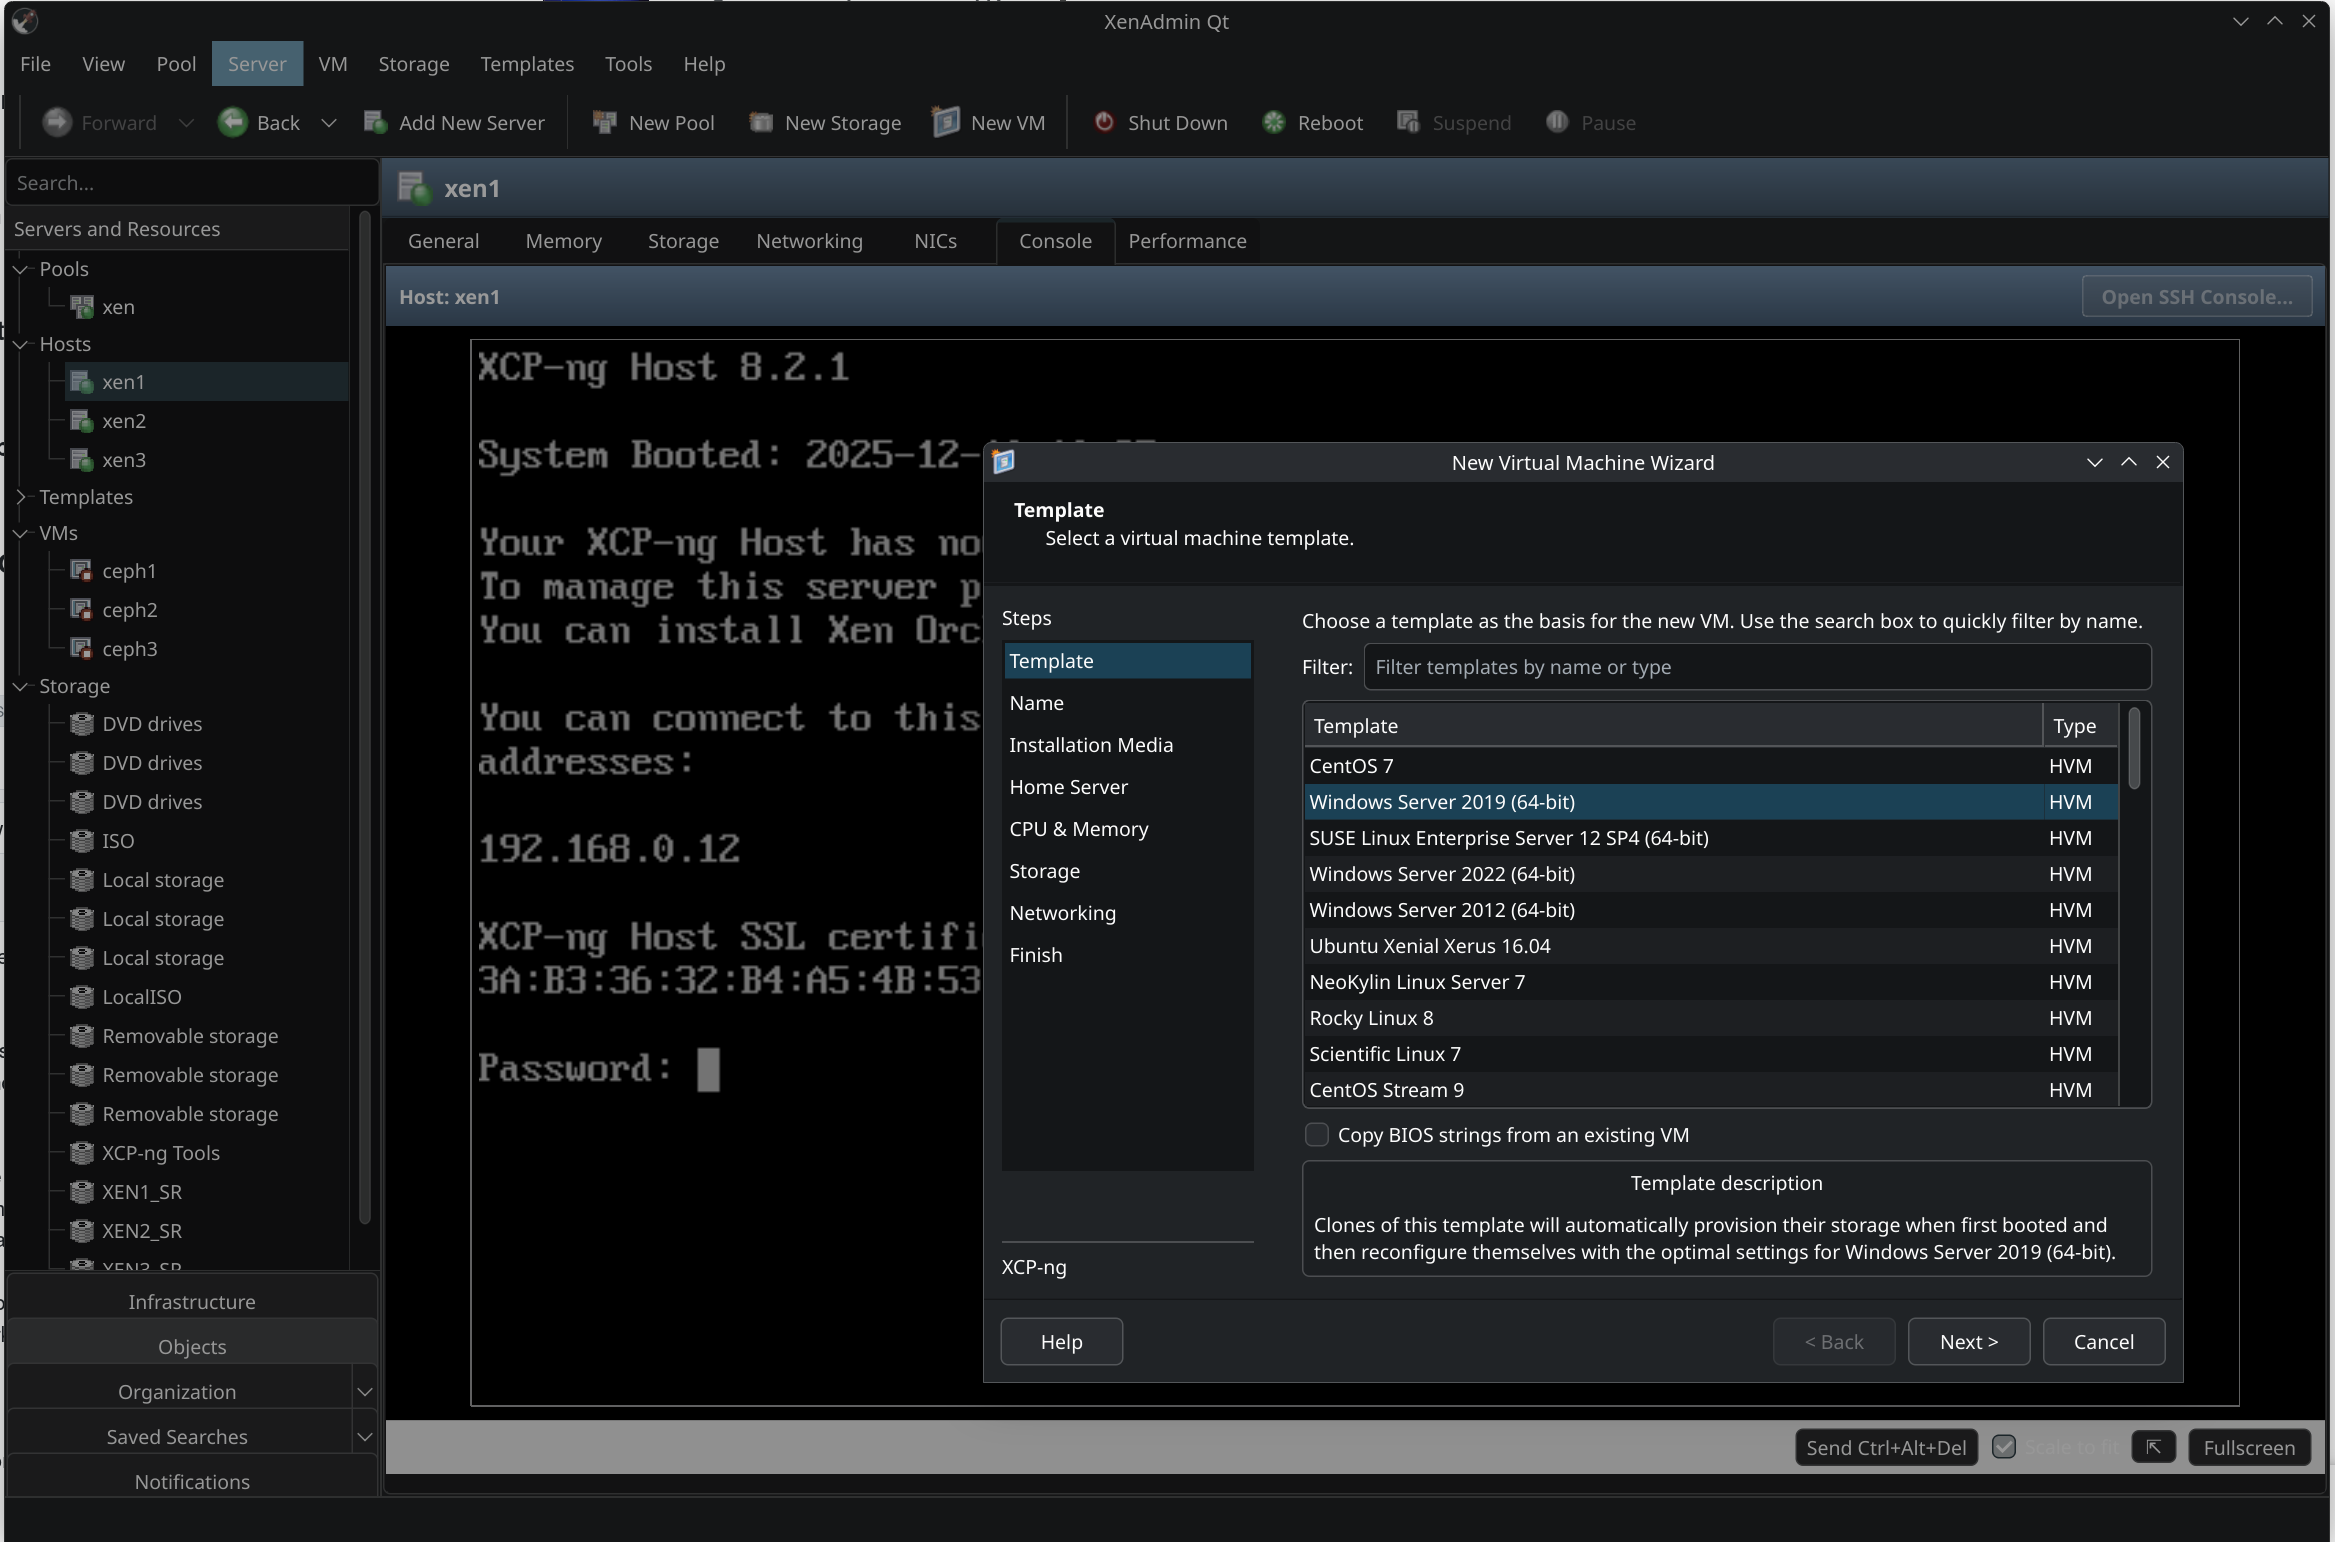
    @benapetr One of the things I've noticed during my initial testing is that there is a problem in how VM templates are handled compared to xenadmin. Here are my observations: Built in templates are shown with yellow icons in the tree view (if enabled with View -> Templates) and this seems to work as expected. User made templates are also shown with yellow icon in the tree view which is wrong. They should be shown with blue icon and sorted before any built in templates. VM snapshots are shown as VM templates with blue icons in the tree view. They should not be shown at all in the tree view. Additionally, they are shown under a host instead of a pool compared to other templates. New VM dialog does not show VM template icons at all so it is hard to distinguish if they are builtin or user created or snapshots (which can be used as VM templates too). Snapshots are not shown in the list at all. New VM dialog also does not sort the templates by name nor group per type (builtin, user, snapshot) so it is hard to find what you need. If I get some extra time, I will add some screenshots for comparison.
  • Backup failures after VHD to QCOW2 conversion

    Unsolved Backup
    7
    0 Votes
    7 Posts
    345 Views
    S
    Hi everyone Here are the logs (anonymized) for one complete backup run. Thanks for taking a look!
  • New 9.2.445 XCP Windows tools Roll Back

    Management
    3
    0 Votes
    3 Posts
    157 Views
    B
    Looks like the tools installation had an issue with Windows Update packages, the windows event log started throwing error relating to the cryptsvc service and C:\Windows\System32\catroot2 at the time I ran XenClean before trying to install 9.2445. Rebuilding Catroot resolved the issue and tools installed fine. net stop cryptsvc ren C:\Windows\System32\catroot2 catroot2.old net start cryptsvc Reboot Appears to be isolated to this single VM
  • 0 Votes
    12 Posts
    6k Views
    olivierlambertO
    Hi @odmsys It's on the roadmap and it won't wait for SMAPIv3. I truly hope we can bring something in a matter of few months, at least to have it to test
  • Native Ceph RBD SM driver for XCP-ng

    Development
    43
    3 Votes
    43 Posts
    12k Views
    A
    @dicode-nl Thank you for the code. I'm in testing now with ceph 20.2.5 and so far I haven't had any issues.
  • 0 Votes
    4 Posts
    221 Views
    R
    Hi, as promised, here are the log excerpts from the incident, in case they help the @Team-Storage folks (or anyone hitting the same thing). All times are CET (host time). VM dd25471a-fbd3-2b0c-df4c-b8182546f6a8, SR 1a97f391-…, migration task R:4fa24c2fefb3 (beta → gamma). 1. The failed attach (SMlog on gamma) The SR lock is acquired at 23:00:04 and the exception comes 6s later: Nov 10 23:00:04 gamma SM: [11963] lock: acquired /var/lock/sm/1a97f391-c733-8520-62c3-2f3847235a36/sr Nov 10 23:00:10 gamma SM: [11963] Raising exception [47, The SR is not available [opterr=Error: ERRO:NoneType]] Nov 10 23:00:10 gamma SM: [11963] ***** generic exception: vdi_attach: EXCEPTION <class 'xs_errors.SROSError'>, The SR is not available [opterr=Error: ERRO:NoneType] File "/opt/xensource/sm/SRCommand.py", line 157, in _run_locked target = sr.vdi(self.vdi_uuid) File "/opt/xensource/sm/LinstorSR", line 549, in wrap return load(self, *args, **kwargs) File "/opt/xensource/sm/LinstorSR", line 479, in load raise xs_errors.XenError('SRUnavailable', opterr=str(e)) One second later the same SR answers normally, which is why I think the failure was transient: Nov 10 23:00:11 gamma SM: [12120] Failed to join node(s): {'gamma', 'alpha'} Nov 10 23:00:11 gamma SM: [12120] Synchronize metadata... Nov 10 23:00:11 gamma SM: [12120] VDI c90eeb92-... loaded! (path=/dev/drbd/by-res/xcp-persistent-ha-statefile/0, hidden=0) 2. LINSTOR side (controller on beta) Three error reports between 22:59 and 23:00, all identical: ERROR REPORT 6AF3924C-00000-000001 (also -000002 and -000003) Version: 1.33.1 Node: beta Class name: com.linbit.linstor.netcom.PeerClosingConnectionException Generated at: Method 'connectionClosing', Source file 'TcpConnectorPeer.java', Line #627 *__checkpoint ⇢ Fetch thin capacity info 3. How it surfaces in xapi gamma xapi: [error|VDI.attach2] sm_exec failed with exception Storage_error ([S(Backend_error);[S(SR_BACKEND_FAILURE_47);[S();S(The SR is not available [opterr=Error: ERRO:NoneType]);S()]]]) gamma xapi: [error|Async.VM.pool_migrate R:4fa24c2fefb3|Storage_smapiv1_wrapper] dp:vbd/1/xvda sr:1a97f391-... vdi:60342e65-... op:attach(RW) error:Storage_error (...SR_BACKEND_FAILURE_47...) 4. The cleanup on the source also fails (beta) 23:00:10 beta xenopsd-xc: [error|71|Async.VM.pool_migrate R:4fa24c2fefb3|xenops_server] VM.migrate: Failed during Synchronisation point 4. msg: Xenops_interface.Xenopsd_error([S(Storage_backend_error);[S(SR_BACKEND_FAILURE_47);...]]) 23:00:10 beta xenopsd-xc: [error|71|...|task_server] Task 101 failed; Xenopsd_error([S(Does_not_exist);[S(VM);S(dd25471a-.../config)]]) 23:00:10 beta xenopsd-xc: [error|71|...|xenops_server] Triggering cleanup actions failed: Xenopsd_error([S(Does_not_exist);[S(VM);S(dd25471a-.../config)]]) So after the migration error, the cleanup fails too because the VM config is no longer in xenopsd on the source. That matches what I saw afterwards: XAPI says running on beta, but xenopsd doesn't know the VM. 5. What is left on the destination (gamma) The temporary extra/ entry is created at 22:58:09 and renamed to the final uuid at 23:00:03, i.e. before the attach fails at 23:00:10. Nothing removes it afterwards: 22:58:09 gamma xenopsd-xc: [debug|Async.VM.pool_migrate R:4fa24c2fefb3|xenops_utils] TypedTable: Writing extra/dd25471a-fbd3-2b0c-df4c-000000000001 23:00:03 gamma xenopsd-xc: [debug|13|Async.VM.pool_migrate R:4fa24c2fefb3|xenops_utils] TypedTable: Renaming extra/dd25471a-fbd3-2b0c-df4c-000000000001 -> extra/dd25471a-fbd3-2b0c-df4c-b8182546f6a8 6. What the following RPU runs report in XO 2nd run (00:03, VM still in that state): END failure Evacuate INTERNAL_ERROR(Object with type VM and id dd25471a-fbd3-2b0c-df4c-b8182546f6a8/config does not exist in xenopsd) END failure Rolling pool update INTERNAL_ERROR(Object with type VM and id dd25471a-.../config does not exist in xenopsd) 3rd run (00:11–00:14, after I had recovered the VM on beta only): END failure Evacuate INTERNAL_ERROR(xenopsd internal error: VM.migrate: Failed during Synchronisation point 4. msg: Xenops_interface.Xenopsd_error([S(Already_exists);[S(extra);S(extra/dd25471a-fbd3-2b0c-df4c-b8182546f6a8)]])) And on gamma for that run: 00:13:42 gamma xenopsd-xc: [debug|94|Async.VM.pool_migrate R:005a41ca1c30|xenops_utils] Key extra/dd25471a-fbd3-2b0c-df4c-b8182546f6a8 already exists 00:13:42 gamma xenopsd-xc: [error|94|...|backtrace] Raised Xenopsd_error([S(Already_exists);[S(extra);S(extra/dd25471a-fbd3-2b0c-df4c-b8182546f6a8)]]) 00:13:42 gamma xenopsd-xc: [debug|94|...|xenops_server] Caught Xenopsd_error([S(Already_exists);...]): cleaning up VM state Also at 00:14:03, opening the VM console from XO fails on beta with the same Does_not_exist … /config error. What the logs show A single transient LINSTOR controller error (ERRO:NoneType) appears to trigger the failure vdi_attach with no retry. That failure at sync point 4 leaves state on both hosts: on the source the cleanup fails with Does_not_exist …/config, and on the destination the extra/<uuid> entry stays. Subsequent RPU runs then trips on that leftover (first Does_not_exist, then Already_exists), so it can't recover by itself and requires manual recovery on both hosts. I still have the full xensource.log, SMlog and ErrorReport files for that window if someone needs more. Thanks!
  • XCP-ng 8.3 updates announcements and testing

    Pinned News
    802
    1 Votes
    802 Posts
    1m Views
    R
    Thank you, @stormi , I'm happy to know that xcp-ng.repo is not touched. These three hosts haven't been rebuilt or restored recently, no hosts have been added, and I did have to make the above modification on each one of them to get them to work. I suppose it's possible I missed the step to remove "mirrors.xcp-ng.org" from xcp-ng.repo during the initial pool build about a year ago and it's just somehow been working with our outbound Internet proxy. In any event, having "mirrors.xcp-ng.org" in our xcp-ng.repo file has definitely caused us problems in the past with our proxy setup. TGIF/DMCV!
  • 🛰️ XO 6: dedicated thread for all your feedback!

    Pinned Xen Orchestra
    326
    7 Votes
    326 Posts
    224k Views
    G
    I've noticed something that's confusing. In the Tasks tab one of my backup jobs suggests that it is only 1% done, when you expand that task then you can see that both parts are complete. Image for reference: [image: XO6backup.png] I'm guessing that if I nested other jobs, they would also display like this. I don't nest any other jobs because I want to make sure one finishes before another starts, and I don't have many VMs that I'm backing up (I don't have many VMs total). I'd request that if all nested jobs were complete, we get a full circle with 100% or just another green check mark.
  • Full backup failure when upgrading XOce

    Unsolved Backup
    2
    0 Votes
    2 Posts
    75 Views
    J
    @ph7 Thanks for sharing info. Maybe it will help someone
  • XCP-ng Windows PV tools announcements

    Moved News
    119
    0 Votes
    119 Posts
    65k Views
    J
    @Mitchel-APD Thank you! That might acctually help me quite a bit... I have been having trouble getting my ansible-instances to recover from the VM re-initiating the network connection! Perhaps this could be helpfull. I will absolutely test it
  • MFA for console access

    Unsolved XCP-ng
    1
    0 Votes
    1 Posts
    91 Views
    No one has replied
  • 0 Votes
    15 Posts
    669 Views
    F
    @acebmxer that is exactley what i was saying before. if you disable the remote before nas shutdown you are good on the XO side and will work indefinitely, but if you don't execute umount -l /run/xo-server/mounts/2ab02323-0d47-43a5-9081-b2454e036c70 you will have the mount stuck on the os side. You will be able to reboot XO vm eventually but you will have to wait for a long timeout during XO shutdown. if you want to simulate my issue just disable the remote 5 minutes after shutting down the synology, get the pid from service xo-server status then ps -T pid after a while you'll have 4 "rpc_wait_bit_killable" and XO will stop responding
  • Disk import not happens

    Unsolved Management
    5
    0 Votes
    5 Posts
    211 Views
    Tristis OrisT
    error via reverse proxy. Uncaught Error: Body is not a JSON, original message is : <html> <title>500 Internal Server Error</title> <style>html{color-scheme:light dark;}</style> </head> <body> <center><h1>500 Internal Server Error</h1></center> <hr><center>Angie</center> </body> </html> pr index.js:2564 me index.js:4029 i index.js:4029 promise callback*me index.js:4029 i index.js:4029 promise callback*me index.js:4029 i index.js:4029 promise callback*me index.js:4029 i index.js:4029 be index.js:4029 be index.js:4029 dr index.js:2531 importDisks index.js:2575 Lodash 2 importDisks index.js:2574 e index.js:113 P index.js:22 i index.js:22 R index.js:22 R index.js:22 import index.js:121 t factory.js:307 o factory.js:331 e action-button.js:93 m action-button.js:10 i action-button.js:10 _execute action-button.js:10 _execute action-button.js:10 _execute action-button.js:10 v action-button.js:140 componentDidMount action-button.js:147 React 14 componentWillUnmount factory.js:125 f factory.js:31 _dispatch factory.js:158 t factory.js:322 promise callback*t factory.js:313 o factory.js:331 value index.js:206 promise callback*value index.js:174 React 5
  • Booting Homeassistant (HAOS) Image breaks VM

    Unsolved Compute
    5
    0 Votes
    5 Posts
    402 Views
    C
    @IgorGlock What do you mean by "okay"? Backing up the VM with Commvault or...?
  • Rolling pool update

    Xen Orchestra
    13
    0 Votes
    13 Posts
    597 Views
    J
    @tjkreidl said: @john.c Note that a two-host pool running HA can run into the split-brain issue if one of the hosts fails; it's highly recommended to have at least three hosts in an HA pool (or look into HA-Lizard if running a pool with two hosts and HA). Right but also considering the in development Twinstor for when it goes stable and in production!
  • 4 Votes
    3 Posts
    947 Views
    J
    @vmpr Popping it behind an instance of BunkerWeb (https://www.bunkerweb.io/) or similar, with Xen Orchestra on a new IP address would help. As BunkerWeb is what’s known as a Web Application Firewall. It will help to protect your instance of Xen Orchestra, especially if you change the IP address of the appliance, and only give that friend the one that goes through BunkerWeb. As always don’t expose Xen Orchestra to the Internet, but if it’s absolutely necessary always use something like BunkerWeb (with BunkerNET) and only provide the BunkerWeb based IP address! Also run a check on all of your hosts and may be best to roll them a fresh (in case there’s an Advanced Persistent Threat). As well as a fresh instance of Xen Orchestra, and maybe encourage your friend while also doing yourself to start using hardware security keys, preferably ones that support biometrics and PINs. Alternatively other secure enclaves with cryptographic credentials held there. Additionally opt into the new encrypted datastore for Xen Orchestra on the new fresh Xen Orchestra and XCP-ng. Also make sure it’s completely up to date! Also if the hosts support it ensure that Intel TME or similar is enabled on the fresh installs of XCP-ng. Finally rotate all passwords associated with that system, including your Vates account password, especially if it’s linked to the Xen Orchestra instance hit.
  • 0 Votes
    20 Posts
    2k Views
    nathanael-hN
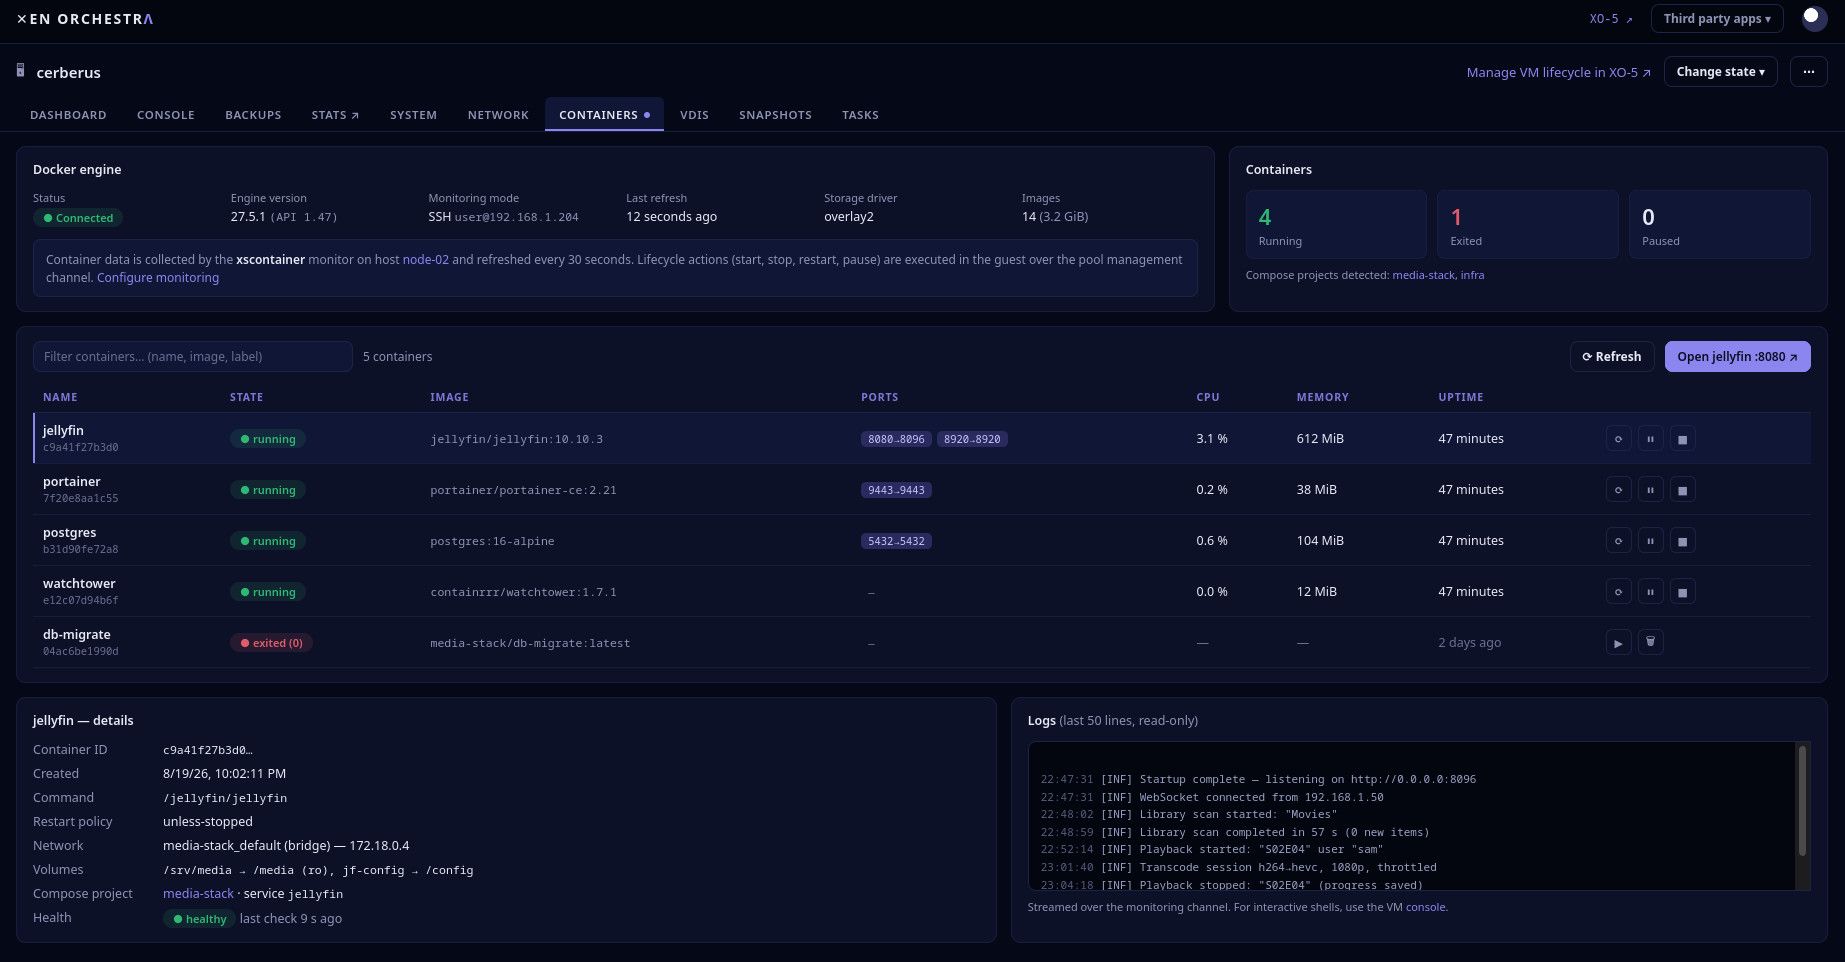
    @jr-m4 I did not took time to test Podman yet. But we expect this to work. You'd have to expose a socket, like the docker daemon does. Probably systemctl enable --now podman.socket would be enough. More in this page https://docs.redhat.com/en/documentation/red_hat_enterprise_linux/8/html/building_running_and_managing_containers/using-the-container-tools-api and this one https://docs.podman.io/en/latest/markdown/podman-system-service.1.html
  • 0 Votes
    5 Posts
    540 Views
    I
    @gudge25 check these https://docs.xcp-ng.org/vms/#enabling-viridian-extensions and https://lazyadmin.nl/it/september-2026-update-break-rds-how-to-fix/
  • XOSTOR hyperconvergence preview

    Pinned Moved XOSTOR
    471
    1
    6 Votes
    471 Posts
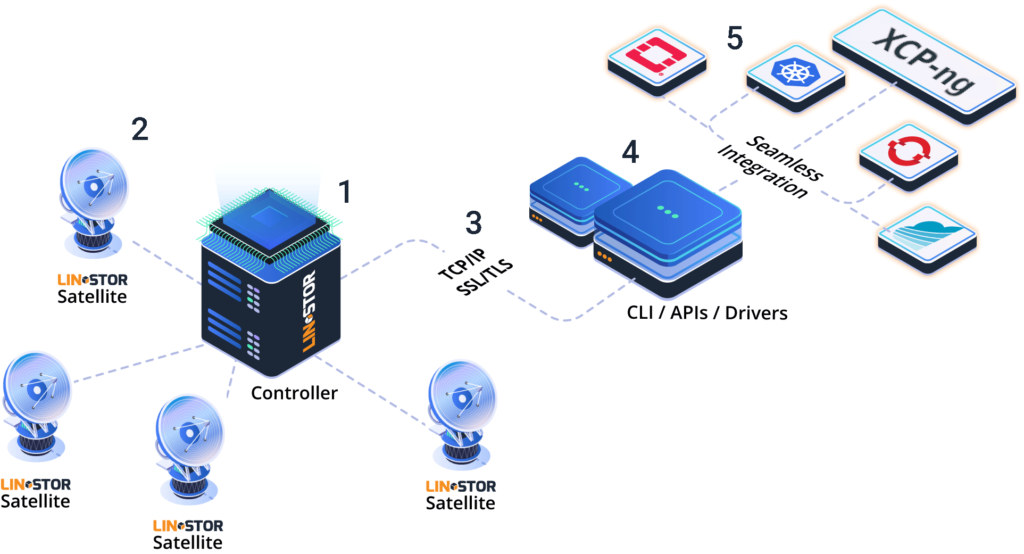
    1m Views
    Maelstrom96M
    @dthenot For anyone stuck, here is what I ended up doing: I've manually hardcoded the controller_uri in /opt/xensource/sm/linstorvolumemanager.py on the new host, restarted the toolstack using xe-toolstack-restart and ran the xe host-call-plugin host-uuid=NEW_HOST_UUID plugin=linstor-manager fn=addHost args:groupName=linstor_group/thin_device command. def _get_controller_uri() -> str: # TODO: Check that an IP address from the current pool is returned. #addresses = _get_controller_addresses() return "linstor://10.25.254.100" #return "linstor://" + addresses[0] if addresses else "" After that, you should see the addHost command return True. It should be safe to revert the change to the _get_controller_uri() function and restart to make sure everything starts properly. [10:06 van3-pprod-xen01 ~]# linstor --controllers 10.25.254.100 node l ╭───────────────────────────────────────────────────────────────────╮ ┊ Node ┊ NodeType ┊ Addresses ┊ State ┊ ╞═══════════════════════════════════════════════════════════════════╡ ┊ van3-pprod-xen01 ┊ COMBINED ┊ 10.25.254.100:3366 (PLAIN) ┊ Online ┊ ┊ van3-pprod-xen02 ┊ COMBINED ┊ 10.25.254.101:3366 (PLAIN) ┊ Online ┊ ┊ van3-pprod-xen03 ┊ COMBINED ┊ 10.25.254.102:3366 (PLAIN) ┊ Online ┊ ┊ van3-pprod-xen04 ┊ COMBINED ┊ 10.25.254.103:3366 (PLAIN) ┊ Online ┊ ╰───────────────────────────────────────────────────────────────────╯ [10:06 van3-pprod-xen01 ~]# xe host-call-plugin host-uuid=f9d94f6c-e826-452f-b9b9-638550b209cf plugin=linstor-manager fn=addHost args:groupName=linstor_group/thin_device True [10:08 van3-pprod-xen01 ~]# linstor --controllers 10.25.254.100 node l ╭───────────────────────────────────────────────────────────────────╮ ┊ Node ┊ NodeType ┊ Addresses ┊ State ┊ ╞═══════════════════════════════════════════════════════════════════╡ ┊ van3-pprod-xen01 ┊ COMBINED ┊ 10.25.254.100:3366 (PLAIN) ┊ Online ┊ ┊ van3-pprod-xen02 ┊ COMBINED ┊ 10.25.254.101:3366 (PLAIN) ┊ Online ┊ ┊ van3-pprod-xen03 ┊ COMBINED ┊ 10.25.254.102:3366 (PLAIN) ┊ Online ┊ ┊ van3-pprod-xen04 ┊ COMBINED ┊ 10.25.254.103:3366 (PLAIN) ┊ Online ┊ ┊ van3-pprod-xen05 ┊ COMBINED ┊ 10.25.254.104:3366 (PLAIN) ┊ Online ┊ ╰───────────────────────────────────────────────────────────────────╯