Installed on 3xDell PowerEdge R350 in HA. And so far, I haven't noticed anything out of the ordinary.
J
Offline
Posts
-
RE: XCP-ng 8.3 updates announcements and testing
-
RE: Building from source, now introduces local changes in typed-router.d.ts?
I noticed you merged https://github.com/vatesfr/xen-orchestra/pull/9787
I just tried it. And it does seem to fix my original issue!
Thank you! I am always impressed by you guys. Making testing and reporting upstream (to you guys) a good experience!
-
RE: Backblaze as Remote error Unsupported header 'x-amz-checksum-mode' received for this API call.
I submitted this as a GitHub issue last week.
TL;DR: Backblaze aparently doesn't support those flags that are enabled by default
"Backblaze does not yet accept these headers, so we recommend downgrading to AWS Javascript 3.x SDK version 3.728.0." -
RE: Enable Maintenance Mode = Host Not Enough Memory
@poddingue
Our HA-pool is a 3 host system, yes.I'll add a note about our plans to go paid in that feedback-item. Thanks for the tip.
In the meantime, I'm testing and reporting as much as I can. In order to hopefully help the product be better for all.Cheers!
-
RE: Enable Maintenance Mode = Host Not Enough Memory
Huh.. Good catch.
I set all of the VMs torestart, and now it does make maintenance mode possible, on the host.However, when we go into licensed/paid production (soon tm). It would be an absolute nightmare to try and find one VM that might not be on the right HA-plan... And it does kind of feel that Maintenance-mode should be compatible with whatever HA-plan is chosen regardless.
Perhaps there could be a way to assign a global/pool-wide HA-plan along with enabling HA alltogether?
Update: Shining light on that there is already a feedback-item, wishing for this kind of mass-operation for HA.
https://feedback.vates.tech/posts/45/bulk-operation-for-setting-vm-ha-option -
RE: [V2V] Without VDDK problems
Thanks for a fantasticly quick answer, and detailed as well. I will test this immediately!
Update:
I can confirm that this was indeed the problem! -
RE: Support for newer Emulex LPe37xxx amd LPe36xxx Fiber channel adapters on XCP-ng 8.3 - your testing is needed
@jr-m4 thank you so much for testing this updated driver.
Just to make sure, I understand now that you confirm the driver is working as expected and the issues you had were not related to it? Or are there any problems still with this new driver?
Many thanks again for spending the time to test and report.
Hi
Yes. I believe I was chasing a red herring of my own doing. I have not found anything actually problematic with this driver at all.
-
RE: XCP-ng 8.3 updates announcements and testing
3 pools updated. RPU went fine, where one is HA. A couple of test-backups went fine as well.
-
RE: XCP-ng 8.3 updates announcements and testing
Updated both test-pools:
old-xcp-dev&new-xcp-devBackups seem to be working fine. But I'm noticing some warnings now (See below). However, these can very well be the result of clumsy and crude troubleshooting with fixing the previous test-release symptoms.
Dashboard/Health doesn't report any issues. And I'm not seing issues with the VMs in their running state.
Backups are seemingly clearing HealthChecks as well.I will update this post in a living matter. So to not spam the forum-thread with many small posts.
Symptom 1:
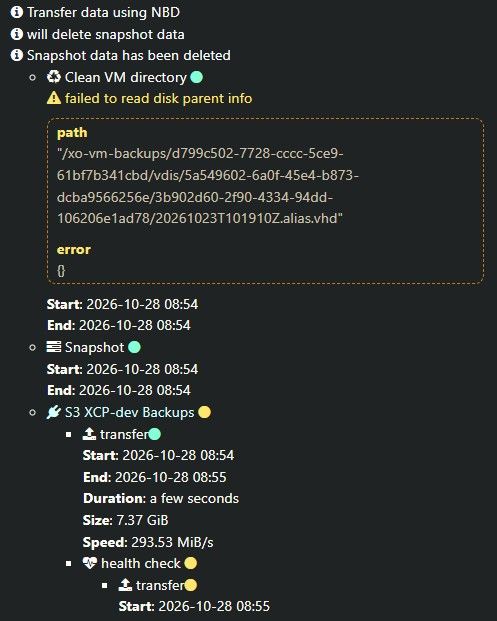
Update 1:
So the only way I could "solve" the issue, was to delete all of the backups for the VM in question. Afterwards it started behaving as expected. I haven't found anything else problematic so far. -
RE: XCP-ng 8.3 updates announcements and testing
@flakpyro Hello,
It would be preferred to use another method.
You can use theresetvdis.pyscript in the/opt/xensource/sm/to reset values instead,
usingvdi-forgetis unadvised in this case, it can cause issues by losing information that are stored in XAPI about VDIs./opt/xensource/sm/resetvdis.py single <VDI UUID>I was just about to look at maybe doing what @flakpyro suggested. More likely I would've just restored from backup. As this is dev-instances, and non-important.
But your
resetvdis.pysuggestion solved it entirely! Thanks for the quick tip! -
RE: XCP-ng 8.3 updates announcements and testing
Updated two dev-pools successfully!
new-xcp-dev: 2x Dell Inc. PowerEdge R650xs
old-xcp-dev: 3x Dell Inc. PowerEdge R350 (HA)I even mistankenly did a wrong updating order on old-xcp-dev. And neglected to disable HA before updating, leading to two hosts being updated and promoting the next master. And by chance the last master was the non-updated one. Here I disabled HA, but couldn't promote another master (not unexpected)... Post update, and everything seems to be good anyways. And HA re-enabled successfully
Note:
No further testing other than the hosts booting and showing good life signs have been done, yet. -
RE: [Solved] SR_SOURCE_SPACE_INSUFFICIENT - Problems enabling HA
Thanks again for your input and recomendations! I'll verify that this is solved by having the LUN expanded to 8GB instead. Afterwards I'll mark your answer as the solution!
-
RE: Rolling Snapshot not cleaning up old snapshots, regardless of retention is set to.
@olivierlambert
I've finally had time to sit down and do some more troubleshooting.
It seems that the issue is somehow tied to the backup-jobs themselves.
Deploying XOA and subsequently importing XO-config from my XOCE instance. I continued to see several issues between both instances.
These issues pretty much went away, when I re-did the backup-jobs from scratch. And are now much more in-line with what I'm excepting to see. This was done on both XOA Stable, Latest and XOCEI am no longer able to repoduce this at all.
So my guess is that a bug of some sort got introduced with this being a constantly updated from source instance.Marking as solved. As I don't believe there is much more to do at this time.
-
RE: A VM without any data on disk, passes Health Check - Bug?
Thanks for taking a look on your end as well.
I would like to point out that the line from the docs is quite deffinitive. If there are gotchas, such as UEFI affecting things. Then this either should be documented. Or better yet, that outlier of an edge-case probably should be addressed.One scenario I'm envisioning is that a disk is faulty for some reason, and this goes unoticed due to the VM being rarely used. And since no backup-errors are given, this might go unoticed for quite some time. The Health Check passing is a false signal in that case.
These are my two-cents. And I confirm that this is an edge-case, and even unlikely one. But a theoretical greater than zero risk anyways.
Thank you
-
RE: VM vCPU allocation
@McHenry
Differences could be things such as:- Amount of cores between hosts for migrations
- Guarantee performance between guests. So that they don't affect each other as much.
Same with overprovisioning dynamic RAM
-
RE: V2V migrated VMs don't autostart
Thanks for taking a look.
Yes it is this part that tells me that it should start the VM automatically once the import has completed.
"After the transfer, the VM on XCP-ng side is started:"
Followed by, "This process is fully automated, without any human intervention after it starts on step 1."
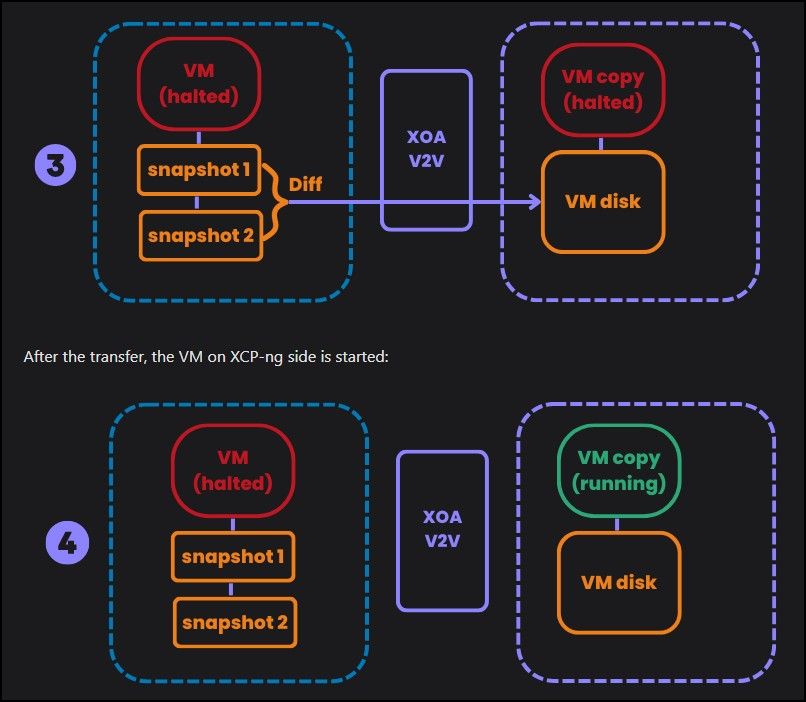
https://docs.xcp-ng.org/installation/migrate-to-xcp-ng/But my findings/experience is that the VM does not start once the import/transfer has completed.
So either the docs are wrong. Or the function is not behaving as intended. I'm acctually fine either way. As long as I know what to expect. However, I would like to have it auto-start the VMs after transfer completion. Which would make the procedure "Fully automated".
Update:
Am I assuming correctly that "the XO V2V guide says to start the VM yourself once the migration is complete " you're reffering to, is part of the "test migration"-procedure? Not the acctual production mgiration?
Because:"Final migration Run the production migration When you're ready for the final migration: Shut down the source VM completely. Start the V2V migration in Xen Orchestra with the Stop source option enabled. This ensures the final sync happens while the VM is powered off, and prevents any inconsistencies."In my mind doesn't state that the VM should be started manually post-transfer.
Great thanks in advance for discussing!
Cheers! -
V2V migrated VMs don't autostart
I'm at the moment doing alot of test with V2V (applause on getting rid of the vddk-dependency btw
 )
However, what I'm noticing is that the migrated VMs don't automatically start when the import has completed. This is contrary to current documentation.
Is this a potential bug? Or am I missing something obvious?
PS: The imports are all sucessfull. It's just the auto-start part that I'm noticing doesn't work.
Cheers!
Commit: dc573
Template used for testig is: Rocky Linux 9
-
RE: Support for newer Emulex LPe37xxx amd LPe36xxx Fiber channel adapters on XCP-ng 8.3 - your testing is needed
Third update:
It looks more and more that I had goofed something up in my testing. So please disregard everything in the post below.
The driver does work to make our LPe37000/LPe38000 series FC-cards work. Which is nice. Thanks!~~Good morning
So I might've found an issue with this driver release. That I'm trying to troubleshoot and collect data on.
We have two LUNs presented to our dev-pool (
xcp-dev), running onR650xs. When I have attached one LUN toxcp-devI can't see the other LUN.
This works on our older R350sRemoving the attached LUN, makes a LUN visible again. But now we're getting some strange behaviour. And looking into if it is misconfigured from the Dell Powerstore, or if it is on the host(s) itself.~~
Details:
multipath is enabledHost on
xcp-dev98:00.0 Fibre Channel [0c04]: Emulex Corporation LPe37000/LPe38000 Series 32Gb/64Gb Fibre Channel Adapter [10df:f500] (rev 11) Subsystem: Emulex Corporation Device [10df:f522] Kernel driver in use: lpfc Kernel modules: lpfc14 98:00.1 Fibre Channel [0c04]: Emulex Corporation LPe37000/LPe38000 Series 32Gb/64Gb Fibre Channel Adapter [10df:f500] (rev 11) Subsystem: Emulex Corporation Device [10df:f522] Kernel driver in use: lpfc Kernel modules: lpfc14Update:
~~After managing to revert my previous tests and forget the existing (wrong) LUN fromxcp-dev. I can now confirm a problem.There are three LUNs. Let's call them 101, 102, 103
When I attach one LUN (103) to
xcp-dev, I am no longer able to see the other LUNs. That means I can't add a second one. I am expecting to be able to see102available.However, on
old-dev, that has two LUNs attached already (101 & 102). It can see103as expected.~~host on
old-dev02:00.0 Fibre Channel [0c04]: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] (rev 03) Subsystem: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] Kernel driver in use: lpfc Kernel modules: lpfc 02:00.1 Fibre Channel [0c04]: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] (rev 03) Subsystem: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] Kernel driver in use: lpfc Kernel modules: lpfcSecond Update:
This might be unrelated. Seems that we're having weird behaviour with the LUNs in general. Please disregard the statement above for now -
RE: XCP-ng 8.3 updates announcements and testing
Now trying to see if pool works with generic operations.
Trying to do a RPR on new-xcp-dev. And I'm met with
Ofcourse there are no backups being run. They are even disabled right now. And the only active task happening is "Garbage collection" on the main SR.
pool.rollingReboot
{
  "pool": "1f16dad2---------------6c8b8b7",
  "bypassBackupCheck": false,
  "shutdownPinnedVms": false
}
{
  "code": "CANNOT_EVACUATE_HOST",
  "params": [
    "VM_LACKS_FEATURE,OpaqueRef:aa5210c4-a------------1b80-9bca5d0d0f8d|OPERATION_BLOCKED,OpaqueRef:c7a08---------------a0--------------9306,VM migration is blocked during backup"
  ],
  "call": {
    "duration": 23,
    "method": "host.assert_can_evacuate",
    "params": [
      "* session id *",
      "OpaqueRef:0145019c-2a32-13bb-5951-3bca9e59e63a"
    ]
  },
  "message": "CANNOT_EVACUATE_HOST(VM_LACKS_FEATURE,OpaqueRef:aa52-----------------------9bca5d0d0f8d|OPERATION_BLOCKED,OpaqueRef:c7a0------------------------306,VM migration is blocked during backup)",
  "name": "XapiError",
  "stack": "XapiError: CANNOT_EVACUATE_HOST(VM_LACKS_FEATURE,OpaqueRef:aa521-------------------8d|OPERATION_BLOCKED,OpaqueRef:c7a08c--------------------------9306,VM migration is blocked during backup)
    at XapiError.wrap (file:///opt/xen-orchestra/packages/xen-api/_XapiError.mjs:16:12)
    at file:///opt/xen-orchestra/packages/xen-api/transports/json-rpc.mjs:38:21
    at runNextTicks (node:internal/process/task_queues:65:5)
    at processImmediate (node:internal/timers:541:9)"
}
Update:
I believe this might be related due to a VDI being orphaned, and trying to delete it results inVDI_NOT_MANAGED-error. Trying a new rescan of disks on the SR, and hopefully garbage collection will finish until Monday. Otherwise I will somehow try to forcefully destroy this VDI.Update 2:
Managed to do a RPR now.
Seems that the flag "Prevent Migration" was applied to one of the VMs. My guess is that this is applied when backups are taken. And since the backups broke with the updates. The flag never got cleared.
I did a quick visual confirmation to see that my guess of this behaviour seems correct. And it indeed sets the "Prevent migration"-flag whilst the backup runs.Running backups on my pools to see if functionality is working as intended again.
Update 3:
Maybe related, maybe not. But my backup-tests are piling up with lots ofVBD.unplug_force, that have gone on for <=30 minutes. And this is on both pools. And it seems very much so that the backup-jobs doesn't complete properly. This could also be entirely XO-related, since there has been several commits towards backups as well.Update 4:
Updated XO from source to the latest commitd2ffe, and things have not improved.
Pretty much, many actions with VDIs are problematic. I'll happily provide logs. But will only do so if I get somewhere to upload them to.
I'll be taking the weekend now. So won't be able to respond before monday,