XCP-ng
    • Categories
    • Recent
    • Tags
    • Popular
    • Users
    • Groups
    • Register
    • Login
    • Profile
    • Following 0
    • Followers 0
    • Topics 12
    • Posts 93
    • Groups 0
    J Offline
    1. Home
    2. jr-m4
    3. Posts

    Posts

    Recent Best Controversial
    • RE: Rolling pool update

      @Octopuss

      Are you running a pool with only 1 host inside? If so, then I believe Rolling Pool Update (RPU) isn't available.

      The point of it is to have a automated way to let XO migrate VMs in the pool to the other hosts. And when the intended host (master first) is empty, it will place it in maintenance mode, and afterwards reboot it. This will then re-iterate until all hosts in the pool have been updated.

      More can be found here:
      https://docs.xcp-ng.org/management/updates/#from-xen-orchestra

      posted in Xen Orchestra
      J
      jr-m4
    • RE: XCP-ng 8.3 updates announcements and testing

      3 pools updated. RPU went fine, where one is HA. A couple of test-backups went fine as well.

      posted in News
      J
      jr-m4
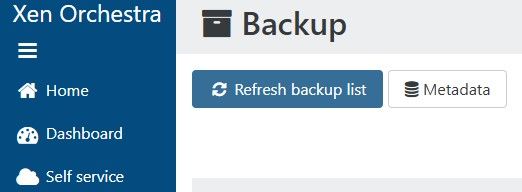
    • [XO5] Small UI inconsitency in Backup restore - Missing "Refresh backup list" when in Metadata-section

      When you're in the Metadata section of the restore The button for Refresh backup list disapears.

      I'm kind of expecting this to not be worked on. Due to it being so small, and in XO5. But for the interest of reporting things. I wanted to share anyways.

      image.jpeg

      VS

      image.jpeg

      posted in Backup
      J
      jr-m4
    • RE: XCP-ng 8.3 updates announcements and testing

      Updated both test-pools: old-xcp-dev & new-xcp-dev

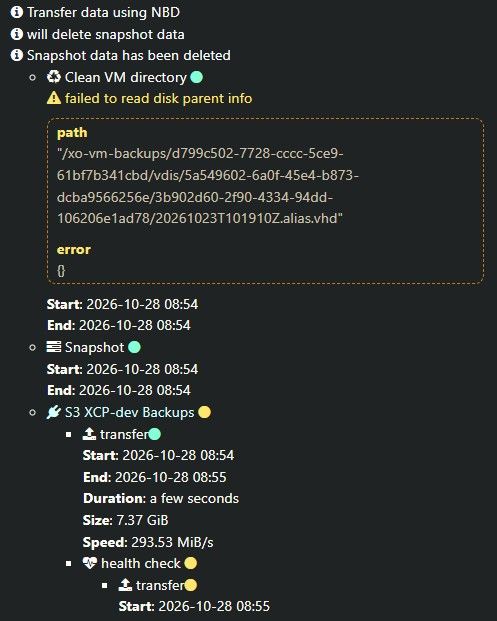
      Backups seem to be working fine. But I'm noticing some warnings now (See below). However, these can very well be the result of clumsy and crude troubleshooting with fixing the previous test-release symptoms.

      Dashboard/Health doesn't report any issues. And I'm not seing issues with the VMs in their running state.
      Backups are seemingly clearing HealthChecks as well.

      I will update this post in a living matter. So to not spam the forum-thread with many small posts.

      Symptom 1:
      image.jpeg

      Update 1:
      So the only way I could "solve" the issue, was to delete all of the backups for the VM in question. Afterwards it started behaving as expected. I haven't found anything else problematic so far.

      posted in News
      J
      jr-m4
    • RE: XCP-ng 8.3 updates announcements and testing

      Now trying to see if pool works with generic operations.

      Trying to do a RPR on new-xcp-dev. And I'm met with

      Ofcourse there are no backups being run. They are even disabled right now. And the only active task happening is "Garbage collection" on the main SR.

      pool.rollingReboot
      {
        "pool": "1f16dad2---------------6c8b8b7",
        "bypassBackupCheck": false,
        "shutdownPinnedVms": false
      }
      {
        "code": "CANNOT_EVACUATE_HOST",
        "params": [
          "VM_LACKS_FEATURE,OpaqueRef:aa5210c4-a------------1b80-9bca5d0d0f8d|OPERATION_BLOCKED,OpaqueRef:c7a08---------------a0--------------9306,VM migration is blocked during backup"
        ],
        "call": {
          "duration": 23,
          "method": "host.assert_can_evacuate",
          "params": [
            "* session id *",
            "OpaqueRef:0145019c-2a32-13bb-5951-3bca9e59e63a"
          ]
        },
        "message": "CANNOT_EVACUATE_HOST(VM_LACKS_FEATURE,OpaqueRef:aa52-----------------------9bca5d0d0f8d|OPERATION_BLOCKED,OpaqueRef:c7a0------------------------306,VM migration is blocked during backup)",
        "name": "XapiError",
        "stack": "XapiError: CANNOT_EVACUATE_HOST(VM_LACKS_FEATURE,OpaqueRef:aa521-------------------8d|OPERATION_BLOCKED,OpaqueRef:c7a08c--------------------------9306,VM migration is blocked during backup)
          at XapiError.wrap (file:///opt/xen-orchestra/packages/xen-api/_XapiError.mjs:16:12)
          at file:///opt/xen-orchestra/packages/xen-api/transports/json-rpc.mjs:38:21
          at runNextTicks (node:internal/process/task_queues:65:5)
          at processImmediate (node:internal/timers:541:9)"
      }
      

      Update:
      I believe this might be related due to a VDI being orphaned, and trying to delete it results in VDI_NOT_MANAGED-error. Trying a new rescan of disks on the SR, and hopefully garbage collection will finish until Monday. Otherwise I will somehow try to forcefully destroy this VDI.

      Update 2:
      Managed to do a RPR now.
      Seems that the flag "Prevent Migration" was applied to one of the VMs. My guess is that this is applied when backups are taken. And since the backups broke with the updates. The flag never got cleared.
      I did a quick visual confirmation to see that my guess of this behaviour seems correct. And it indeed sets the "Prevent migration"-flag whilst the backup runs.

      Running backups on my pools to see if functionality is working as intended again.

      Update 3:
      Maybe related, maybe not. But my backup-tests are piling up with lots of VBD.unplug_force, that have gone on for <=30 minutes. And this is on both pools. And it seems very much so that the backup-jobs doesn't complete properly. This could also be entirely XO-related, since there has been several commits towards backups as well.

      Update 4:
      Updated XO from source to the latest commit d2ffe, and things have not improved.
      Pretty much, many actions with VDIs are problematic. I'll happily provide logs. But will only do so if I get somewhere to upload them to.
      I'll be taking the weekend now. So won't be able to respond before monday,
      posted in News
      J
      jr-m4
    • RE: XCP-ng 8.3 updates announcements and testing

      @dthenot said:

      @flakpyro Hello,

      It would be preferred to use another method.
      You can use the resetvdis.py script in the /opt/xensource/sm/ to reset values instead,
      using vdi-forget is unadvised in this case, it can cause issues by losing information that are stored in XAPI about VDIs.

      /opt/xensource/sm/resetvdis.py single <VDI UUID>
      

      I was just about to look at maybe doing what @flakpyro suggested. More likely I would've just restored from backup. As this is dev-instances, and non-important.

      But your resetvdis.pysuggestion solved it entirely! Thanks for the quick tip!

      posted in News
      J
      jr-m4
    • RE: XCP-ng 8.3 updates announcements and testing

      @Emmanuel-V

      Rebooting hosts and/or VMs doesn't solve the problems.
      As @andrew said. This one got ugly. But this is also why we test stuff

      Update:
      Doing a "Rescan all disks" on the SR (lvmohba), seems to help out a little bit. But not everything.
      Some VMs were able to be started again. But others are still showing problems and erroring out

      "The VDI is not available [opterr=['MAP_DUPLICATE_KEY', 'VDI', 'sm_config', 'OpaqueRef:7---------2c1b', 'activating']]",
      posted in News
      J
      jr-m4
    • RE: Support for newer Emulex LPe37xxx amd LPe36xxx Fiber channel adapters on XCP-ng 8.3 - your testing is needed

      @MrQ said:

      @jr-m4 thank you so much for testing this updated driver.

      Just to make sure, I understand now that you confirm the driver is working as expected and the issues you had were not related to it? Or are there any problems still with this new driver?

      Many thanks again for spending the time to test and report.

      Hi

      Yes. I believe I was chasing a red herring of my own doing. I have not found anything actually problematic with this driver at all.

      posted in Hardware
      J
      jr-m4
    • RE: XCP-ng 8.3 updates announcements and testing

      jr-m4 said:

      Updated two dev-pools successfully!

      new-xcp-dev: 2x Dell Inc. PowerEdge R650xs
      old-xcp-dev: 3x Dell Inc. PowerEdge R350 (HA)

      I even mistankenly did a wrong updating order on old-xcp-dev. And neglected to disable HA before updating, leading to two hosts being updated and promoting the next master. And by chance the last master was the non-updated one. Here I disabled HA, but couldn't promote another master (not unexpected)... Post update, and everything seems to be good anyways. And HA re-enabled successfully

      Note:
      No further testing other than the hosts booting and showing good life signs have been done, yet.

      I'm now also seeing issues with backups being stuck for multiple hours.
      Update: Correction. I'm now having issues with almost everything on both pools.

      • migrations
      • snapshots
      • changing status e.g. rebooting or hard shut down of VMs
      posted in News
      J
      jr-m4
    • RE: XCP-ng 8.3 updates announcements and testing

      Updated two dev-pools successfully!

      new-xcp-dev: 2x Dell Inc. PowerEdge R650xs
      old-xcp-dev: 3x Dell Inc. PowerEdge R350 (HA)

      I even mistankenly did a wrong updating order on old-xcp-dev. And neglected to disable HA before updating, leading to two hosts being updated and promoting the next master. And by chance the last master was the non-updated one. Here I disabled HA, but couldn't promote another master (not unexpected)... Post update, and everything seems to be good anyways. And HA re-enabled successfully

      Note:
      No further testing other than the hosts booting and showing good life signs have been done, yet.

      posted in News
      J
      jr-m4
    • RE: Are there any downsides to using CBT when doing backups?

      @poddingue
      Acctually my experience is that a VDI with CBT enabled can't have its VDI migrated at all. And XO does indeed catch that CBT is enabled. But it doesn't disable it -> migrate -> re-enable.

      @archw
      And if you'd like to migrate VDIs between SRs you'd most likely also have to delete existing snapshots as well (along with disabling CBT prior to migrating).

      posted in Backup
      J
      jr-m4
    • RE: Are there any downsides to using CBT when doing backups?

      One potential downside is that CBT makes live-migrations between SRs alot more difficult.

      posted in Backup
      J
      jr-m4
    • RE: A VM without any data on disk, passes Health Check - Bug?

      @poddingue
      Thank you!

      posted in Backup
      J
      jr-m4
    • RE: A VM without any data on disk, passes Health Check - Bug?

      @poddingue

      Thanks for taking a look on your end as well.
      I would like to point out that the line from the docs is quite deffinitive. If there are gotchas, such as UEFI affecting things. Then this either should be documented. Or better yet, that outlier of an edge-case probably should be addressed.

      One scenario I'm envisioning is that a disk is faulty for some reason, and this goes unoticed due to the VM being rarely used. And since no backup-errors are given, this might go unoticed for quite some time. The Health Check passing is a false signal in that case.

      These are my two-cents. And I confirm that this is an edge-case, and even unlikely one. But a theoretical greater than zero risk anyways.

      Thank you

      posted in Backup
      J
      jr-m4
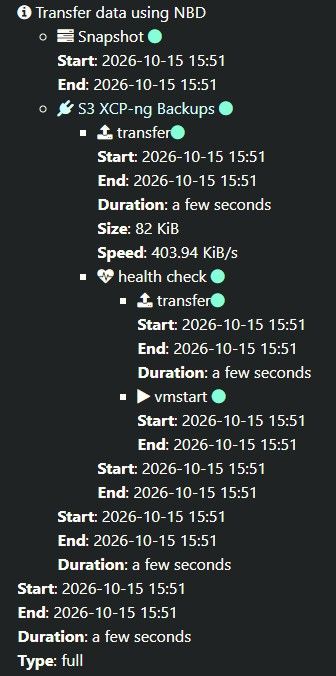
    • A VM without any data on disk, passes Health Check - Bug?

      After doing some reshuffling and having to re-create a couple of VMs. I have two with newly created disks, that don't contain any data yet.
      Upon doing some checks on the backup-schedules, I notice that these two passed the latest Delta-backup Health Check. However, as I mentioned earlier. These don't have data on their disks, and hence no Guest-Tools can be installed.

      "A VM without guest tools will fail its health check."

      source: https://docs.xen-orchestra.com/backups-and-dr/backup-features-and-settings#backup-health-check

      image.jpeg

      posted in Backup
      J
      jr-m4
    • RE: Support for newer Emulex LPe37xxx amd LPe36xxx Fiber channel adapters on XCP-ng 8.3 - your testing is needed

      Third update:
      It looks more and more that I had goofed something up in my testing. So please disregard everything in the post below.
      The driver does work to make our LPe37000/LPe38000 series FC-cards work. Which is nice. Thanks!

      ~~Good morning

      So I might've found an issue with this driver release. That I'm trying to troubleshoot and collect data on.

      We have two LUNs presented to our dev-pool (xcp-dev), running on R650xs. When I have attached one LUN to xcp-dev I can't see the other LUN.
      This works on our older R350s

      Removing the attached LUN, makes a LUN visible again. But now we're getting some strange behaviour. And looking into if it is misconfigured from the Dell Powerstore, or if it is on the host(s) itself.~~

      Details:
      multipath is enabled

      Host on xcp-dev

      98:00.0 Fibre Channel [0c04]: Emulex Corporation LPe37000/LPe38000 Series 32Gb/64Gb Fibre Channel Adapter [10df:f500] (rev 11)
              Subsystem: Emulex Corporation Device [10df:f522]
              Kernel driver in use: lpfc
              Kernel modules: lpfc14
      98:00.1 Fibre Channel [0c04]: Emulex Corporation LPe37000/LPe38000 Series 32Gb/64Gb Fibre Channel Adapter [10df:f500] (rev 11)
              Subsystem: Emulex Corporation Device [10df:f522]
              Kernel driver in use: lpfc
              Kernel modules: lpfc14
      

      Update:
      ~~After managing to revert my previous tests and forget the existing (wrong) LUN from xcp-dev. I can now confirm a problem.

      There are three LUNs. Let's call them 101, 102, 103

      When I attach one LUN (103) to xcp-dev, I am no longer able to see the other LUNs. That means I can't add a second one. I am expecting to be able to see 102 available.

      However, on old-dev, that has two LUNs attached already (101 & 102). It can see 103 as expected.~~

      host on old-dev

      02:00.0 Fibre Channel [0c04]: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] (rev 03)
              Subsystem: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100]
              Kernel driver in use: lpfc
              Kernel modules: lpfc
      02:00.1 Fibre Channel [0c04]: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100] (rev 03)
              Subsystem: Emulex Corporation LPe12000 Series 8Gb Fibre Channel Adapter [10df:f100]
              Kernel driver in use: lpfc
              Kernel modules: lpfc
      

      Second Update:
      This might be unrelated. Seems that we're having weird behaviour with the LUNs in general. Please disregard the statement above for now

      posted in Hardware
      J
      jr-m4
    • RE: [V2V] Without VDDK problems

      @mpiton

      Thanks for a fantasticly quick answer, and detailed as well. I will test this immediately!

      Update:
      I can confirm that this was indeed the problem!

      posted in Migrate to XCP-ng
      J
      jr-m4
    • RE: [V2V] Without VDDK problems

      Looking into journcelctl on the XO-server, after I enabled CBT-tracking on the VM (using this KB from Broadcom https://knowledge.broadcom.com/external/article/315370/enabling-or-disabling-changed-block-trac.html). I get the following:

      The initial V2V-snapshot on vmware is created as expected. So there is communication between XO and vmware (vcenter-host)

      Oct 02 13:24:33 hostname-xo-server xo-server[55639]: 2026-10-02T11:24:33.361Z xo:vmware-explorer:esxi INFO got the data map from the change tracking of the host {
      Oct 02 13:24:33 hostname-xo-server xo-server[55639]:   blocks: 16,
      Oct 02 13:24:33 hostname-xo-server xo-server[55639]:   bytes: 20912799744,
      Oct 02 13:24:33 hostname-xo-server xo-server[55639]:   diskPath: 'vm-name_1/vm-name.vmdk',
      Oct 02 13:24:33 hostname-xo-server xo-server[55639]:   full: true,
      Oct 02 13:24:33 hostname-xo-server xo-server[55639]:   seconds: 0,
      Oct 02 13:24:33 hostname-xo-server xo-server[55639]:   vmId: 'vm-1169935'
      Oct 02 13:24:33 hostname-xo-server xo-server[55639]: }
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]: 2026-10-02T11:24:44.496Z vates:nbd-client:stdio WARN the nbd server process exited unexpectedly {
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:   error: Error: the nbd server process exited (code: 1, signal: null)
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:       at ChildProcess.<anonymous> (file:///opt/xen-orchestra/@vates/nbd-client/NbdStdioClient.mjs:107:21)
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:       at ChildProcess.wrapper (node:events:639:12)
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:       at ChildProcess.emit (node:events:514:28)
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:       at ChildProcess.patchedEmit [as emit] (/opt/xen-orchestra/@xen-orchestra/log/configure.js:52:17)
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:       at Process.ChildProcess._handle.onexit (node:internal/child_process:295:12) {
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:     code: 'NBD_SERVER_EXITED',
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:     exitCode: 1,
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:     signal: null,
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:     command: '/opt/xen-orchestra/@xen-orchestra/vmware-explorer/vectura/vectura',
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:     stderr: 'vectura: data plane: could not connect: timed out\n'
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]:   }
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]: }
      Oct 02 13:24:44 hostname-xo-server xo-server[55639]: 2026-10-02T11:24:44.526Z xo:api WARN username-1 | vm.importMultipleFromEsxi(...) [17s] =!> Error: stream has ended without data, was looking for 8 bytes
      
      posted in Migrate to XCP-ng
      J
      jr-m4
    • [V2V] Without VDDK problems

      First of all. Thanks for putting alot of effort into getting migrations to work without VDDK. https://github.com/vatesfr/xen-orchestra/pull/10421

      However. I did a new provisioning of an XO-source instance. And wanted to test it without any hanging dependencies from previously installed vddk's.

      Now I'm getting met with failed import-attempts.

      Attempts with my previous XO instance, on the same commit: b59c8 works just fine. Except the VMs not starting automatically after import (discussed in separate thread: https://xcp-ng.org/forum/post/108686)

      vm.importMultipleFromEsxi
      {
        "concurrency": 2,
        "host": "vcenter-host",
        "network": "72471fb1-58fd-d2d1-9a1e-46aea05374b4",
        "password": "* obfuscated *",
        "sr": "4d58d7f1-087a-bc7b-a957-e8f8be8b1f77",
        "sslVerify": false,
        "stopOnError": true,
        "stopSource": true,
        "template": "37e7a3b9-8c45-c7f2-7d09-249a935dd33d-1a647cf9-99c1-4e9c-b3b4-6b9989c530be",
        "user": "obfuscated",
        "vms": [
          "vm-1169935"
        ]
      }
      {
        "succeeded": {},
        "message": "stream has ended without data, was looking for 8 bytes",
        "name": "Error",
        "stack": "Error: stream has ended without data, was looking for 8 bytes
          at readChunkStrict (/opt/xen-orchestra/@vates/read-chunk/index.js:83:13)"
      }
      ´´´
      posted in Migrate to XCP-ng
      J
      jr-m4
    • RE: XCP-ng 8.3 updates announcements and testing

      Installed on 3xDell PowerEdge R350 in HA. And so far, I haven't noticed anything out of the ordinary.

      posted in News
      J
      jr-m4