If I had my choice, Prevent Migration is more understandable.
Disable Migration, while it means the same thing, doesn't naturally come out of the English language.
If I had my choice, Prevent Migration is more understandable.
Disable Migration, while it means the same thing, doesn't naturally come out of the English language.
@olivierlambert I was able to sort out the issue, it has to do with licensing and the fact that we aren't licensed to with "Live Migration" for this ESXi host.
Essentially this inquiry is solved.
@TechGrips While I can understand the desire to use removable USB as a Backup Repo, I would highly discourage it.
Managing and rotating USB drives is a pain, if they go to sleep, it's a pain, if they fail it's a pain, if you forget to rotate your drives, it's a pain.
I personally can understand the desire to do so, it's cheap and relatively affective if you can deal with these risks, however so is just using any NFS or SMB share and then having a replication script that could write to your USB, which you could then rotate. Separating your XCP-ng hosts, XO, and your backups is of critical importance because if you have any sort of server room environmental issues or failure, you're risking loosing everything.
XCP-ng and Xen Orchestra, while they do offer a ton of flexibility, there is obviously trades-offs to using less than ideal components, such as external USB drives as your primary backup repository.
If you really want to insist on using USB drives, you'll have to attach the drives to your host and then pass them through to your XO installation, which when you want to rotate those drives you'll have to update your Backup jobs within XO and confirm that your XO VM has the proper access to the drives. This seems like a lot of complexity for very little financial benefit.
Separately I think you're taking your own frustrations out on the community, because of a lack of understanding in the tooling that you testing in comparison to ESXi where you'd attach a USB drive directly, perform your backup, remove the disk and attach another.
I get that ESXi can make things "simple" but simple isn't always better.
HTH
The reason you wouldn't want to look at XO for this from a technical standpoint is because XO works at the hardware level of the hypervisor, dolling out resources to different VMs and creating backups.
You need to look at the content within a given VM and compare the file system difference from points A and B.
Only something that is operating within the file system would be able to readily tell you "Something has changed".
Odds are you have a user or several who are dumping files onto a share that they shouldn't be, or are replicating some cloud service to keep a copy on your server etc.
@flakpyro said in How to migrate XOA itself?:
@DustinB Are the any downsides to having two XOA instances pointing at the same pool? Since the config itself is stored at the pool level im guessing theres no downside?
IE: Priimary XOA running in core DC and secondary XOA running at your DR site. Is it just a matter of adding the pool on the secondary XOA and it downloads the existing config or did you need to do a full export / import?
If you import your configuration, each XO instance will think they should be running the backups as far as I've noticed. If I have two instances running with the same configuration, I simply disable the backup jobs on one of them.
The config file is just an XML that contains your existing instance. You can import it to any new XO instance and have the same exact configuration.
@yzgulec there really isn't any hard-fast rules to aligning CPU to vCPU. A Guest is going to need cores to operate no matter what.
If you're trying to min-max your CPU utilization for a given system, you might want to target the guest to use between 70-80% of it's vCPU all of the time.
This is all a part of system tuning and is always a shifting target, as CPU is shared among all VMs and DOM0.
As you increase the number of guests on a host, the CPU consumption will be increased, which means you may need to scale back on the vCPU a given VM has.
@stormi said in XSA-468: multiple Windows PV driver vulnerabilities - update now!:
Do others share this feeling and have this question after re-reading the whole announcement?
No it's pretty clear, update the drivers on everything as all versions are susceptible.
@olivierlambert I agree wholeheartedly with you on that. Keeping the system stock is best for support.
Separately, is there any planned work on officially integrating support for Uninterruptable Power Supplies and XCP-ng 8.3?
A question
You can disable all of the boot devices in the Advanced section of the VM, try disabling the HDD
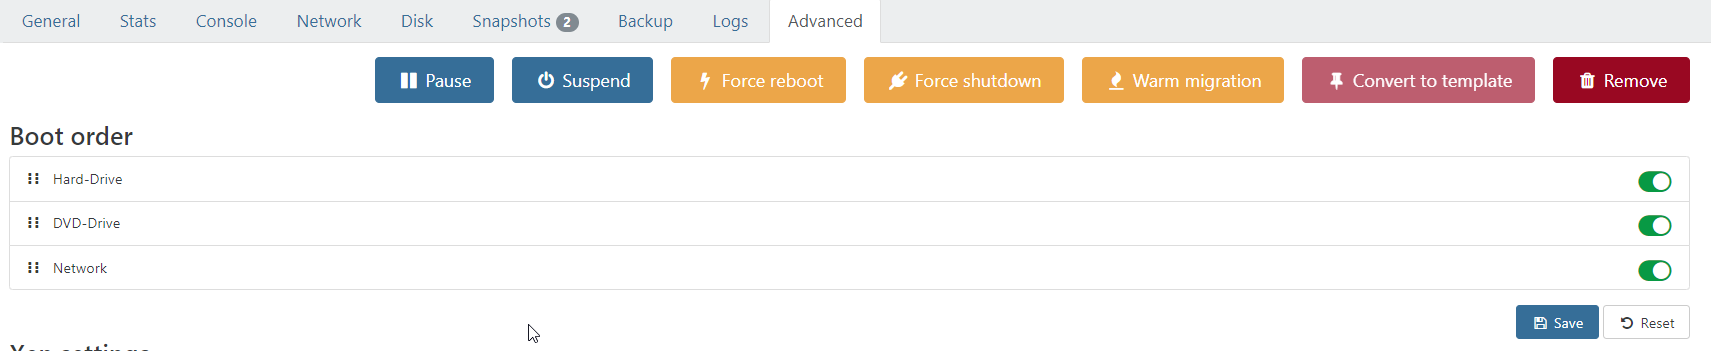
Disable the Boot options if your system is making it past POST to quickly so you can get into the Guests BIOS.
@jasonnix said in A question for the creators of XO:
Hi @olivierlambert,
No, I'm not a bot. I asked it because I need your experiences. I want to make a panel for Xen.
So you know how to program with PHP and Ruby and not with Javascript, so the question is really "Why can't this be rewritten so I can help?"
14 year old controller
it supported and has a driver. Whats wrong?
I can't find that storage adapter on the HCL, were you able to? But the summary I have here is replace the old really old adapter.
How reliable can't this card still be after working for so long?
Since I'm the happy owner of this controller, if there's no urgent solution, then tell me which models are definitely compatible with 8.3?
The Adaptec ASR-71605 was released in 2012, that's 14 years old. I'd use https://hcl.xenserver.com/search/?type=storagecontrollers&support_status=supported&page=1 to find compatible controllers if you need help.
But yeah... 14 year old controller...
I'm guessing this might be having updates applied, and now I need new Xen Tools. I have a feeling tomorrow will be filled with updating the tools and checking things because I bet all my backups fail tonight. And I bet all fail after they try to start.
Are you performing nightly healthy checks? Seems obsessive to need to check every system makes it to a login screen, but on the other hand, I understand.
Just curious.
@Greg_E Right, the backup operations are occurring outside of the VM, at the hypervisor layer. The guest drivers, don't stop or flush any database writes to disk etc.
So while the VM will likely boot, you might lose records or changes.
Depending on the size of your organization, it may be moot, but still worth keeping an eye on it.
I've seen other people use Veeam Backup and Replication to backup their Domain Controllers outside of the XO backup mechanism, and now that it's officially integrated, it might be a good contender here (and for others). https://www.veeam.com/products/free/backup-recovery.html for things that need to be handled "carefully".
@Greg_E Worth remembering that DC backups need to be completed by something that is database aware, as far as I know, XO doesn't currently have this functionality, and if so, you are risking your entire environment....
Just discussed this with @nathanael-h; I would strongly recommend using the load balancer plugin in XO and create some VM-to-host affinity rules, so that your CP VMs are running on different hosts ! So when the RPU comes you would have minimum impact.
Yeah the Load Balancer plugin is an option, though not in my plan. I could certainly get it by using XOCE for free though.
I wonder if Host Affinity might work as well...
@Greg_E When was the last time you updated the guest drivers?
One thing that I need to sort out - how can I ensure that I'm able to keep quorum at all times between my control planes?
During a RPU, I need to have at least 2 non-paused CP VMs running or else the environment goes belly up.
The system does seem very sensitive to those kinds of shifts, so anyone looking to deploy this, be mindful of RPU's. Maybe manually move 1 CP off of Host A to Host B, patch Host A, then move the CP back to Host A afterwards...
@poddingue Sorry, I was asleep when you posted this, but yes that is perfectly fine to move it into the IaaS category.
Hey All, I recently deployed OKD on XCP-ng and wanted to share the runbook that I wrote to go along with the installation incase anyone else was looking at Redhat like Yeah Nah....
User-Provisioned Infrastructure · CentOS Stream CoreOS (SCOS) · Rocky Linux Helper · DNS/DHCP
This guide documents the validated step-by-step procedure to deploy OKD 5 (CentOS Stream CoreOS - SCOS) on User-Provisioned Infrastructure (UPI) using XCP-ng, a Rocky Linux Helper VM, and an external DNS/DHCP server.
| Role | Hostname | IP Address | vCPU | RAM | Disk | Notes |
|---|---|---|---|---|---|---|
| DNS / DHCP | services.domain.int | 10.100.20.248 | — | — | — | Shared Infrastructure |
| Helper / LB | helper.okd.domain.int | 10.100.3.9 | 2 | 4 GB | 30 GB | Rocky Linux (HAProxy + Apache) |
| Bootstrap | bootstrap.okd.domain.int | 10.100.3.3 | 4 | 16 GB | 60 GB | Temporary VM (Destroyed post-install) |
| Control Plane 1 | fedora-cp-1.okd.domain.int | 10.100.3.4 | 4 | 16 GB | 60 GB | Master Node 1 |
| Control Plane 2 | fedora-cp-2.okd.domain.int | 10.100.3.5 | 4 | 16 GB | 60 GB | Master Node 2 (Bind MAC in DHCP) |
| Control Plane 3 | fedora-cp-3.okd.domain.int | 10.100.3.6 | 4 | 16 GB | 60 GB | Master Node 3 |
| Compute 1 | fedora-cmp-1.okd.domain.int | 10.100.3.7 | 2–4 | 8 GB | 60 GB | Worker Node 1 |
| Compute 2 | fedora-cmp-2.okd.domain.int | 10.100.3.8 | 2–4 | 8 GB | 60 GB | Worker Node 2 |
Subnet: 10.100.0.0/16
Base Domain: domain.int
Cluster Name: okd
Worker count: A 2-worker topology is suitable for non-HA workloads. Control plane nodes are set to non-schedulable in this guide, so workloads requiring 3-way quorum or strict pod anti-affinity (for example IBM MQ Native HA, OpenShift Data Foundation / Ceph, Elasticsearch, Kafka) will leave their third replica Pending. If deploying such workloads, provision a third compute node (fedora-cmp-3) and add it to the DNS, DHCP, and HAProxy ingress configuration.
Worker memory: 8 GB per compute node is suitable for an idle or lightly loaded lab cluster. OKD system pods (OVN-Kubernetes, ingress routers, monitoring, image registry) consume a substantial share of that, so 16 GB per compute node is recommended if you plan to test multi-container operators or stateful applications.
To avoid IP drift on a flat /16 network, map the virtual MAC addresses of all 6 cluster VMs and the Helper VM to their assigned static IPs inside your network DNS/DHCP Server before powering them on.
Add the following A records:
helper.okd.domain.int. A 10.100.3.9
api.okd.domain.int. A 10.100.3.9
api-int.okd.domain.int. A 10.100.3.9
*.apps.okd.domain.int. A 10.100.3.9
bootstrap.okd.domain.int. A 10.100.3.3
fedora-cp-1.okd.domain.int. A 10.100.3.4
fedora-cp-2.okd.domain.int. A 10.100.3.5
fedora-cp-3.okd.domain.int. A 10.100.3.6
fedora-cmp-1.okd.domain.int. A 10.100.3.7
fedora-cmp-2.okd.domain.int. A 10.100.3.8
Configure a reverse lookup zone in network DNS. Entries must map the host octet to the FQDN with a trailing dot:
$ORIGIN 3.100.10.in-addr.arpa.
$TTL 86400
3.100.10.in-addr.arpa. IN SOA ns.3.100.10.in-addr.arpa. mail.3.100.10.in-addr.arpa. (
    1 43200 180 1209600 10800
)
3.100.10.in-addr.arpa. IN NS ns.domain.int.
3 IN PTR bootstrap.okd.domain.int.
4 IN PTR fedora-cp-1.okd.domain.int.
5 IN PTR fedora-cp-2.okd.domain.int.
6 IN PTR fedora-cp-3.okd.domain.int.
7 IN PTR fedora-cmp-1.okd.domain.int.
8 IN PTR fedora-cmp-2.okd.domain.int.
9 IN PTR helper.okd.domain.int.
CoreOS and etcd are sensitive to clock drift. Significant clock skew between control plane VMs can cause etcd to lose quorum and the installation to fail with gRPC dial timeouts. Confirm that you network DHCP server hands out a valid NTP server (DHCP Option 42) to all cluster VMs, or otherwise ensure all nodes sync to the same time source.
Log into the Rocky Linux Helper VM (10.100.3.9) to configure services.
sudo dnf install -y epel-release
sudo dnf install -y haproxy httpd bind-utils wget curl jq tar helm
# Allow HAProxy to proxy arbitrary network ports
sudo setsebool -P haproxy_connect_any 1

# Open API, Ingress, Machine Config, and HTTP installation ports
sudo firewall-cmd --permanent --add-port={80,443,6443,22623,8080}/tcp
sudo firewall-cmd --reload
Run Apache on port 8080 to leave ports 80 and 443 open for HAProxy ingress routing.
sudo sed -i 's/^Listen 80/Listen 8080/' /etc/httpd/conf/httpd.conf
sudo mkdir -p /var/www/html/okd
sudo chown -R apache:apache /var/www/html/okd
sudo chmod -R 755 /var/www/html/okd
sudo systemctl enable --now httpd
Replace /etc/haproxy/haproxy.cfg with:
global
    log 127.0.0.1 local2
    chroot /var/lib/haproxy
    pidfile /var/run/haproxy.pid
    maxconn 4000
    user haproxy
    group haproxy
    daemon
    stats socket /var/lib/haproxy/stats

defaults
    mode tcp
    log global
    option tcplog
    option dontlognull
    retries 3
    timeout queue 1m
    timeout connect 10s
    timeout client 1m
    timeout server 1m
    timeout check 10s
    maxconn 3000

# --- Kubernetes API (Port 6443) ---
frontend okd_k8s_api_fe
    bind *:6443
    default_backend okd_k8s_api_be

backend okd_k8s_api_be
    balance roundrobin
    server bootstrap 10.100.3.3:6443 check
    server fedora-cp-1 10.100.3.4:6443 check
    server fedora-cp-2 10.100.3.5:6443 check
    server fedora-cp-3 10.100.3.6:6443 check

# --- Machine Config Server (Port 22623) ---
frontend okd_machine_config_fe
    bind *:22623
    default_backend okd_machine_config_be

backend okd_machine_config_be
    balance roundrobin
    server bootstrap 10.100.3.3:22623 check
    server fedora-cp-1 10.100.3.4:22623 check
    server fedora-cp-2 10.100.3.5:22623 check
    server fedora-cp-3 10.100.3.6:22623 check

# --- Ingress Router HTTP (Port 80) ---
frontend okd_http_ingress_fe
    bind *:80
    default_backend okd_http_ingress_be

backend okd_http_ingress_be
    balance roundrobin
    server fedora-cmp-1 10.100.3.7:80 check
    server fedora-cmp-2 10.100.3.8:80 check

# --- Ingress Router HTTPS (Port 443) ---
frontend okd_https_ingress_fe
    bind *:443
    default_backend okd_https_ingress_be

backend okd_https_ingress_be
    balance roundrobin
    server fedora-cmp-1 10.100.3.7:443 check
    server fedora-cmp-2 10.100.3.8:443 check
Validate and start HAProxy:
sudo haproxy -c -f /etc/haproxy/haproxy.cfg
sudo systemctl enable --now haproxy
Execute these commands as the admin user (<admin-user>) on the Helper VM.
cd ~
export OKD_VER="5.0.0-okd-scos.2"
wget https://github.com/okd-project/okd/releases/download/${OKD_VER}/openshift-client-linux-${OKD_VER}.tar.gz
wget https://github.com/okd-project/okd/releases/download/${OKD_VER}/openshift-install-linux-${OKD_VER}.tar.gz
tar -xvf openshift-client-linux-${OKD_VER}.tar.gz
tar -xvf openshift-install-linux-${OKD_VER}.tar.gz
sudo mv oc kubectl openshift-install /usr/local/bin/
Fetch the exact installer-matched image URL:
openshift-install coreos print-stream-json | jq -r '.architectures.x86_64.artifacts.metal.formats.iso.disk.location'
Upload this downloaded .iso to your XCP-ng storage repository.
[ -f ~/.ssh/id_ed25519 ] || ssh-keygen -t ed25519 -N '' -f ~/.ssh/id_ed25519
mkdir -p ~/okd-install
cd ~/okd-install
cat <<EOF > install-config.yaml
apiVersion: v1
baseDomain: domain.int
metadata:
  name: okd
compute:
- hyperthreading: Enabled
  name: worker
  replicas: 0
controlPlane:
  hyperthreading: Enabled
  name: master
  replicas: 3
networking:
  networkType: OVNKubernetes
  clusterNetwork:
  - cidr: 10.128.0.0/14
    hostPrefix: 23
  serviceNetwork:
  - 172.30.0.0/16
platform:
  none: {}
# Note: Because OKD pulls exclusively from public community container registries, this dummy pull secret works out of the box with no modifications.
pullSecret: '{"auths":{"fake":{"auth":"aWQ6cGFzc3dvcmQ="}}}'
sshKey: '$(cat ~/.ssh/id_ed25519.pub)'
EOF

# Back up the install configuration
cp install-config.yaml install-config.yaml.bak
Note: compute replicas is set to 0 because on User-Provisioned Infrastructure (platform: none) there is no cloud provider to create machines. The two worker VMs are provisioned manually and join the cluster through the CSR approvals in Section 7.
# 1. Create manifests
openshift-install create manifests --dir=~/okd-install

# 2. Prevent general user workloads on master nodes
sed -i 's/mastersSchedulable: true/mastersSchedulable: false/g' ~/okd-install/manifests/cluster-scheduler-02-config.yml

# 3. Create Ignition configs
openshift-install create ignition-configs --dir=~/okd-install

# 4. Publish to Apache
sudo cp ~/okd-install/*.ign /var/www/html/okd/
sudo chown -R apache:apache /var/www/html/okd
sudo chmod 644 /var/www/html/okd/*.ign
sudo restorecon -Rv /var/www/html/okd/

# 5. Sanity check HTTP server
curl -s -I http://10.100.3.9:8080/okd/bootstrap.ign | head -n 1
Create the 6 VMs in XCP-ng / Xen Orchestra matching the specifications from Section 1. Attach the SCOS Live ISO to each VM.
Important: Power on only the bootstrap VM and the three control plane VMs at this stage. Leave the two compute VMs powered off until Section 7.
The worker.ign file is only a lightweight pointer that tells each worker to fetch its real configuration from https://api-int.okd.domain.int:22623/config/worker. While the bootstrap node is still behind HAProxy on port 22623, it can only serve control plane configurations and returns HTTP 500 for worker requests. Booting the workers after the bootstrap node has been removed means they only reach healthy control plane nodes and pull their configuration on the first attempt.
Once each VM boots into the live environment (network device enX0 pulls DHCP), run coreos-installer. Verify your local virtual disk name with lsblk (/dev/xvda on XCP-ng virtual disks):
sudo coreos-installer install /dev/xvda --ignition-url=http://10.100.3.9:8080/okd/bootstrap.ign --insecure-ignition
sudo reboot
sudo coreos-installer install /dev/xvda --ignition-url=http://10.100.3.9:8080/okd/master.ign --insecure-ignition
sudo reboot
Make sure the VMs boot from their virtual hard drives on reboot rather than looping back into the ISO.
From the Helper VM:
openshift-install wait-for bootstrap-complete --dir=$HOME/okd-install --log-level=info
When wait-for bootstrap-complete outputs:
INFO It is now safe to remove the bootstrap resources
backend okd_k8s_api_be
    balance roundrobin
    server fedora-cp-1 10.100.3.4:6443 check
    server fedora-cp-2 10.100.3.5:6443 check
    server fedora-cp-3 10.100.3.6:6443 check

backend okd_machine_config_be
    balance roundrobin
    server fedora-cp-1 10.100.3.4:22623 check
    server fedora-cp-2 10.100.3.5:22623 check
    server fedora-cp-3 10.100.3.6:22623 check
sudo systemctl reload haproxy
Now power on fedora-cmp-1 and fedora-cmp-2 with the SCOS Live ISO attached. Once each boots into the live environment, run the installer (verify the disk name with lsblk first):
sudo coreos-installer install /dev/xvda --ignition-url=http://10.100.3.9:8080/okd/worker.ign --insecure-ignition
sudo reboot
After the reboot (booting from the virtual hard drive, not the ISO), the workers pull the ~450KB configuration from the control plane nodes through HAProxy, write their partitions, and reboot.
Worker nodes require manual Certificate Signing Request (CSR) approvals before joining the cluster. The kubelets first request client join certificates, then roughly 30 to 60 seconds later request serving certificates, so the approval command must be run repeatedly. The loop below runs it every 30 seconds for about 10 minutes and covers both phases.
Run on the Helper VM:
export KUBECONFIG=$HOME/okd-install/auth/kubeconfig

# Approve client join certificates, then serving certificates
for i in $(seq 1 20); do
  oc get csr -o go-template='{{range .items}}{{if not .status}}{{.metadata.name}}{{"\n"}}{{end}}{{end}}' | xargs --no-run-if-empty oc adm certificate approve
  sleep 30
done
If any node is still missing afterwards, run the loop again.
Check that all 5 nodes report Ready:
oc get nodes
Run the final installer watcher to monitor cluster operators:
openshift-install wait-for install-complete --dir=$HOME/okd-install --log-level=info
When finished, the terminal outputs the Web Console URL (https://console-openshift-console.apps.okd.domain.int) and the kubeadmin password.
The KUBECONFIG export above only lasts for the current shell session. Copy the kubeconfig so oc commands keep working after logging out and back in to the Helper VM:
mkdir -p ~/.kube
cp ~/okd-install/auth/kubeconfig ~/.kube/config
chmod 600 ~/.kube/config
On UPI with platform: none there is no cloud provider, so the cluster is not ready for general use when the installer exits. Two Day-1 items must be configured: the internal image registry and a default StorageClass.
The Image Registry Operator starts in a Removed state because no cloud object storage is available. Check it:
oc get configs.imageregistry.operator.openshift.io cluster -o jsonpath='{.spec.managementState}'
# Returns: Removed
Until this is addressed, internal builds and local image pushes will fail. For a lab or other non-production environment, use ephemeral storage (image data is lost if the registry pod restarts):
oc patch configs.imageregistry.operator.openshift.io cluster --type merge \
  -p '{"spec":{"managementState":"Managed","storage":{"emptyDir":{}}}}'
Once the default StorageClass below is in place, the registry can be moved to a persistent volume claim instead.
A fresh UPI cluster has no StorageClasses, so any PersistentVolumeClaim will remain Pending. This lab example uses the nfs-subdir-external-provisioner on the storage appliance / NAS (example path: 10.100.20.248:/volume1/okd).
Prerequisites: create the NFS export on your storage appliance (SAN/NAS), allow the cluster node IPs (10.100.3.0/24), and set the squash option so the provisioner can write to the share (usually no_root_squash).
oc new-project nfs-provisioner
oc adm policy add-scc-to-user hostmount-anyuid -z nfs-subdir-external-provisioner -n nfs-provisioner

helm repo add nfs-subdir-external-provisioner https://kubernetes-sigs.github.io/nfs-subdir-external-provisioner/
helm install nfs-subdir-external-provisioner nfs-subdir-external-provisioner/nfs-subdir-external-provisioner \
  --namespace nfs-provisioner \
  --set nfs.server=10.100.20.248 \
  --set nfs.path=/volume1/okd \
  --set storageClass.name=nfs-client \
  --set storageClass.defaultClass=true
Verify, and mark the class as default manually if it is not already:
oc get storageclass
oc annotate storageclass nfs-client storageclass.kubernetes.io/is-default-class="true" --overwrite