XCP-ng 8.3 updates announcements and testing
-
Updated my Lab Pool.
For the Test:Reboot your VMs, starting with Linux VMs that use PCI passthrough (GPU, NVMe, NIC). The new HVM PIRQ default applies to every VM at its next boot. If you set platform:hvm-pirq on a VM yourself, that value is kept. Devices that worked before must still work, with similar performance and CPU usage. If one doesn't, check whether platform:hvm-pirq=true brings it back, and tell us.
-> No such VM on my Lab Pool, not tested
Run your usual Xen Orchestra backups (incremental with NBD, full) and a restore. Every NBD backup now goes through new code (tapdisk's NBD server, parallel requests), so they must complete, and shouldn't get slower.
-> ran a full backup job and an incremental backup job. No issues. No diffrences to previous backups.
Watch the disk performance of your busiest VMs, on VHD and QCOW2 SRs. The locking change in tapdisk applies to every VM disk, not only QCOW2.
-> Didn't notice any performance issues.
After running the snapshot_fixer.py script if necessary, take, revert to and delete snapshots, including on VMs with several disks, and check that the VMs and their disks are as expected afterwards. The fix changes how xapi handles VDIs during reverts and SR scans.
-> Performed test with 3 VMs, 1 with one disk, 2 with 2 discs. -> No issues seen.
-
Installed on my usual test hosts.
Backups seem to have major ussues for me, much less stable with these updates. On two different test pools i ran into a similar issue. These pools are different hardware, one pool uses CBT for backups, one does not.
Pool 1:
Started a backup after running the updates, 2 VMs in the job hung on first run requiring restarting XO and the hosts tool stack. When trying to clear the leftover snapshots one VM got stuck with "VBD.unplug_force", restarting the toolstack didn't help with this i had to reboot the entire host to remove it. Second attempt backups ran ok.Third attempt, VM hung again, same story as above, had to reboot the whole host to clear the "VBD.unplug_force"
Pool 2:
Backup job completed however again two VMs got stuck at the end with "VBD.unplug_force" and "VDIs attached to Control Domain"
On one VM the backup showed "Error: operation timed out" despite it otherwise finishing.Is there a way to revert these updates for now? They are test hosts but i do like backing up the test VMs on them.
-
Same i am continuing to have backup issues.. multiple reboots, disabled NBD backup getting stuck.
Is this the correct procedure to downgrade from the updates?
yum history list | head -n 6
yum history undo <ID> --enablerepo=xcp-ng-testing
reboot
rpm -q xapi-core blktap xen-hypervisor sm
Or do you advise doing -
yum downgrade blktap-3.55.5-11.3.xcpng8.3to just downgrade the blktap?Edit - Actually looks like diabling NBD might have worked... I thought backup was still runing.. no the full backup completed this time and a scheduled delta job is running.... NBD is enabled on the delta job.
-
I was able to revert by running
yum history listFinding the transaction from todays updates then running
yum history undo <id>I did this on both pools, doing the slaves first then the master. (Reverse order of updating) and so far everything is back to normal.
-
@acebmxer I was able to run successfully one time after multiple failures. I don't think its consistently reliable. Interesting that disabling NBD helped though. I didn't try that before reverting.
-
@acebmxer said:
(...)
yum history undo <ID> --enablerepo=xcp-ng-testing
(...)Your're lucky ! this is a risky operation we don't recommend to downgrade because some packages like xapi are not handling this properly, prefer other workarounds if there are any (like disabling nbd until @storage team suggest a better option)
Let me thank you again @flakpyro for this regression report it is very valuable to us,
-
@lmolina Updates ran fine, but I'm having CR backup problems too... Mostly ran fine, but I now have 3 stuck with
VBD.unplug_force. I can't get them to clear. I'll have to try harder before I revert updates. -
@rzr I was worried about this because of XAPI. Luckily i have a host thats not currently running any VMs so i tried it there first hoping it was a small enough change that i could get away with it. Good to know i could have just disabled NBD for now though!
-
@acebmxer said:
(...)
yum history undo <ID> --enablerepo=xcp-ng-testing
(...)Your're lucky ! this is a risky operation we don't recommend to downgrade because some packages like xapi are not handling this properly, prefer other workarounds if there are any (like disabling nbd until @storage team suggest a better option)
Let me thank you again @flakpyro for this regression report it is very valuable to us,
I didn't run the commands I stated. As I was asking first.. I did the command @flakpryo
Of course this is was before i saw your post. As this is the home lab i am fine with if it blows up. but for others this is good to know.
-
We have just released security updates for
ca-certificates.Full details are available on the blog:
https://xcp-ng.org/blog/2026/10/22/october-2026-security-updates-3-for-xcp-ng-8-3-lts/ -
Ok, so what's the scoop here? Safe to roll this out or wait a few days? I just saw the notice in my XO that there are updates and I don't want to wreck my system right now after fixing a few other "issues".
[edit] I see this is just the certificate update so pushing it out and listening to servers reboot.
-
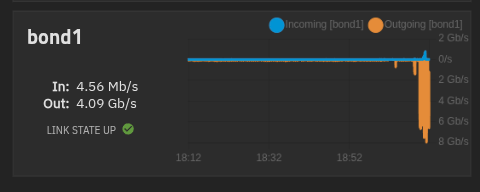
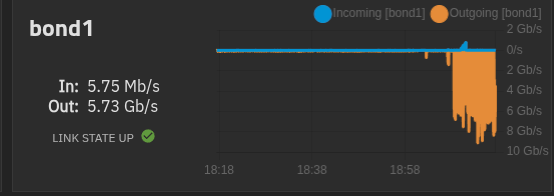
I reinstalled the updates, and confirm backups work with NBD disablled in backup job. - I missed the part about NBD in the notes..
However the task stay at 0% while i can see traffic on my trunas..


-
jr-m4 said:
Updated two dev-pools successfully!
new-xcp-dev: 2x Dell Inc. PowerEdge R650xs
old-xcp-dev: 3x Dell Inc. PowerEdge R350 (HA)I even mistankenly did a wrong updating order on old-xcp-dev. And neglected to disable HA before updating, leading to two hosts being updated and promoting the next master. And by chance the last master was the non-updated one. Here I disabled HA, but couldn't promote another master (not unexpected)... Post update, and everything seems to be good anyways. And HA re-enabled successfully
Note:
No further testing other than the hosts booting and showing good life signs have been done, yet.I'm now also seeing issues with backups being stuck for multiple hours.
Update: Correction. I'm now having issues with almost everything on both pools.- migrations
- snapshots
- changing status e.g. rebooting or hard shut down of VMs
-
@lmolina @olivierlambert Sorry, but this update got ugly fast. CR backups got stuck. Migrations got stuck. VMs would not start any more. After reverting all the patches and rebooting all hosts I had several VMs that would not start again (including primary XO) because the VDIs stuck marked as activating. It took some time to fix them but at least there was no data loss. Some backups lost their snapshots and had to revert to full backups again.
-
Some message formats changed between the two releases, so VMs started before the update (with an 11.3 tapdisk and tapback) can’t understand some of the changed commands. Rebooting XCP-ng or doing an RPU should work. Since not every command is affected, restarting tapback is usually enough: systemctl restart tapback.service
We're going to work to avoid that. -
Rebooting hosts and/or VMs doesn't solve the problems.
As @andrew said. This one got ugly. But this is also why we test stuffUpdate:
Doing a "Rescan all disks" on the SR (lvmohba), seems to help out a little bit. But not everything.
Some VMs were able to be started again. But others are still showing problems and erroring out"The VDI is not available [opterr=['MAP_DUPLICATE_KEY', 'VDI', 'sm_config', 'OpaqueRef:7---------2c1b', 'activating']]", -
@jr-m4 I had this issue on one of the pools i tested on as well and was able to fix the issue by following the fix here:
https://xcp-ng.org/forum/topic/10603/sr_backend_failure_46-the-vdi-is-not-available-not-detached-cleanly/3 -
@flakpyro Hello,
It would be preferred to use another method.
You can use theresetvdis.pyscript in the/opt/xensource/sm/to reset values instead,
usingvdi-forgetis unadvised in this case, it can cause issues by losing information that are stored in XAPI about VDIs./opt/xensource/sm/resetvdis.py single <VDI UUID> -
@flakpyro Hello,
It would be preferred to use another method.
You can use theresetvdis.pyscript in the/opt/xensource/sm/to reset values instead,
usingvdi-forgetis unadvised in this case, it can cause issues by losing information that are stored in XAPI about VDIs./opt/xensource/sm/resetvdis.py single <VDI UUID>I was just about to look at maybe doing what @flakpyro suggested. More likely I would've just restored from backup. As this is dev-instances, and non-important.
But your
resetvdis.pysuggestion solved it entirely! Thanks for the quick tip! -
Now trying to see if pool works with generic operations.
Trying to do a RPR on new-xcp-dev. And I'm met with
Ofcourse there are no backups being run. They are even disabled right now. And the only active task happening is "Garbage collection" on the main SR.
pool.rollingReboot
{
  "pool": "1f16dad2---------------6c8b8b7",
  "bypassBackupCheck": false,
  "shutdownPinnedVms": false
}
{
  "code": "CANNOT_EVACUATE_HOST",
  "params": [
    "VM_LACKS_FEATURE,OpaqueRef:aa5210c4-a------------1b80-9bca5d0d0f8d|OPERATION_BLOCKED,OpaqueRef:c7a08---------------a0--------------9306,VM migration is blocked during backup"
  ],
  "call": {
    "duration": 23,
    "method": "host.assert_can_evacuate",
    "params": [
      "* session id *",
      "OpaqueRef:0145019c-2a32-13bb-5951-3bca9e59e63a"
    ]
  },
  "message": "CANNOT_EVACUATE_HOST(VM_LACKS_FEATURE,OpaqueRef:aa52-----------------------9bca5d0d0f8d|OPERATION_BLOCKED,OpaqueRef:c7a0------------------------306,VM migration is blocked during backup)",
  "name": "XapiError",
  "stack": "XapiError: CANNOT_EVACUATE_HOST(VM_LACKS_FEATURE,OpaqueRef:aa521-------------------8d|OPERATION_BLOCKED,OpaqueRef:c7a08c--------------------------9306,VM migration is blocked during backup)
    at XapiError.wrap (file:///opt/xen-orchestra/packages/xen-api/_XapiError.mjs:16:12)
    at file:///opt/xen-orchestra/packages/xen-api/transports/json-rpc.mjs:38:21
    at runNextTicks (node:internal/process/task_queues:65:5)
    at processImmediate (node:internal/timers:541:9)"
}
Update:
I believe this might be related due to a VDI being orphaned, and trying to delete it results inVDI_NOT_MANAGED-error. Trying a new rescan of disks on the SR, and hopefully garbage collection will finish until Monday. Otherwise I will somehow try to forcefully destroy this VDI.Update 2:
Managed to do a RPR now.
Seems that the flag "Prevent Migration" was applied to one of the VMs. My guess is that this is applied when backups are taken. And since the backups broke with the updates. The flag never got cleared.
I did a quick visual confirmation to see that my guess of this behaviour seems correct. And it indeed sets the "Prevent migration"-flag whilst the backup runs.Running backups on my pools to see if functionality is working as intended again.
Update 3:
Maybe related, maybe not. But my backup-tests are piling up with lots ofVBD.unplug_force, that have gone on for <=30 minutes. And this is on both pools. And it seems very much so that the backup-jobs doesn't complete properly. This could also be entirely XO-related, since there has been several commits towards backups as well.Update 4:
Updated XO from source to the latest commitd2ffe, and things have not improved.
Pretty much, many actions with VDIs are problematic. I'll happily provide logs. But will only do so if I get somewhere to upload them to.
I'll be taking the weekend now. So won't be able to respond before monday,
Hello! It looks like you're interested in this conversation, but you don't have an account yet.
Getting fed up of having to scroll through the same posts each visit? When you register for an account, you'll always come back to exactly where you were before, and choose to be notified of new replies (either via email, or push notification). You'll also be able to save bookmarks and upvote posts to show your appreciation to other community members.
With your input, this post could be even better 💗
Register Login