• 0 Votes
    7 Posts
    703 Views
    Bastien NolletB
    Hello @ludalm13, Thanks for your contribution and sorry for not giving an answer earlier. We initially planned to review your PR while doing some additional work on the audit plugin, but our planning evolved and that work was postponed. We'll review your PR in the following days.
  • Backup failures with odd connection refused errors

    Unsolved Backup
    8
    0 Votes
    8 Posts
    856 Views
    C
    Just as an update on this. Did get the migrations working. Still haven't gotten the backups working. Pool is still stable otherwise. Have managed to get backups by using Veeam so it's not to much of a problem.
  • Version 9 already ;0)

    Xen Orchestra
    2
    1
    0 Votes
    2 Posts
    178 Views
    poddingueP
    Thanks for the information, @ph7 . That's a typo, for sure.
  • Native Ceph RBD SM driver for XCP-ng

    Development
    42
    3 Votes
    42 Posts
    11k Views
    dicode-nlD
    @nick.lloyd that's something out of this plugin, that's ceph native. most clusters should run on msgr2 native. which ceph versions are you running?
  • Veeam and XO backup CBT. How to avoid conflict?

    Unsolved Backup
    7
    0 Votes
    7 Posts
    443 Views
    poddingueP
    @zorro So with purge off, Veeam stayed clean for a few nights, which fits what I saw in the lab test. If I read the docs right, the cost is that XO's reference snapshot keeps its data on the SR again, which you'd notice more on thick-provisioned storage: https://docs.xen-orchestra.com/backups-and-dr/backup-types/incremental_backups#purge-snapshot-data-cbt. Storage hasn't said yet whether purge breaking another tool's chain is expected, so I'd still call this a workaround rather than the answer. If a CBT warning comes back when you add the other VMs, the Veeam task id and the time would probably help them. And keeping both makes sense to me, since Veeam doesn't do the cross-site replication you need XO for.
  • Intel GPU passthrough on windows server 2025

    Unsolved Hardware
    3
    0 Votes
    3 Posts
    183 Views
    O
    @yannsionneau I don't use Ubuntu, but I have a few linux vm's ranging from Debian 13-14 to RHEL 10 and in all of them the passthrough works fine.
  • Unable to update Windows PV driver

    Unsolved Management
    6
    4
    0 Votes
    6 Posts
    341 Views
    D
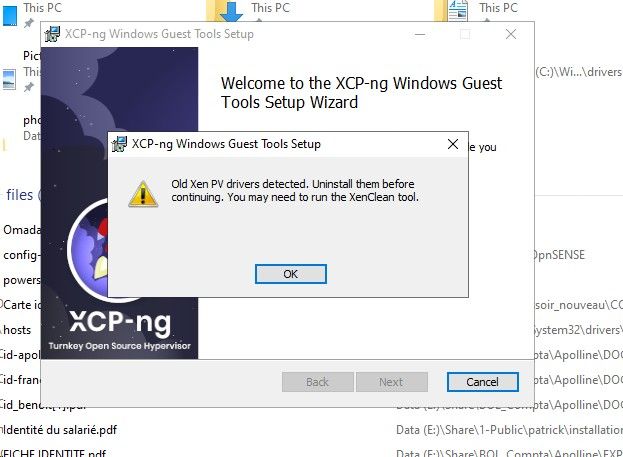
    @fred974 Hello, Could you please provide the logs produced by XenClean after its execution? If your VM couldn't boot after XenClean, XenBootFix executed from a recovery environment should get your VM working again. Instructions are available here: https://docs.xcp-ng.org/troubleshooting/windows-pv-tools/#windows-fails-to-boot-hangs-inaccessible_boot_device
  • Broadcom removed public access to VDDK download links

    Unsolved Migrate to XCP-ng
    10
    1 Votes
    10 Posts
    1k Views
    olivierlambertO
    FYI, our approach with vectura is only temporary, we have other plans in few months to get rid of this potential cat & mouse game Broadcom could do by slightly change their protocol (without even talking about the potential legal risk with it).
  • PCIe Pass-through lanes and lane performance

    Solved Compute
    80
    0 Votes
    80 Posts
    27k Views
    TeddyAstieT
    I'm also investigating on a solution to make XCP-ng opportunistically resize device BAR; in case the firmware didn't do it (or has no support for it).
  • 0 Votes
    2 Posts
    169 Views
    poddingueP
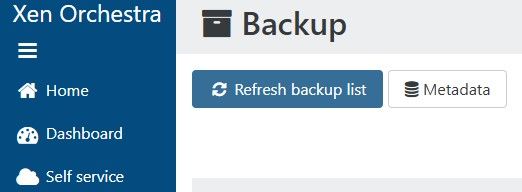
    Thanks @jr-m4, reporting the small ones is useful too. From what I can see in the code, the VM view of the restore page has that refresh button and the Metadata view only has a link back, so I think your screenshots show a real gap and not a glitch on your side. I honestly don't know whether XO 5 still takes this kind of small UI fix now that most of the work goes into XO 6, so I'll leave that to @Team-XO-Frontend to decide.
  • XOA Unable to connect xo server every 30s

    Solved Xen Orchestra
    11
    0 Votes
    11 Posts
    2k Views
    poddingueP
    Thanks @cocoon, and I owe a correction: when I said in https://xcp-ng.org/forum/post/104865 that 6.4 would make these alerts disappear for good, I overstated it. If I'm reading the code right this time, the XO server sends a ping every 30 seconds stamped with its own clock (https://github.com/vatesfr/xen-orchestra/blob/master/@xen-orchestra/rest-api/src/events/event.class.mts), and the browser compares that stamp with its own clock and shows the banner once the gap passes 40 seconds (https://github.com/vatesfr/xen-orchestra/blob/master/@xen-orchestra/web-core/lib/packages/remote-resource/sse.store.ts). So https://github.com/vatesfr/xen-orchestra/pull/9681 widened the margin from 32 to 40 seconds, but a browser whose clock runs ahead of the XO server by more than about 10 seconds would still see it. That might be why @GregBinSD saw it on the Windows PC and not on the tablet, though that's only a guess on my part. Comparing two different clocks looks fragile to me, but @Team-XO-Frontend will know far better than I do whether there's a reason it's done that way.
  • Slow SR Creation

    Unsolved Management
    14
    1
    0 Votes
    14 Posts
    1k Views
    tjkreidlT
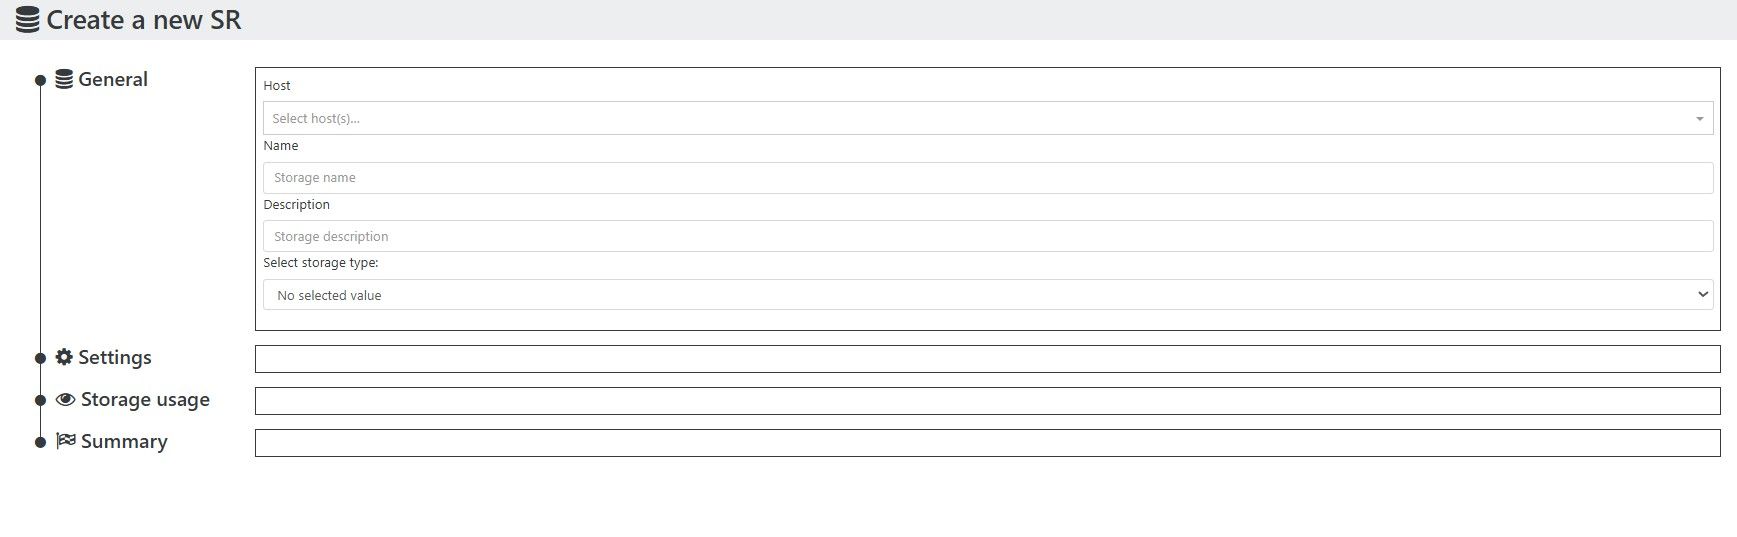
    @irtaza9 What do you see if you run top or xtop, or "xe task-list" when you start the process?
  • VDI not showing in XO 5 from Source.

    Unsolved Management
    59
    2
    0 Votes
    59 Posts
    23k Views
    C
    For some reason, we have the same issue (missing disks / snapshot-of) on our environment. (XO from source commit a5077) This is a major issue for us. We use Terraform to manage our VMs, and the missing VDIs are causing Terraform to fail. As a result, we are currently unable to manage our VMs using Terraform. ➜ dacsvm-db02 git:(main) tofu plan -var-file="dacsvm-db02.tfvars" module.vm.xenorchestra_vm.vm: Refreshing state... [id=e36fcd8a-b88c-42f7-6d61-2aa639f63b4a] Planning failed. OpenTofu encountered an error while generating this plan. ╷ │ Error: Could not find client.VDI with query: {VDIId:cad7d739-35c2-4585-9991-4c2f3fc6531c SrId: NameLabel: NameDescription: Size:0 VBDs:[] Parent: PoolId: Tags:[]} │ │ with module.vm.xenorchestra_vm.vm, │ on ../modules/vm/main.tf line 16, in resource "xenorchestra_vm" "vm": │ 16: resource "xenorchestra_vm" "vm" { │ ╵
  • Incremental Backup Question

    Unsolved Backup
    3
    1
    0 Votes
    3 Posts
    248 Views
    florentF
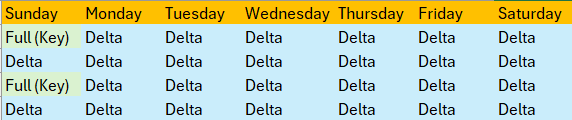
    @Velocity1192 If you can wait a little, we are atively working on the new XO6 backup job uI, that will come with some changes : one schedule per job, but with conditionnal actions You will run an incremental job, and will be able to define that the schedule of sunday is a full,and even run a healthcheck on it The ETA is on 6.11 ( next month release )
  • Node.js October 21, 2026 Security Releases

    Xen Orchestra
    6
    0 Votes
    6 Posts
    1k Views
    poddingueP
    @acebmxer I haven't run your script, so I can't vouch for the log lines, but the systemctl status check looks like the safer of the two to me. It shows the binary the service is really running. Whichever node comes first in your shell can be a different one if more than one Node is installed. For XOA I'd go with what @Danp said above.
  • OKD on XCP-ng

    Moved Infrastructure as Code xcp-ng okd openshift rocky fedora
    10
    0 Votes
    10 Posts
    884 Views
    D
    For anyone else who steps through this, I've also installed the latest xen-guest-agent with the below process. Repeat for each host in the environment, 1 at a time from your Helper VM. ### ssh into your helper ### oc debug node/fedora-cmp-1/2/3 chroot /host cd /var/tmp curl -LO https://gitlab.com/xen-project/xen-guest-agent/-/jobs/6041686376/artifacts/raw/RPMS/x86_64/xen-guest-agent-0.4.0-0.fc37.x86_64.rpm sudo rpm-ostree install /var/tmp/xen-guest-agent-0.4.0-0.fc37.x86_64.rpm mkdir /var/tmp/xga && cd /var/tmp/xga rpm2cpio ../xen-guest-agent-0.4.0-0.fc37.x86_64.rpm | cpio -idmv ### From your helper... DRAIN YOUR WORKERS ### oc adm drain fedora-cmp-1/2/3 --ignore-daemonsets --delete-emptydir-data ### log back into fedora-cmp-1/2/3... ### sudo systemctl reboot ### from helper ### oc adm uncordon fedora-cmp-1/2/3 ### login to fedora-cmp-1/2/3 ### chroot /host sudo systemctl enable --now xen-guest-agent And then from XO this is what your VMs will look like. [image: image.jpeg]
  • 1 Votes
    5 Posts
    474 Views
    poddingueP
    Good to hear block mode did it. If I'm reading XO's troubleshooting page right, that 5-minute wait is a setting you can raise: httpInactivityTimeout under [xapiOptions] in a file like /etc/xo-server/config.httpInactivityTimeout.toml, then a restart of xo-server (https://docs.xen-orchestra.com/backups-and-dr/backup_troubleshooting#error-http-connection-has-timed-out). That path is the XOA one, and I don't know where the ronivay installer keeps its config, so check that first. The page calls it a workaround and says the slow host is the real thing to look at, which could fit your SMR-disk theory, but I haven't tried anything close to a 3 TB qcow2 delta myself. For the close() error, unless I'm misreading the code, XO closes the source after the failed start and only logs a warning before falling back to a full, so I'd guess it's noise from the timeout and not a second bug. The stuck tapdisks look more like one for @Team-Storage, and I don't know if a keep-alive during the delta computation is planned.
  • Enabling Intel APICv for better performance

    Development
    2
    3 Votes
    2 Posts
    539 Views
    T
    Sharing some results. I enabled this on my homelab server, a Dell R630 with Intel Xeon E5-2630 v4 (Broadwell). No adverse impact noticed. The CDM results on Windows is higher than previous runs however, I do not go in depth with I/O benchmarking. (I am using the latest win-pv-drivers on Windows and the rust-based guest tools on Linux) Controller is in HBA mode. VM SR is using SMAPIv3 (ZFS, RAID-0, noop scheduler) [image: R630_XCP-ng_APICv.png] CDM results. Windows Server 2019 4 vCPU/8GB RAM/single VHD: [image: 2610_WIN2019_ZFS.png] I installed ScyllaDB on Alma Linux 10.2 (4 vCPU/8GB RAM & two VHDs, ScyllaDB uses a dedicated drive for data) with io_uring enabled and noop scheduler set on VM. Here are the IOTune results from the ScyllaDB installation: Measuring sequential write bandwidth: 826 MiB/s (deviation 13%) Measuring sequential read bandwidth: 1061 MiB/s (deviation 6%) Measuring random write IOPS: 50791 IOPS (deviation 11%) Measuring random read IOPS: 62977 IOPS (deviation 16%)
  • 2 Votes
    5 Posts
    648 Views
    J
    @MrQ said: @jr-m4 thank you so much for testing this updated driver. Just to make sure, I understand now that you confirm the driver is working as expected and the issues you had were not related to it? Or are there any problems still with this new driver? Many thanks again for spending the time to test and report. Hi Yes. I believe I was chasing a red herring of my own doing. I have not found anything actually problematic with this driver at all.
  • Are there any downsides to using CBT when doing backups?

    Unsolved Backup
    10
    0 Votes
    10 Posts
    754 Views
    A
    @poddingue Thank you!