XCP-ng
    • Categories
    • Recent
    • Tags
    • Popular
    • Users
    • Groups
    • Register
    • Login

    Backup fails with "Body Timeout Error", "all targets have failed, step: writer.run()"

    Scheduled Pinned Locked Moved Solved Backup
    114 Posts 21 Posters 16.9k Views 22 Watching
    Loading More Posts
    • Oldest to Newest
    • Newest to Oldest
    • Most Votes
    Reply
    • Reply as topic
    Log in to reply
    This topic has been deleted. Only users with topic management privileges can see it.
    • olivierlambertO Offline
      olivierlambert Vates 🪐 Co-Founder CEO
      last edited by

      I have a theory that I'd like you to test on a specific branch. It might be an Undici bug, but I'm far from being sure.

      You need Node >=22.19 to make it work. Switch to the branch named fix_undici_paused_parser_crash, build it and try again.

      christopher-petzelC 2 Replies Last reply Reply Quote 0
      • christopher-petzelC Offline
        christopher-petzel @olivierlambert
        last edited by

        @olivierlambert Good news. This morning, I built on the fix_undici_paused_parser_crash branch and manually ran the metadata backup job 10 times and did NOT get an error. Previously, running the job manually could result in the body timeout error, so we have progress.

        I will stay on this build during this week, let the scheduled metadata backups run, and report back by this Friday.

        M G 2 Replies Last reply Reply Quote 2
        • M Online
          MajorP93 @christopher-petzel
          last edited by MajorP93

          @christopher-petzel Thank you for testing this! I am also interested in this fix since I encounter this issue from time to time. Unfortunately my testing environment / lab is currently unavailable which is why I wasn't able to compile & deploy this branch myself.

          1 Reply Last reply Reply Quote 0
          • G Offline
            GregBinSD @christopher-petzel
            last edited by GregBinSD

            @christopher-petzel
            Great news!
            I will test and report after it is available in a global update.
            Thank you Christopher.

            1 Reply Last reply Reply Quote 0
            • christopher-petzelC Offline
              christopher-petzel @olivierlambert
              last edited by

              @olivierlambert No metadata backup errors in the 4 scheduled backups since Monday, while on the fix_undici_paused_parser_crash branch. Previously, I would not have more that 1 day without an error. Between manual and scheduled backup jobs, I've not been able to recreate the error on this test branch.

              This is good to see again...
              6f8b9214-c5d9-4aef-abfa-b982dcccbe0b-image.jpeg

              J 1 Reply Last reply Reply Quote 0
              • olivierlambertO Offline
                olivierlambert Vates 🪐 Co-Founder CEO
                last edited by

                Excellent 🙂 so it was an undici bug after all… Now I'm making sure @Team-XO-Backend won't miss it 👍

                1 Reply Last reply Reply Quote 2
                • J Offline
                  JB @christopher-petzel
                  last edited by

                  @christopher-petzel Unfortunately, for me, it still has an error.

                  7425c362-284f-41d1-8fc5-ce89cc4edf4f-image.jpeg

                  commit c5fae

                  M 1 Reply Last reply Reply Quote 0
                  • M Online
                    MajorP93 @JB
                    last edited by

                    @JB Yes makes sense. You are not on the branch that already has the fix. Your commit is latest master branch.
                    Either switch to the branch that got mentioned or wait for the fix to land in master.

                    J 1 Reply Last reply Reply Quote 1
                    • J Offline
                      JB @MajorP93
                      last edited by

                      @MajorP93 Ok. Thanks!

                      P 1 Reply Last reply Reply Quote 0
                      • P Online
                        pierrebrunet Vates 🪐 XO Team @JB
                        last edited by

                        @JB @majorp93 We made a smaller PR to be merged just after the release (because it is linked to almost all XAPI calls), the new branch is this one if you want to test: fix_undici_timeout
                        Same fix, just a little smaller 🙂

                        christopher-petzelC 1 Reply Last reply Reply Quote 1
                        • christopher-petzelC Offline
                          christopher-petzel @pierrebrunet
                          last edited by

                          @pierrebrunet I built on the fix_undici_timeout branch and manually ran the metadata backup job 10 times and did NOT get an error. I will stay on this build through the weekend, let the scheduled metadata backups run, and report back on Monday.

                          1 Reply Last reply Reply Quote 2
                          • T Offline
                            Tim-PT
                            last edited by

                            It looks like this is identified and solved, I'll test on a new version of XO next week at some point, but I just wanted to confirm that I've been seeing what appears to be the same problem.

                            This hasn't affected any of my full, delta or mirror backups, on any of the NFS targets - but it does affect two different Pool metadata & xo config backups. Both on different NFS targets on different schedules.

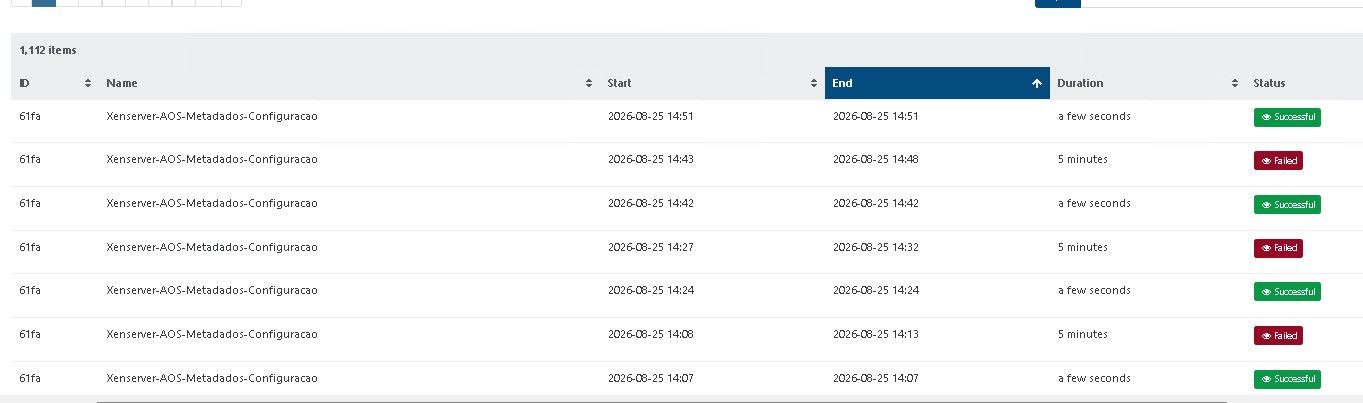
                            It's an infrequent failure, sometimes not failing for a couple of days, but sometimes failing up to 3 or 4 times per day - this is on an hourly schedule.
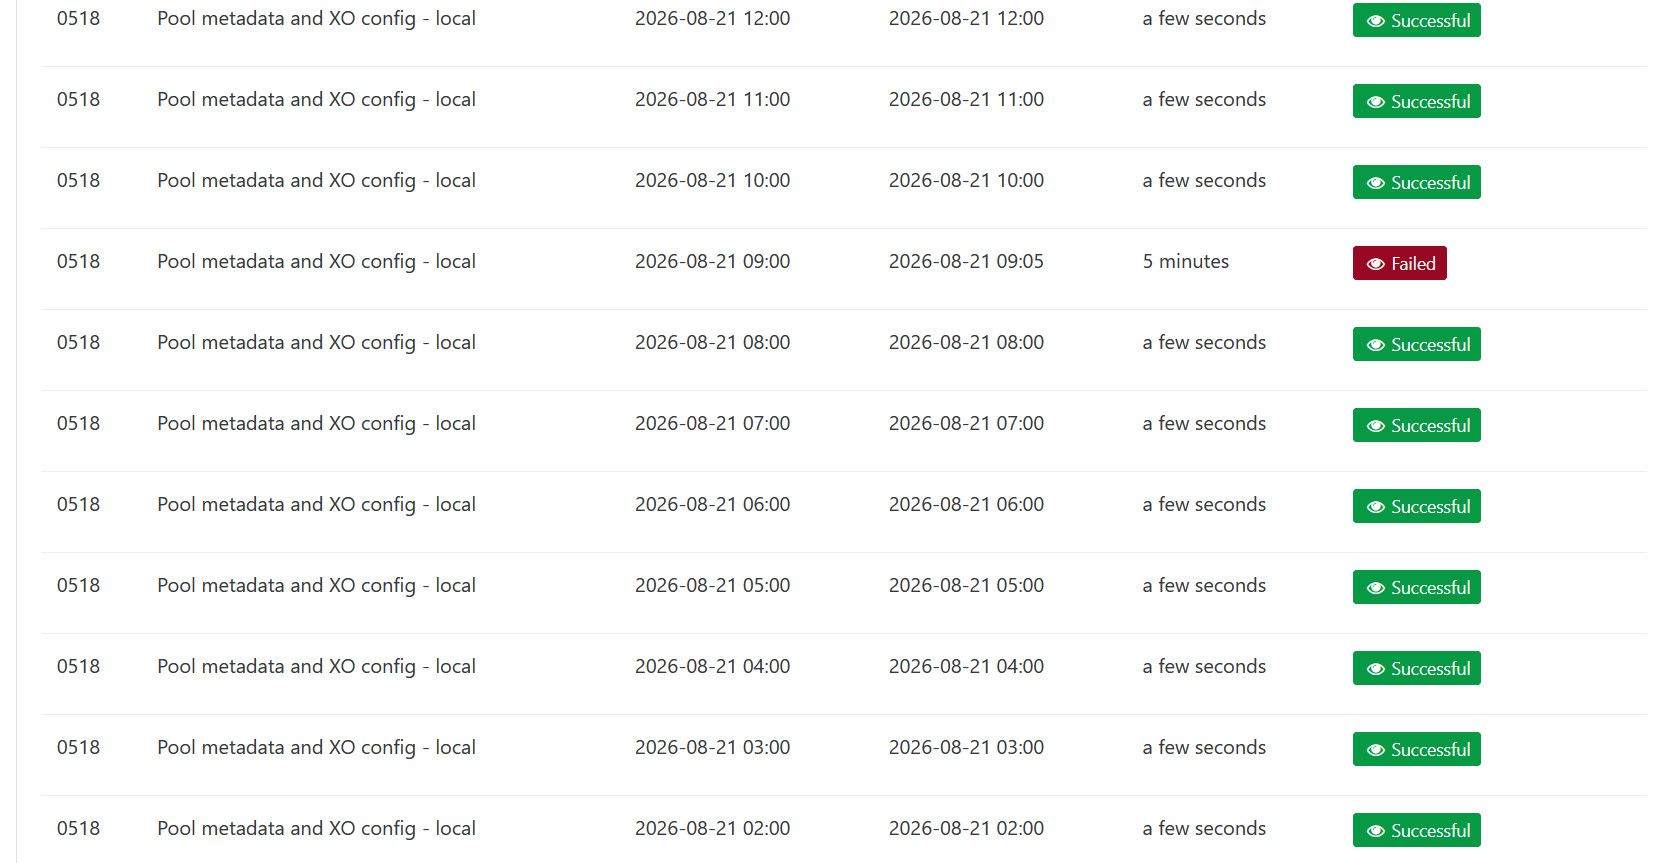
                            912ddd51-e6c1-4a62-8529-79d6b2fe8ad0-image.jpeg

                            My most recent failure on the hourly job was yesterday morning, the one before that was almost 24 hours earlier.
                            This is currently on Xen Orchestra, commit 24913 but it was also noticeable on a version from the end of July.

                            From what I've read, I'm guessing the fix will be in the main branch soon enough and an update will solve it, but if there's any useful information I can provide, please let me know.

                            poddingueP 1 Reply Last reply Reply Quote 1
                            • poddingueP Offline
                              poddingue Vates 🪐 @Tim-PT
                              last edited by

                              Thanks for the feedback so far, folks! 👍

                              christopher-petzelC 1 Reply Last reply Reply Quote 1
                              • christopher-petzelC Offline
                                christopher-petzel @poddingue
                                last edited by

                                @poddingue On the fix_undici_timeout branch this weekend, all scheduled metadata backups completed sucesfully.

                                poddingueP 1 Reply Last reply Reply Quote 1
                                • poddingueP Offline
                                  poddingue Vates 🪐 @christopher-petzel
                                  last edited by

                                  That's great news, thanks, @christopher-petzel ! 👍

                                  1 Reply Last reply Reply Quote 0
                                  • J Offline
                                    JB
                                    last edited by

                                    0f9a7699-7d49-4dce-a588-e7e999730275-image.jpeg

                                    commit 9cdaf

                                    christopher-petzelC 1 Reply Last reply Reply Quote 0
                                    • G Offline
                                      GregBinSD
                                      last edited by

                                      Here is my story:
                                      I responded to the notice regarding the latest update of the main branch, Master, commit 9cdaf, by updating the XO-CE vm, rebooting the XO-CE vm, bringing all 3 XCP-ng hosts on line, and then running the XO-CE GUI and selecting Pool Rolling Update.
                                      The rolling update cycled through all 3 hosts in the pool.
                                      I then attempted to run a pool metadata and xo_config backup.
                                      It failed by timing out at 5 minutes.
                                      I decided to shutdown the pool master, so I transferred all VMs to the other 2 hosts and shutdown the master for 15 seconds. I powered on the master, and transferred the VMs back to the master.
                                      I shutdown the other 2 hosts, and then powered them back on. All hosts are indicating "green" status.
                                      At this point I attempted to run the pool metadata and xo_config backup, and it ran successfully.
                                      I waited 2 minutes and ran it again, with success again!
                                      Lastly, I powered down the other 2 hosts, and with the VMs all running on the master, I ran the pool metadata and xo_config backup again, with apparent success.
                                      If someone can tell me the location of the logs that recorded this operation, I will look at them closely to confirm that the pool metadata and xo_config backups actually took place.
                                      Thank you.

                                      G 1 Reply Last reply Reply Quote 0
                                      • G Offline
                                        GregBinSD @GregBinSD
                                        last edited by

                                        Here is the log for the GUI Backup function:
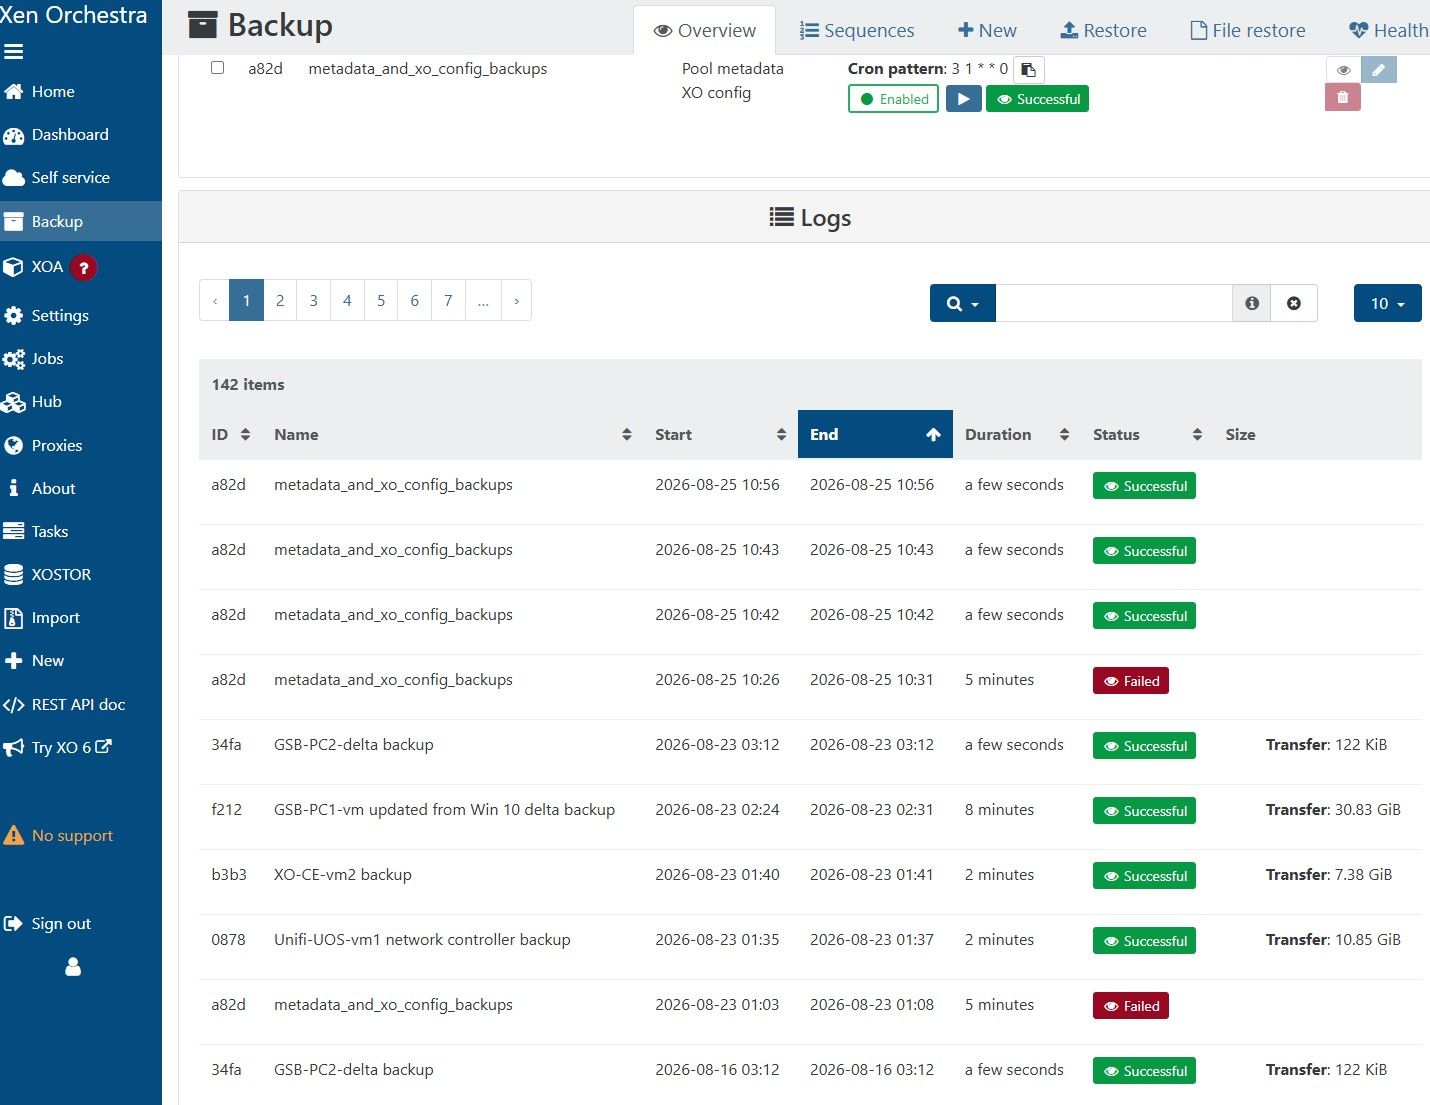
                                        1dab5aec-6f9a-4338-bf7d-dab065e17e43-image.jpeg

                                        1 Reply Last reply Reply Quote 0
                                        • christopher-petzelC Offline
                                          christopher-petzel @JB
                                          last edited by

                                          @JB @gregbinsd The fix has not been merged with the master branch yet, so you won't have the fix yet. Follow this pull request https://github.com/vatesfr/xen-orchestra/pull/10282

                                          When you see an entry at the end of the activity log which says something like ' merged commit [commit ID] into master' then you'll know the fix has been added to the master branch.

                                          It's important to know that they could close this pull request without committing it to the master branch if they want to approach the resolution in a different way (this has already happened once with this issue).

                                          J K 2 Replies Last reply Reply Quote 0
                                          • J Offline
                                            JB @christopher-petzel
                                            last edited by

                                            @christopher-petzel Ok! Thanks!

                                            1 Reply Last reply Reply Quote 0

                                            Hello! It looks like you're interested in this conversation, but you don't have an account yet.

                                            Getting fed up of having to scroll through the same posts each visit? When you register for an account, you'll always come back to exactly where you were before, and choose to be notified of new replies (either via email, or push notification). You'll also be able to save bookmarks and upvote posts to show your appreciation to other community members.

                                            With your input, this post could be even better 💗

                                            Register Login
                                            • First post
                                              Last post