XCP-ng 8.3 updates announcements and testing
-
installed updates.... by accident i ran the linstore-testing updates. but no issues with the udpate itself.
I did download the
snapshot-fixer.pyin dry run it found to vms. I ran a full backup first and was going fine till here...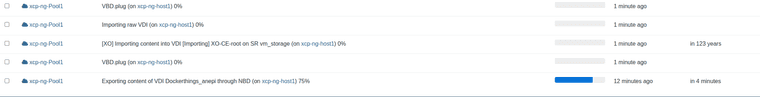
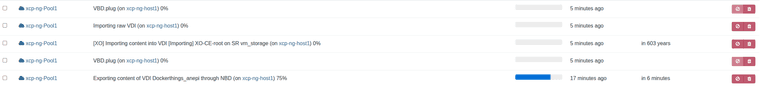
Here are some of the logs - if you have a place i can send the rest as i am not able to post all of them...
tapdisk-28167-daemonlog.txt
tapdisk-probe.txt
tapdisk-28167-fd.txt
tapdisk-28167-threads.txt
versions.txtDug into it some more. The stuck process is tapdisk
pid 28167. tap-ctl list just hangs andtap-ctl list -p 28167times out, but the other 3 tapdisks answer fine. It’s in S state, not D, so it doesn’t look like it’s waiting on the disk.28167is the one doing the NBD export of the backup snapshot for my Dockerthings_anepi VM (snapshotbf2a422e-9df3-4b3d-83f0-0fa3ff191efb, VHD onSR 4991d4aa...). That’s the export that stopped at 75%. Everything after it is stuck at 0% (VBD.plug, importing raw VDI, the XO-CE-root import), and when I tried force unplug those got stuck too. The backup job said it finished though, and the VM itself is still running fine.Ran the snapshot-fixer dry run and it found 2 VMs. I did not run the rewrite before doing the backup.
Update went through fine at 05:58, all from xcp-ng-testing, and I rebooted at 06:00, so this happened on the new packages. The linstor-testing thing didn’t install anything,
rpm -qa | grep -i linstorcomes back empty. Attached the yum history.I have the full logs (xensource, SMlog, daemon, kern) if you want them, just tell me where to send them.
yum-history-11.txtUpdate: kill 28167 (plain SIGTERM, not -9) cleared it, then the stuck tasks cancelled without a reboot. Will post if it happens again on the next backup.
-
Updated two dev-pools successfully!
new-xcp-dev: 2x Dell Inc. PowerEdge R650xs
old-xcp-dev: 3x Dell Inc. PowerEdge R350 (HA)I even mistankenly did a wrong updating order on old-xcp-dev. And neglected to disable HA before updating, leading to two hosts being updated and promoting the next master. And by chance the last master was the non-updated one. Here I disabled HA, but couldn't promote another master (not unexpected)... Post update, and everything seems to be good anyways. And HA re-enabled successfully
Note:
No further testing other than the hosts booting and showing good life signs have been done, yet. -
Updated my Lab Pool.
For the Test:Reboot your VMs, starting with Linux VMs that use PCI passthrough (GPU, NVMe, NIC). The new HVM PIRQ default applies to every VM at its next boot. If you set platform:hvm-pirq on a VM yourself, that value is kept. Devices that worked before must still work, with similar performance and CPU usage. If one doesn't, check whether platform:hvm-pirq=true brings it back, and tell us.
-> No such VM on my Lab Pool, not tested
Run your usual Xen Orchestra backups (incremental with NBD, full) and a restore. Every NBD backup now goes through new code (tapdisk's NBD server, parallel requests), so they must complete, and shouldn't get slower.
-> ran a full backup job and an incremental backup job. No issues. No diffrences to previous backups.
Watch the disk performance of your busiest VMs, on VHD and QCOW2 SRs. The locking change in tapdisk applies to every VM disk, not only QCOW2.
-> Didn't notice any performance issues.
After running the snapshot_fixer.py script if necessary, take, revert to and delete snapshots, including on VMs with several disks, and check that the VMs and their disks are as expected afterwards. The fix changes how xapi handles VDIs during reverts and SR scans.
-> Performed test with 3 VMs, 1 with one disk, 2 with 2 discs. -> No issues seen.
-
Installed on my usual test hosts.
Backups seem to have major ussues for me, much less stable with these updates. On two different test pools i ran into a similar issue. These pools are different hardware, one pool uses CBT for backups, one does not.
Pool 1:
Started a backup after running the updates, 2 VMs in the job hung on first run requiring restarting XO and the hosts tool stack. When trying to clear the leftover snapshots one VM got stuck with "VBD.unplug_force", restarting the toolstack didn't help with this i had to reboot the entire host to remove it. Second attempt backups ran ok.Third attempt, VM hung again, same story as above, had to reboot the whole host to clear the "VBD.unplug_force"
Pool 2:
Backup job completed however again two VMs got stuck at the end with "VBD.unplug_force" and "VDIs attached to Control Domain"
On one VM the backup showed "Error: operation timed out" despite it otherwise finishing.Is there a way to revert these updates for now? They are test hosts but i do like backing up the test VMs on them.
-
Same i am continuing to have backup issues.. multiple reboots, disabled NBD backup getting stuck.
Is this the correct procedure to downgrade from the updates?
yum history list | head -n 6
yum history undo <ID> --enablerepo=xcp-ng-testing
reboot
rpm -q xapi-core blktap xen-hypervisor sm
Or do you advise doing -
yum downgrade blktap-3.55.5-11.3.xcpng8.3to just downgrade the blktap?Edit - Actually looks like diabling NBD might have worked... I thought backup was still runing.. no the full backup completed this time and a scheduled delta job is running.... NBD is enabled on the delta job.
-
I was able to revert by running
yum history listFinding the transaction from todays updates then running
yum history undo <id>I did this on both pools, doing the slaves first then the master. (Reverse order of updating) and so far everything is back to normal.
-
@acebmxer I was able to run successfully one time after multiple failures. I don't think its consistently reliable. Interesting that disabling NBD helped though. I didn't try that before reverting.
-
@acebmxer said:
(...)
yum history undo <ID> --enablerepo=xcp-ng-testing
(...)Your're lucky ! this is a risky operation we don't recommend to downgrade because some packages like xapi are not handling this properly, prefer other workarounds if there are any (like disabling nbd until @storage team suggest a better option)
Let me thank you again @flakpyro for this regression report it is very valuable to us,
-
@lmolina Updates ran fine, but I'm having CR backup problems too... Mostly ran fine, but I now have 3 stuck with
VBD.unplug_force. I can't get them to clear. I'll have to try harder before I revert updates. -
@rzr I was worried about this because of XAPI. Luckily i have a host thats not currently running any VMs so i tried it there first hoping it was a small enough change that i could get away with it. Good to know i could have just disabled NBD for now though!
-
@acebmxer said:
(...)
yum history undo <ID> --enablerepo=xcp-ng-testing
(...)Your're lucky ! this is a risky operation we don't recommend to downgrade because some packages like xapi are not handling this properly, prefer other workarounds if there are any (like disabling nbd until @storage team suggest a better option)
Let me thank you again @flakpyro for this regression report it is very valuable to us,
I didn't run the commands I stated. As I was asking first.. I did the command @flakpryo
Of course this is was before i saw your post. As this is the home lab i am fine with if it blows up. but for others this is good to know.
-
We have just released security updates for
ca-certificates.Full details are available on the blog:
https://xcp-ng.org/blog/2026/10/22/october-2026-security-updates-3-for-xcp-ng-8-3-lts/
Hello! It looks like you're interested in this conversation, but you don't have an account yet.
Getting fed up of having to scroll through the same posts each visit? When you register for an account, you'll always come back to exactly where you were before, and choose to be notified of new replies (either via email, or push notification). You'll also be able to save bookmarks and upvote posts to show your appreciation to other community members.
With your input, this post could be even better 💗
Register Login