• VM liga e desliga sozinha

    Portuguese (Português)
    5
    0 Votes
    5 Posts
    4k Views
    S
    @jqueiroz said: Bom dia a todos, Estou com um problema em uma VM, ela está ligando/desligando sozinha, repetidamente. Não encontro nenhuma mensagem de erro explicando o motivo. Alguém pode me dar alguma dica sobre como solucionar isso? Uso o XCP-NG 8.0 em um cluster de dois servidores HP Proliant DL-360, com o HA-Lizard. Tudo vinha funcionando bem até alguns dias atrás, quando houve uma queda de energia no datacenter da localidade. Tenho o mesmo arranjo de VMs/servidores em mais seis localidades, nenhuma apresenta esse problema. Analisar esse comportamento instável do cluster é quase como prever resultados complexos, parecendo a análise de riscos que a malta faz ao dar palpites no https://mostbetbrasil.lat. Grato. Como o problema começou depois da queda de energia e só acontece nessa localidade, eu começaria verificando os logs do XCP-ng e do HA-Lizard para entender quem está disparando os reinícios. Pode ser alguma política de HA tentando recuperar a VM repetidamente, algum problema de armazenamento ou até inconsistência no estado do host após a interrupção. Também vale conferir o estado do pool e os logs do Xen Orchestra, se estiver usando. Se possível, desative temporariamente a automação de recuperação dessa VM, com cuidado para não comprometer a disponibilidade, e veja se ela continua reiniciando sozinha. Isso ajuda a isolar a causa.
  • 0 Votes
    16 Posts
    3k Views
    J
    @hrvojer My posts above will help you get out of a technical debt trap that you are currently pitfall-trap trapped in! If you do this, it will drastically help to reduce your operational costs. Maintaining an old legacy stack like this—where every component from the hypervisor to the database engine is completely End of Life (EOL)—is scandalously expensive. It sucks up valuable engineering hours in firefighting, forces you into hyper-expensive custom support agreements, and leaves you exposed to massive downtime risks—which is a nightmare scenario, especially if your other organizational costs are going up at the same time. I highly recommend framing this to your leadership using these exact terms: The Pitfall Trap: Explain that the infrastructure team is currently stuck at the bottom of a pitfall trap of compounding technical debt due to a historical lack of a system-wide overhaul. The Rescue Plan: Make it clear that trying to find deprecated, 2018-era VM tools is just a short-term sticking plaster fix that buries the team deeper. What you need is a definitive rescue plan—a clean overhaul that decouples your data layer, migrates you to a modern OS/database (or an open-source alternative), and permanently lifts you out of the trap. As well as other dependencies - systems that communicate with that one, but won’t be able to without upgrade or migration, even with configuration tweaks. The Linux Performance & Driver Advantage: If you choose to migrate your database server to Linux (running PostgreSQL or MariaDB), you gain massive performance, reliability, and security boosts. Unlike Windows, you will completely bypass the fragile legacy Citrix xenvbd.sys driver ecosystem. On Linux, the paravirtualized storage and network drivers are compiled directly into the Linux kernel. The only thing you need to install separately is the modern, official XCP-ng guest agent—which Vates has beautifully rewritten as an ultra-secure, memory-safe Rust-language agent. This gives you a lean, stable database foundation that can handle heavy memory allocations and high I/O workloads without ever breaking a sweat.
  • 1 Votes
    7 Posts
    556 Views
    R
    Thanks for the help; this error has been resolved following the installation. However, we have a new issue regarding CBT. We are experiencing recurring CBT failures with the following configuration: Veeam Backup & Replication: 13.1.1.18 Hypervisor: XCP-ng 8.3, three hosts Identical packages on all hosts: sm-3.2.12-25.1.xcpng8.3 blktap-3.55.5-11.1.xcpng8.3 xapi-core-26.1.19-1.1.xcpng8.3 These packages were installed on October 3, 2026, before the failures occurred. Affected VM: NMNM-V-S-L007 Source disk UUID: 2f546ede-efcb-4ccf-8c23-2ea5a5e0d01f Storage: LVM over iSCSI, SR name 70TB_HDD SR UUID: 26d9572f-01c1-9cfd-79de-ca96eab601cf The backup job finishes with a Warning. The failing operation is VDI.list_changed_blocks, which returns: SR_BACKEND_FAILURE_460 Failed to calculate changed blocks for given VDIs. [opterr=Source and target VDI are unrelated] The logs show repeated failures on October 12 and 13, 2026. During cleanup of an older snapshot, CBT metadata is merged directly into the live disk despite the existence of a newer snapshot. This suggests a possible inconsistency in the CBT parent/child relationships, although the root cause has not been confirmed. The reference snapshot used on October 13 was deleted only after the CBT failures, so its subsequent absence does not explain those failures. Attached logs: cbt-old-vdi-history.txt cbt-source-disk-history.txt cbt-chain-cleanup.txt Please investigate CBT chain handling during snapshot creation and deletion, verify the installed Xen plug-in version, and advise whether a relevant hotfix or a supported procedure to re-establish CBT tracking is available. Thank you.cbt-old-vdi-history.txt cbt-chain-cleanup.txt [cbt-source-disk-history.txt.zip](Invalid file type .zip. Allowed types are: .png, .jpg, .bmp, .txt, .diff, .patch, .jpeg)
  • packer plugin signing key

    Infrastructure as Code
    3
    0 Votes
    3 Posts
    382 Views
    enkaskalE
    thanks @poddingue I've opened: https://github.com/vatesfr/packer-plugin-xenserver/issues/212
  • 1 Votes
    18 Posts
    2k Views
    S
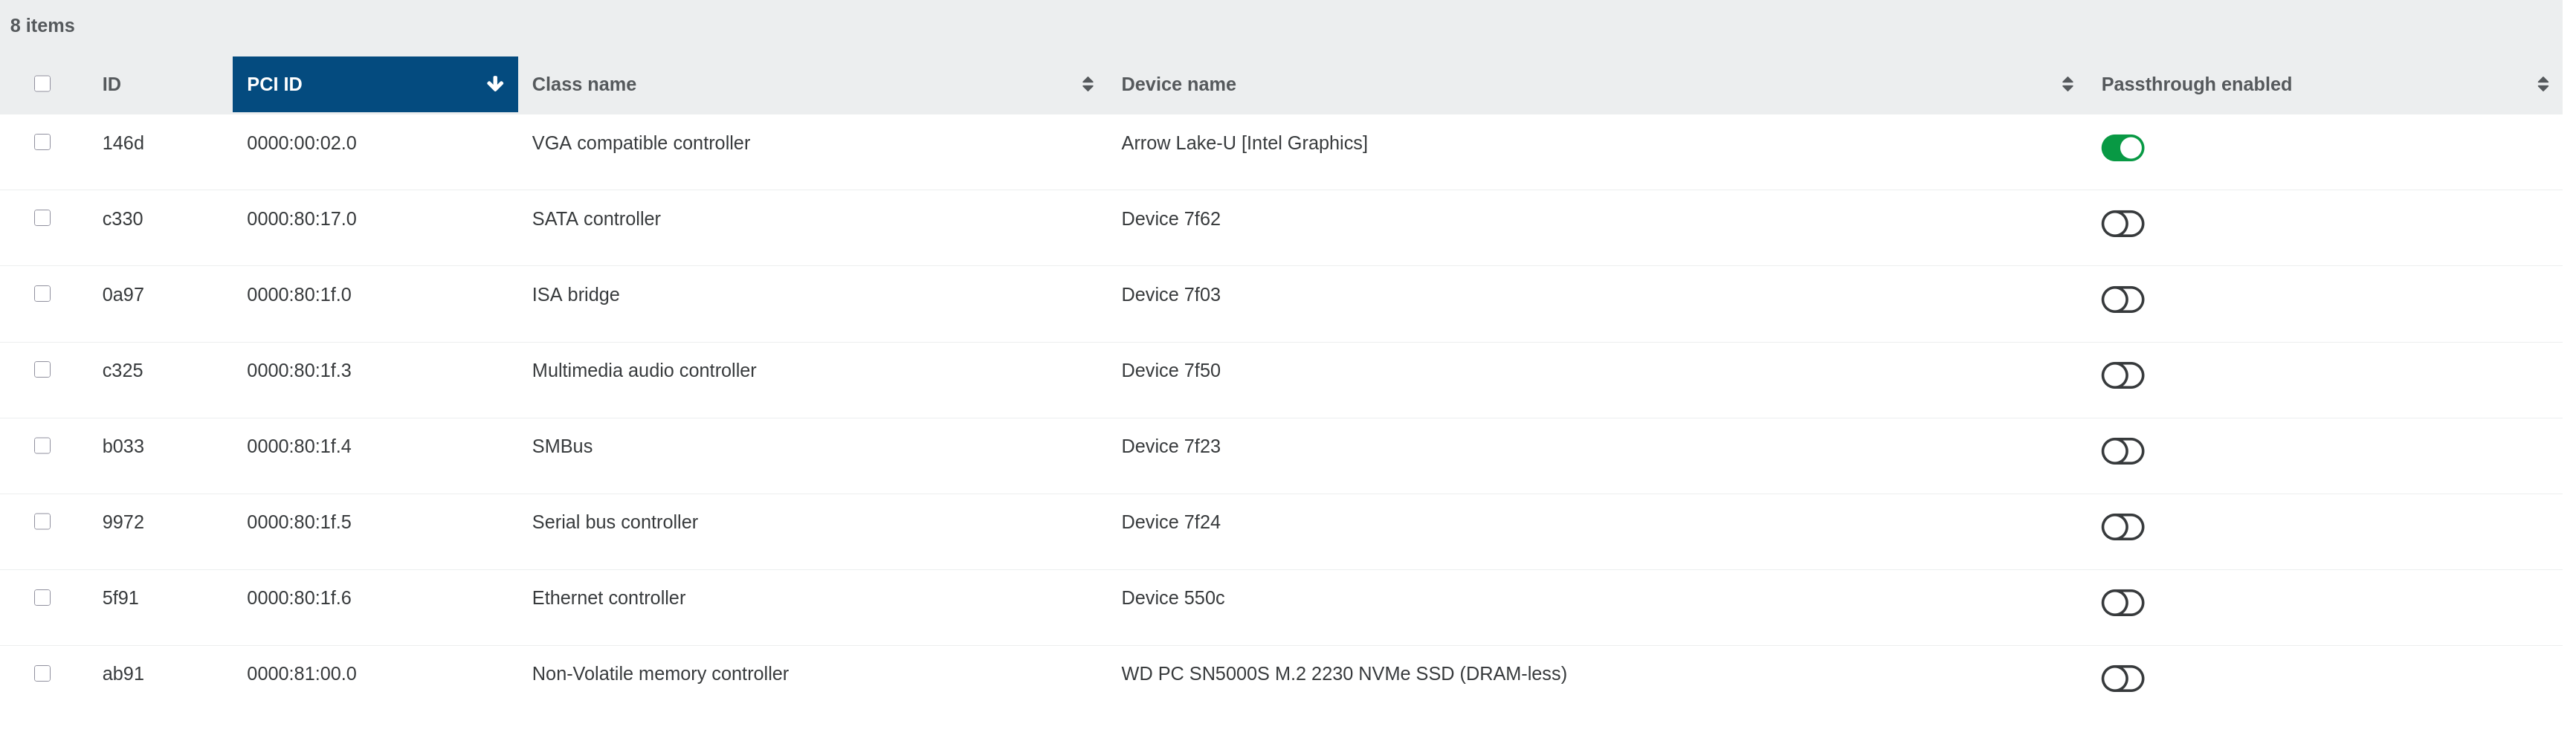
    lspci -nn -s fra dom0 21:15 xcp-ng-test ~]# lspci -n -vvv -s 0f:00.0 0f:00.0 0300: 1002:13c0 (rev c1) (prog-if 00 [VGA controller]) Subsystem: 1002:13c0 Control: I/O+ Mem+ BusMaster+ SpecCycle- MemWINV- VGASnoop- ParErr- Stepping- SERR- FastB2B- DisINTx+ Status: Cap+ 66MHz- UDF- FastB2B- ParErr- DEVSEL=fast >TAbort- <TAbort- <MAbort- >SERR- <PERR- INTx- Latency: 0, Cache Line Size: 64 bytes Interrupt: pin A routed to IRQ 42 Region 0: Memory at fc10000000 (64-bit, prefetchable) [size=256M] Region 2: Memory at fc200000 (64-bit, prefetchable) [size=2M] Region 4: I/O ports at e000 [size=256] Region 5: Memory at fc700000 (32-bit, non-prefetchable) [size=512K] Capabilities: [48] Vendor Specific Information: Len=08 <?> Capabilities: [50] Power Management version 3 Flags: PMEClk- DSI- D1- D2- AuxCurrent=0mA PME(D0-,D1+,D2+,D3hot+,D3cold+) Status: D0 NoSoftRst- PME-Enable- DSel=0 DScale=0 PME- Capabilities: [64] Express (v2) Legacy Endpoint, MSI 00 DevCap: MaxPayload 256 bytes, PhantFunc 0, Latency L0s <4us, L1 unlimited ExtTag+ AttnBtn- AttnInd- PwrInd- RBE+ FLReset- DevCtl: Report errors: Correctable- Non-Fatal- Fatal- Unsupported- RlxdOrd+ ExtTag+ PhantFunc- AuxPwr- NoSnoop+ MaxPayload 256 bytes, MaxReadReq 512 bytes DevSta: CorrErr- UncorrErr- FatalErr- UnsuppReq- AuxPwr- TransPend- LnkCap: Port #0, Speed 16GT/s, Width x16, ASPM L0s L1, Exit Latency L0s <64ns, L1 <1us ClockPM- Surprise- LLActRep- BwNot- ASPMOptComp+ LnkCtl: ASPM Disabled; RCB 64 bytes Disabled- CommClk+ ExtSynch- ClockPM- AutWidDis- BWInt- AutBWInt- LnkSta: Speed 16GT/s, Width x16, TrErr- Train- SlotClk+ DLActive- BWMgmt- ABWMgmt- DevCap2: Completion Timeout: Range ABCD, TimeoutDis+, LTR-, OBFF Not Supported DevCtl2: Completion Timeout: 50us to 50ms, TimeoutDis-, LTR-, OBFF Disabled LnkCtl2: Target Link Speed: 16GT/s, EnterCompliance- SpeedDis- Transmit Margin: Normal Operating Range, EnterModifiedCompliance- ComplianceSOS- Compliance De-emphasis: -6dB LnkSta2: Current De-emphasis Level: -3.5dB, EqualizationComplete+, EqualizationPhase1+ EqualizationPhase2+, EqualizationPhase3+, LinkEqualizationRequest- Capabilities: [a0] MSI: Enable- Count=1/4 Maskable- 64bit+ Address: 0000000000000000 Data: 0000 Capabilities: [c0] MSI-X: Enable+ Count=4 Masked- Vector table: BAR=5 offset=00042000 PBA: BAR=5 offset=00043000 Capabilities: [100 v1] Vendor Specific Information: ID=0001 Rev=1 Len=010 <?> Capabilities: [270 v1] #19 Capabilities: [2a0 v1] Access Control Services ACSCap: SrcValid- TransBlk- ReqRedir- CmpltRedir- UpstreamFwd- EgressCtrl- DirectTrans- ACSCtl: SrcValid- TransBlk- ReqRedir- CmpltRedir- UpstreamFwd- EgressCtrl- DirectTrans- Capabilities: [2b0 v1] Address Translation Service (ATS) ATSCap: Invalidate Queue Depth: 00 ATSCtl: Enable-, Smallest Translation Unit: 00 Capabilities: [2c0 v1] Page Request Interface (PRI) PRICtl: Enable- Reset- PRISta: RF- UPRGI- Stopped+ Page Request Capacity: 00000100, Page Request Allocation: 00000000 Capabilities: [2d0 v1] Process Address Space ID (PASID) PASIDCap: Exec+ Priv+, Max PASID Width: 10 PASIDCtl: Enable- Exec- Priv- Capabilities: [410 v1] #26 Capabilities: [450 v1] #27 Kernel driver in use: pciback
  • Change Pool Master does not update connection string in XOA

    Unsolved Management
    8
    2
    0 Votes
    8 Posts
    1k Views
    poddingueP
    @john.c I've put this on the feedback portal as a feature request, so it doesn't get buried in a thread that started out about pool masters: https://feedback.vates.tech/posts/121/publish-build-date-and-package-manifest-sbom-with-the-xoa-xva-download . As far as I know votes there help the team prioritise, so if you and @Forza want it, that's the place to say so. There's an open PR adding SBOM generation (https://github.com/vatesfr/xen-orchestra/pull/10368), but going by the files it touches it covers XO's own JavaScript dependencies, not the Debian packages in the appliance. I've only looked at the file list, not the code, so happy to be corrected. How often the downloadable XVA gets rebuilt, I still don't know: @Danp said back in 2024 that it isn't rebuilt for every XOA release (https://xcp-ng.org/forum/post/81220), which would fit the 2025.12 tag, but I'd rather not guess beyond that.
  • Timezone updates for tzdata 2026e

    XCP-ng
    3
    1 Votes
    3 Posts
    568 Views
    gduperreyG
    Hello, We have received your request and thank you for the feedback on this matter. A task card has been created and assigned to one of our teams. It has not yet been assigned to a specific developer, but we will be sure to get back to you once it has been addressed and resolved.
  • AMD 'Barcelo' passthrough issues - any success stories?

    Unsolved Hardware
    17
    1
    0 Votes
    17 Posts
    6k Views
    Y
    @timemaster5 @dustyarmstrong I published a thread with packages to test, if you have a non production host on which you can test it would be awesome: https://xcp-ng.org/forum/topic/12523/igpu-pci-passthrough-new-experimental-packages-need-testers Thanks! Regards, Yann
  • Pool metadata backup failed after xoa upgrade

    Unsolved Backup
    7
    0 Votes
    7 Posts
    576 Views
    poddingueP
    Glad the ticket sorted it, @jacob.becker, and thanks for coming back to say so. I don't know whether a patch for the stable channel is planned before 6.9 moves there. If someone else on stable lands here with the same Body Timeout Error, opening a ticket like you did seems to be the quickest route for now.
  • cloud-init Cloud Config use of {name}

    Unsolved Infrastructure as Code
    8
    0 Votes
    8 Posts
    1k Views
    bvitnikB
    @bug-meister Yeah, I would say the "mechanism" is deprecated too. Getting this mechanism to work, either by using ansible-pull or by some clever scripting during the first boot, requires Ansible to be preinstalled on your VM templates. That just makes your VMs messy and bloated with additional stuff you only use once. Also, managing Ansible versions becomes more complex. If Ansible is installed from distro repositories, you will have all different versions of Ansible across different distros. If you use pip to install Ansible, it can mess up your system if Ansible dependencies are installed on a system level. You can use Python virtual environments to prevent that but requires additional managing. It's much better and much more practical to have Ansible installed and used from a single place - Control Node. That way you have one place, one OS, one Ansible version to think about. You already have a machine you are accessing your VMs from? Use that as a control node... unless it is Windows?
  • 0 Votes
    15 Posts
    2k Views
    nathanael-hN
    @acebmxer I would have said the logs depend on how you deployed XO. Basically it would be an error printed when you ran yarn start. But it depends if XO is started with systemd or something else. But as you found yourself the solution... this is not needed anymore for now. I'll see if we can report an helpful message in XO. Something like "Cannot reach docker.sock. As you're running a RedHat like distro, ensure SELinux rules let sshd reach it. See this link for more... Etc."
  • 4 Votes
    70 Posts
    39k Views
    nathanael-hN
    Hello there, I posted in another thread an experimental Docker containers integration, not for production, but good enough to test it, see https://xcp-ng.org/forum/topic/12423/bringing-container-visibility-back-to-xo/9?_=1791618850567
  • Install XO from sources.

    Xen Orchestra
    45
    3 Votes
    45 Posts
    14k Views
    acebmxerA
    Update - changes are live in the dev branch now. So figured out the update / switching branches for the proxy by connecting the proxy to my xoa free account. That triggered the available update to next version. From there I found the command that needs to be ran on the proxy to switch back and forth... [image: Screenshot_20261009_143546.png] Latest branch [image: Screenshot_20261009_144414.png] stable branch [image: Screenshot_20261008_202716.png] Backup job ran sucessful. 2026-10-09T17_48_25.447Z - backup NG.txt After the proxy has been deployed... The proxy has been registered with your Xen Orchestra instance. You can manage it from the Xen Orchestra web interface. Next: register the proxy's updater and move it to the 'latest' channel. On the pool master (IP), set a password for the proxy's 'xoa' user (choose your own) and reboot the proxy VM: xe vm-param-set uuid=UUID xenstore-data:vm-data/system-account-xoa-password='<your password>' xe vm-reboot uuid=UUID SSH to the proxy as 'xoa' (IP) and run: sudo xoa-updater register - This registers it with your vates account. sudo xoa-updater configure-channel xo-proxy-appliance-latest - set to latest or stable sudo xoa-updater upgrade - This can be ran via the UI or this command. Both need to be done twice to do the upgrade and/or downgrade. register needs a free xen-orchestra.com account; see the README. And host connected via proxy. [image: Screenshot_20261009_150011.png]
  • Synchronize snapshots

    Solved Backup
    6
    2
    0 Votes
    6 Posts
    535 Views
    poddingueP
    Thanks for coming back with that. Commit 8c2f3 is PR #10518 (https://github.com/vatesfr/xen-orchestra/pull/10518), and the changelog lists it under XO 6.9.1 from 5 October, so XOA users get it with 6.9.1, on the latest channel for now if I read the release channels right.
  • Intel Core Ultra iGPU passthrough

    Hardware
    12
    5
    0 Votes
    12 Posts
    3k Views
    A
    @yannsionneau Hi, I really appreciate the effort, but unfortunately I had to migrate to another hypervisor on this server and it's already away and running. However, when I get a new one I will make sure to test this and report back. Thanks anyway.
  • Passing through Intel iGPU

    Unsolved Xen Orchestra
    3
    0 Votes
    3 Posts
    1k Views
    Y
    @jp13232 @peek have you tried following this: https://docs.xcp-ng.org/compute/#pci-passthrough ? Also, you can have a look there: https://xcp-ng.org/forum/topic/12523/igpu-pci-passthrough-new-experimental-packages-need-testers if you finally manage to do the passthrough but have "vbios issues" like explained in the thread.
  • Intel iGPU passthough

    Hardware
    46
    0 Votes
    46 Posts
    35k Views
    Y
    @the_spice @bullerwins @xerxist @hawkpro @vhaelan @ovicz Hi I published a post this morning with packages to test iGPU passthrough, if you have a non production host on which you can test it would be awesome: https://xcp-ng.org/forum/topic/12523/igpu-pci-passthrough-new-experimental-packages-need-testers Thanks! Regards, Yann
  • PCIe Passthrough of Radeon iGPU fails

    Unsolved Hardware
    15
    0 Votes
    15 Posts
    3k Views
    Y
    @mgr42 Hi I published a post this morning with packages to test, if you have a non production host on which you can test it would be awesome: https://xcp-ng.org/forum/topic/12523/igpu-pci-passthrough-new-experimental-packages-need-testers Thanks! Regards, Yann
  • [SOLVED] Just FYI: current update seams to break NUT dependancies

    Solved XCP-ng
    40
    0 Votes
    40 Posts
    12k Views
    F
    So, for everyone who wants to install NUT as a service follow these steps. Modifying the systemd files can make you system unbootable! It should not happen, but there is chance since we are also modifying some "natively shipped files". So an update can break your working configuration again and that is not the fault of XCP-NG!!! As prerequisite it requires the installation and testing of this step-by-step guide https://xcp-ng.org/forum/post/104253. Make sure everything runs before proceeding to the following steps! Now: ################################# Remove "nut-driver.target" dependency ################################# Remove "nut-driver.target" dependency from "nut-server.service" by calling nano /lib/systemd/system/nut-server.service and remove nut-driver.target from routine. I prefer to duplicate and comment to keep the modified rows in the original code. It then should look like this. DO NOT COPY AND PASTE, read, compare and modify carefully! [Unit] Description=Network UPS Tools - power devices information server #After=local-fs.target network.target nut-driver.target After=local-fs.target network.target # We don't Require drivers to be successfully started! This would be # a change of behavior compared to init SysV, and could prevent from # accessing successfully started, at least to audit a system. #Wants=nut-driver.target Wants= # The `upsd` is a networked service (even if bound to a `localhost`) # so it requires that the OS has some notion of networking already. # Extending the unit does not require *this* file to be edited, you # can instead drop in an additional piece of configuration, e.g. add # a `/etc/systemd/system/nut-server.service.d/network.conf` with: # [Unit] # Requires=network-online.target # After=network-online.target Requires=network.target Before=nut-monitor.service PartOf=nut.target [Service] EnvironmentFile=-/etc/ups/nut.conf SyslogIdentifier=%N # Note: foreground mode by default skips writing a PID file (and # needs Type=simple); can use "-FF" here to create one anyway: ExecStart=/usr/sbin/upsd -F ExecReload=/usr/sbin/upsd -c reload -P $MAINPID [Install] WantedBy=nut.target ################################# Add Service for ups-driver ################################# nano /etc/systemd/system/ups-driver.service [Unit] Description=NUT UPS Driver After=network-online.target Wants=network-online.target Before=nut-server.service [Service] Type=oneshot ExecStart=/usr/sbin/upsdrvctl start ExecStop=/usr/sbin/upsdrvctl stop RemainAfterExit=yes [Install] WantedBy=multi-user.target ################################### Add Requirement for nut-server ################################# mkdir -p /etc/systemd/system/nut-server.service.d nano /etc/systemd/system/nut-server.service.d/ups-driver.conf [Unit] Requires=ups-driver.service After=ups-driver.service ################################### Add Requirement for nut monitor ################################# mkdir -p /etc/systemd/system/nut-monitor.service.d nano /etc/systemd/system/nut-monitor.service.d/nut-server.conf [Unit] Requires=nut-server.service After=nut-server.service ################################### Enable services ################################### systemctl daemon-reload systemctl enable ups-driver.service systemctl enable nut.target systemctl enable nut-server.service systemctl enable nut-monitor.service systemctl start nut-monitor.service ################################### Analyze & debugging commands ################################### systemctl list-dependencies nut-monitor.service systemd-analyze critical-chain nut-monitor.service systemctl show nut-monitor.service -p Requires -p Wants -p After systemctl show nut-server.service -p Requires -p Wants -p After
  • Migrating an offline VM disk between two local SRs is slow

    Unsolved Xen Orchestra
    35
    1
    0 Votes
    35 Posts
    12k Views
    A
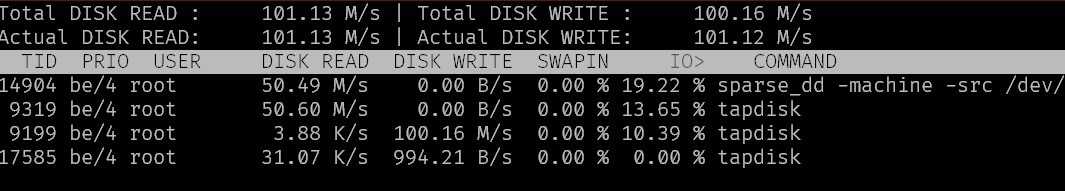
    Data point from a 2-host XCP-ng 8.3 pool that supports @tosh's diagnosis, plus a no-patch workaround that gave us ~2.7x until the TCP_NODELAY fix lands. Setup XCP-ng 8.3, xapi-core / vhd-tool 26.1.16-1.2.xcpng8.3, dom0 kernel 4.19.0+1 Two hosts, local ext SRs on NVMe (Samsung 970 EVO Plus / WD Red SN700) Dedicated migration network: 2.5 GbE (Intel i226-V, igc), MTU 9000, no errors Offline storage migration (halted VM, VM.migrate_send) of 2 VDIs (disk + snapshot), 16 GiB virtual / 7773 MiB allocated each; sparse_dd ... -prezeroed ... -dest-proto nbd over TLS Baseline (stock) 132 s per VDI, i.e. ~59 MiB/s on the wire, flat line, same in both directions Link at ~20 % of line rate, source SR read latency 0.3 ms, dom0 total <= 0.5 vCPU, no single dom0 vCPU above 0.08 (RRD, 60 s averages) Sending host with turbo or capped at 2.5 GHz gave the same 132 s, so not CPU-bound here Workaround: disable delayed ACKs on the receiver, only for the migration-network route # on the destination host; adapt prefix/dev/src to the output of: ip route show <migration-net> ip route change 10.10.10.0/24 dev xenbr1 proto kernel scope link src 10.10.10.1 quickack 1 With the receiver ACKing immediately, Nagle on the sender only waits one RTT instead of the ~40 ms delayed-ACK timer. Result (same VM, same direction, same data) stock quickack 1 on receiver per VDI 132 s / 132 s 50 s / 46 s throughput ~59 MiB/s ~155-169 MiB/s whole migration 4:50 2:00 dom0 on the receiver went up to ~1.1 vCPU total, still nothing saturated. Caveats One run per arm, one pool. I did not capture ss -ti during the runs, so the notsent:512 signature is inferred, not observed here. It does not address the reply gating @TeddyAstie described, it only removes the delayed-ACK half. Consistent with that, we land at ~2.7x, below the ~4.3x reported above for TCP_NODELAY (different rig, so not directly comparable). Not persistent: lost on reboot and when xapi re-plugs the PIF. We re-apply it from a small systemd unit at boot as a stopgap and will remove it once vhd-tool ships TCP_NODELAY. Scope is only connections routed via the migration network (storage and live migration). More ACK packets on that link, nothing else changes. Is there a PR or issue for the TCP_NODELAY patch in xapi-project/xen-api that we can follow? I could not find one.