Confirming this on a newly created VM with empty disk of 2MiB.
XO source: 635f0
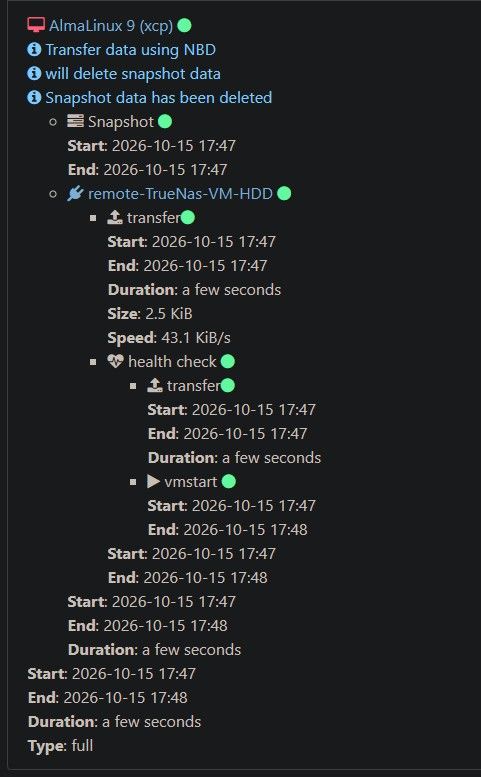
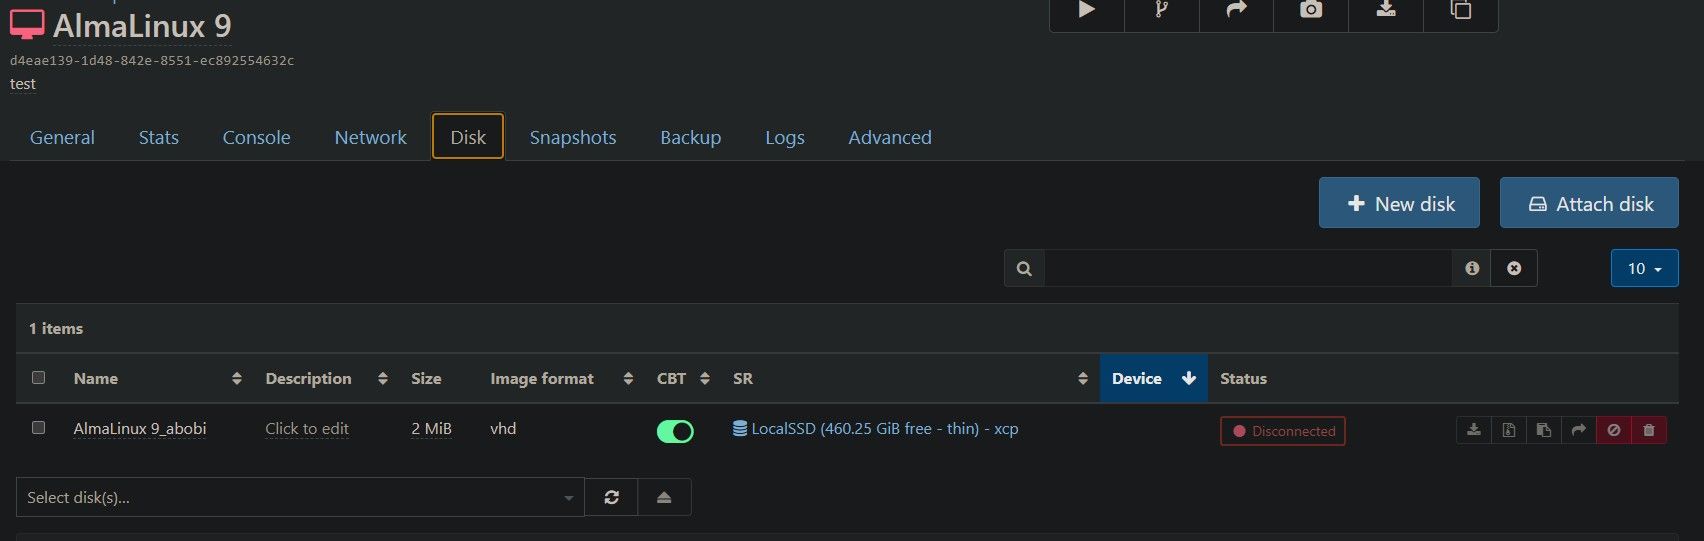
Confirming this on a newly created VM with empty disk of 2MiB.
XO source: 635f0
@Danp
Happy to hear that you too were able to reproduce the phenomenon.
Thank you for taking the time to look.
The backup jobs are Delta Backups. And other than the Health Checks-theory, I don't really have a theory of why the same job would report 28GB transfered in XO5, but 172GB in XO6.
The comment about the side panel, is more an emphasis that it is very difficult to read and extract the relevant information from. Whereas in XO5 that information was presented far easier. Both from a readability standpoint, but also accessibility. Where I have a very hard time with being able to focus on elements in XO6... But that is another topic for another day. I'm eagerly hoping for it to mature more. And it is slowly getting better.
Ah, yes. Sorry for not supplying that bit of crucial information.
XO from source: a1dba
I should also say that I believe the transfer size is from Delta Backups. And also, I find XO5 to be better descriptive of how large the amount of backup-data was sent to the remote. Whilst XO6 includes the amount of data from Health Checks sent as well. If this is the case, then the amount if Health Check data, isn't relevant imho. Or should be placed in brackets or similar.
I'm noticing that the transfer sizes for backups are different between XO5 & XO6. And this is by an order of magnitude in difference. Why is that?


If I could decipher the pop-out side-panel, then maybe I could figure it out. But I honestly can't even look at it. 
No explicit assigned migration or backup network set.
Backups generate errors somewhat randomly. As one VM won't get the "error" one time. But on the next backup run it will. And the third time it might not. This even happens on VMs that are turned off, and therefore shouldn't have any changed bytes between backups.
I've since reduced the number of NBD connections to 4. However, I'm actually still seing this happen. I thought it was resolved. But going back to confirm, proved I assumed wrong.
I have therefore uploaded a new bugtools archive from the host server on the link @poddingue sent me earlier.
I hope they can prove helpfull. If you'd like me to do anything else, then I'll happily help out.
Cheers!
@olivierlambert
Happy to hear that they are providing results to be looked at.
If there is anything else I can provide, please don't hesitate to ask. And I'll do my very best to be helpfull
5 nbd connections went fine.
8 is not.
Thanks for looking into it further as well.. If there is a hard cap on the amount of NBD connections, then that is very interesting. Because the closest I've ever been able to find regarding this setting, was the general answer of "Try and see what works for you". So if ther is indeed a hard cap, then I would propose that this is limited inside the GUI itself. e.g. if the cap is 8, then don't let the integer exceed 8.
I'm doing increasing increments of the number of connections now. So far I've done 1,2,10. And 10 does seem to be breaking again, but only on some.
Thanks as well for the link. I'm collecting the logs through xen-bugtool --yestoall now. I do wish that something like this is implemented in GUI someday. And I even made a FR feedback on it. Since I really do want to provide good information for the devs. But collecting manually isn't the most convinient way unfortunately.
Logs should be up shortly
I'm doing more backup runs. And not all of the VMs trigger the warning and fall back. But it seems quite random so far.
I did one adjustment thoug.
My number of NBD connections are set quite high, 20. And after reading this post I decided to try if lowering to 1 would have an effect. And it seems that it does. The latest backup-run hasn't showed any warnings this time... Maybe it's a false lead. But it is a behaviour I noticed this time
Unfortunately I'm not able to connect logs and such until tomorrow. But I can share further info on the configs.
The backup type is Delta.
NBD is activated and reachable
The SR on the source drive is local
Target SR is truenas nfs. Transfers are as expected.
Starting with the commits on 27th. These infos and fallback to full started happening. They have not been seen before. Resulting in transfers becoming 300% larger than expected.
All vdi are vhd
I compile from source almost daily. Hence me being very certain this is due to recent commits.
Info warning and fallback is happening even after second attempt after latest updates as well. So issue persists between reboots as well.
Is there a vates upload service I can upload to?
Or if we reset my XO trial, I can open a support tunnel for you
Since updating to XO from source on 2026-07-28 my backups have started showing issues:
Issue still persists on 2026-07-29 on latest commit (26c36) after the latest XCP-ng updates as well.
 can't compute delta OpaqueRef:4f676f19-a405-9bf7-ebb8-508240593020 from OpaqueRef:044a8fe1-7547-175f-612a-82e8df28524a, fall back to a full
 can't connect through NBD, fall back to stream export
 Backup fell back to a full
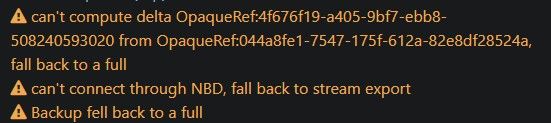
This happens to almost all of my VMs. But not on my Windows Server 2025 VM. Unsure if that is relevant though.
2026-07-27 didn't have any such notices.
Other ideas I get are:
PCI passthrough on any of these?
Are they cloned from each other, or setup from scratch?
Afinity host / load balancing?
What happens if you migrate to the other pool?
Last time I saw that error. The resources on the host weren't enough to start the additional VM.
@probain Hello,
It's likely linked to the
List index out of rangebug.
That bug was linked to the SR scan failing to introduceCBT_metatadataVDI in the XAPI database, could you try to launch axe sr-scan uuid=<SR UUID>and try again to disable CBT?
If it does not work, could you share the/var/log/SMlogof around the time you are trying to disable CBT?
I've sent you a DM for sharing the logs.. Unfortunately I "solved" the issue by deleting all snapshots related to each VM. Including CBT ones. That did make it so I could toggle CBT on the VDIs again.
But I've collected the logs for you.
This also seems like a good time to raise my suggestion to have somewhere at vates where we could upload details in a similar way to how TrueNAS does it. Suggested here: https://feedback.vates.tech/posts/69/suggesting-to-add-a-debug-file-option
Now receiving UUID_INVALIDwhen trying to disable CBT on a VDI.
Perhaps a result of fixing the "List index out of range"-bug?
XO Source: 5811d
Node 24
vdi.set
{
  "id": "57e0db3e-3131-40df-a620-c1118047b9d4",
  "cbt": false
}
{
  "code": "UUID_INVALID",
  "params": [
    "VDI",
    "7b179964-dec6-4e24-a13b-8c5c56efcd95"
  ],
  "call": {
    "duration": 2,
    "method": "VDI.get_by_uuid",
    "params": [
      "* session id *",
      "7b179964-dec6-4e24-a13b-8c5c56efcd95"
    ]
  },
  "message": "UUID_INVALID(VDI, 7b179964-dec6-4e24-a13b-8c5c56efcd95)",
  "name": "XapiError",
  "stack": "XapiError: UUID_INVALID(VDI, 7b179964-dec6-4e24-a13b-8c5c56efcd95)
    at XapiError.wrap (file:///opt/xen-orchestra/packages/xen-api/_XapiError.mjs:16:12)
    at file:///opt/xen-orchestra/packages/xen-api/transports/json-rpc.mjs:38:21
    at runNextTicks (node:internal/process/task_queues:65:5)
    at processImmediate (node:internal/timers:472:9)"
}
I will check back tomorrow when I'm back at that lab-pool. Sorry for taking your time thus far. I will provide more and better info tomorrow
So is it a display issue from XO or a problem for the tools? (not sure to get it).
What's the output of
xeCLI?
This is me (jr-m4) from another (private) account.
Update: Details below are incorrect information.
xe Output for another windows 2025 guest, where I'm seeing the same behaviour
[16:25 xcp ~]# xe vm-list uuid=3d3b8ba4-09c1-039d-8d58-ec797e7a05c3 params=networks
networks (MRO)    : 0/ip: 192.168.80.234; 0/ipv4/0: 192.168.80.234; 0/ipv6/0: fe80::4496:9d87:690d:ccc7
