XCP-ng
    • Categories
    • Recent
    • Tags
    • Popular
    • Users
    • Groups
    • Register
    • Login
    1. Home
    2. Popular
    Log in to post
    • All Time
    • Day
    • Week
    • Month
    • All Topics
    • New Topics
    • Watched Topics
    • Unreplied Topics

    • All categories
    • R

      Incremental backup fails on a 3 TB qcow2 disk: value is out of range ... <= 4294967295 in computeVhdBatAndFileSize

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Backup
      5
      1 Votes
      5 Posts
      191 Views
      poddingueP
      Good to hear block mode did it. If I'm reading XO's troubleshooting page right, that 5-minute wait is a setting you can raise: httpInactivityTimeout under [xapiOptions] in a file like /etc/xo-server/config.httpInactivityTimeout.toml, then a restart of xo-server (https://docs.xen-orchestra.com/backups-and-dr/backup_troubleshooting#error-http-connection-has-timed-out). That path is the XOA one, and I don't know where the ronivay installer keeps its config, so check that first. The page calls it a workaround and says the slow host is the real thing to look at, which could fit your SMR-disk theory, but I haven't tried anything close to a 3 TB qcow2 delta myself. For the close() error, unless I'm misreading the code, XO closes the source after the failed start and only logs a warning before falling back to a full, so I'd guess it's noise from the timeout and not a second bug. The stuck tapdisks look more like one for @Team-Storage, and I don't know if a keep-alive during the delta computation is planned.
    • I

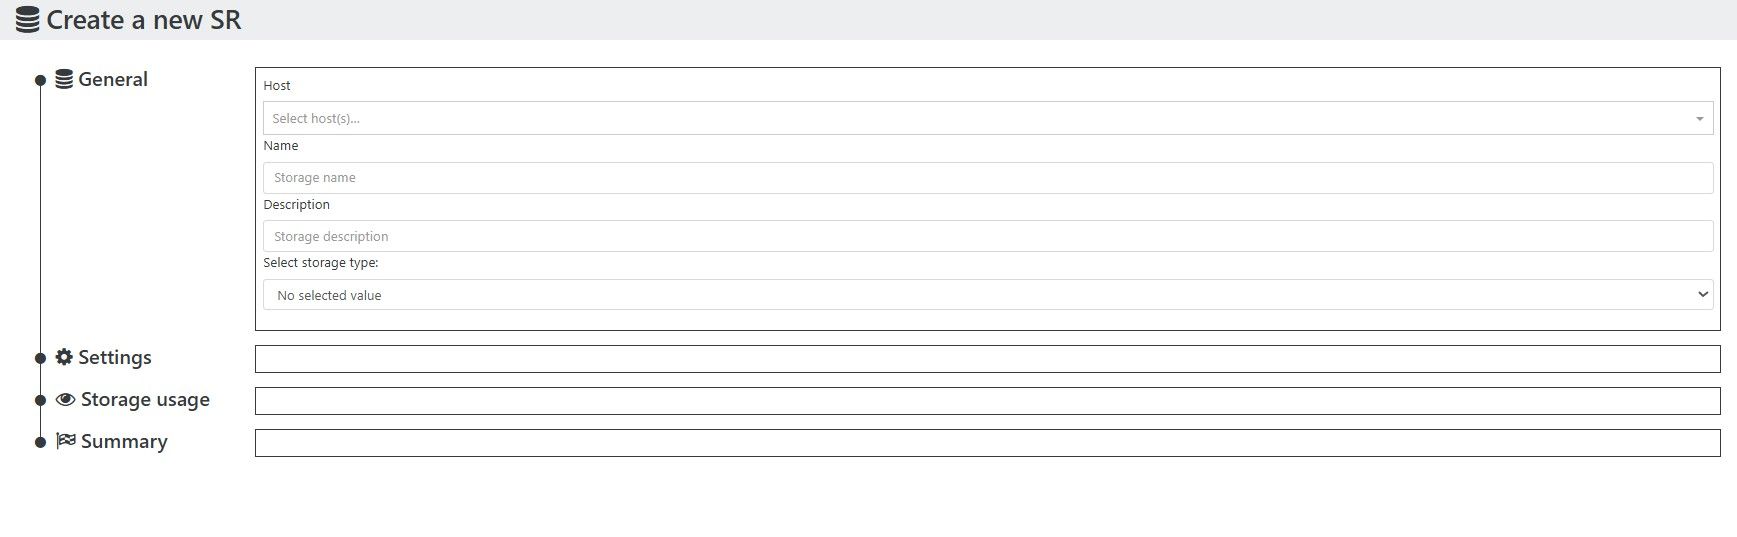
      Slow SR Creation

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Management
      7
      1
      0 Votes
      7 Posts
      657 Views
      I
      @Goulven I have shared the logs with you over the drive.
    • W

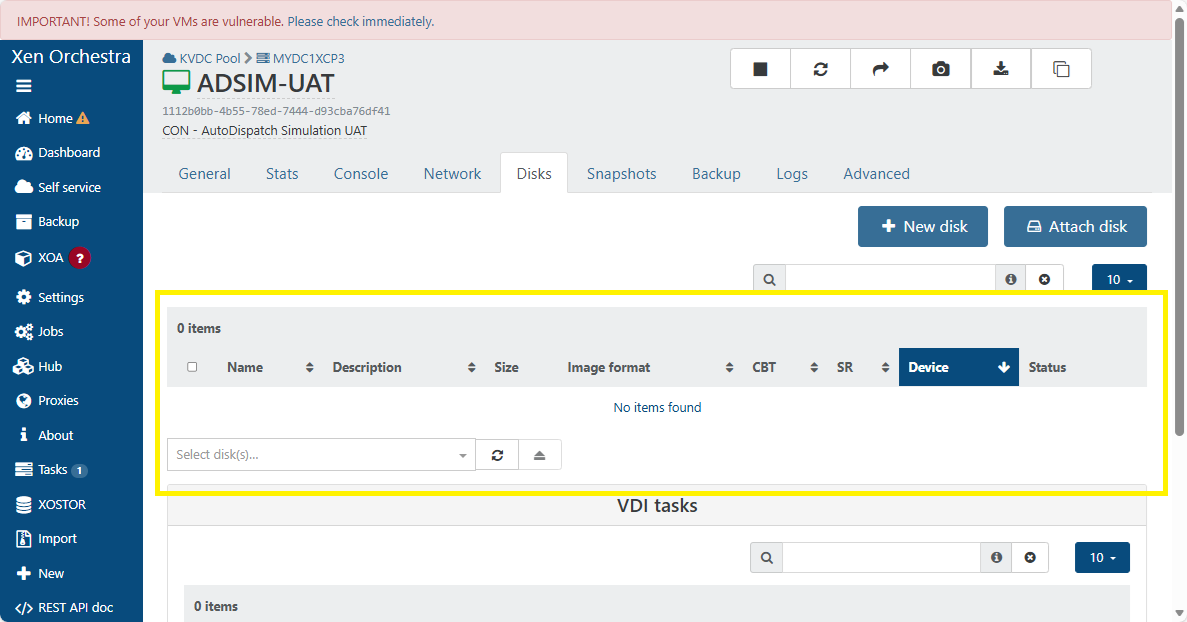
      VDI not showing in XO 5 from Source.

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Management
      58
      2
      0 Votes
      58 Posts
      21k Views
      L
      It's a been a while since this thread has been updated, so I figure I should share what I've learned. First: here's a script which reproduces the bug reliably and includes steps to revert: https://gist.github.com/dmeiselman/ecb35ffcb675c38e6eeb14292948c2e3 Don't run this on your production cluster. Here's my understanding of this bug and it's current state: Some operation sets the snapshot_of metadata field of a valid snapshot to NULL (We can do this intentionally by making a VM, taking a snapshot of it, then deleting the parent disk.) If you perform a revert of this invalid snapshot, revert's "Updating the snapshot_of fields" step looks for VDIs whose snapshot_of matches the snapshot's source disk, so it can relink them to the new disk. If the source is NULL, the search becomes "every VDI with NULL", which matches ISOs, base images, ordinary VM disks. Congrats, every real disk and ISO in every SR now looks like a snapshot. Now these disks have a value set for snapshot_of which means XOA hides the VDI in the web UI. The fix is to delete or clone the super-parent, and all of its snapshots. sr_scan will correct the metadata for all the VMs and ISOs and you're back where you started. This happens in line 401 of https://github.com/xapi-project/xen-api/blob/v26.1.19/ocaml/xapi/xapi_vm_snapshot.ml#L389-L408 PR 7290 https://github.com/xapi-project/xen-api/pull/7290 has a fix, which looks like it's coming in xapi v26.1.21. (It's worth reading the Pull Request, as it has a more graceful description of the issue, it really helped me wrap my head around it.)