• Veeam for Xen Orchestra has been release today 13.1

    25
    0 Votes
    25 Posts
    3k Views
    acebmxerA
    So I ended up going with the Windows B&R as i could net setup the windows mount server when setting up the repo for the backups. It would setup the linux one but not the windows one. This was with using the veeam console from a windows client. So i ended up with the Windows one. Now after a few backups i am see this warning / error.... 8/5/2026 5:34:50 PM Warning : Failed to use CBT: [Task e75c4247-2ee1-7b51-088c-b970ace60f3d (Async.VDI.list_changed_blocks) failed: . SR_BACKEND_FAILURE_460. . Failed to calculate changed blocks for given VDIs. [opterr=Source and target VDI are unrelated] First i thought it was because i maped the new job to older backups from Beta v1. So i purged all old backups and started fresh. The full backups were successful. Now on first delta 4 out of 7 vms have that warrning. This a Veeam issue or xcp-ng?
  • Pool metadata Restore RESTORE_INCOMPATIBLE_VERSION

    Moved Unsolved
    5
    0 Votes
    5 Posts
    361 Views
    F
    This might have worked, at that time i've allready created new VMs from the information inside the Backup xml file. It worked out allright but building VMs this way, is quite tidious. Maybe there could be a way to find the correct installer and patches, to get a new host in a state to restore a pool backup, would be good.
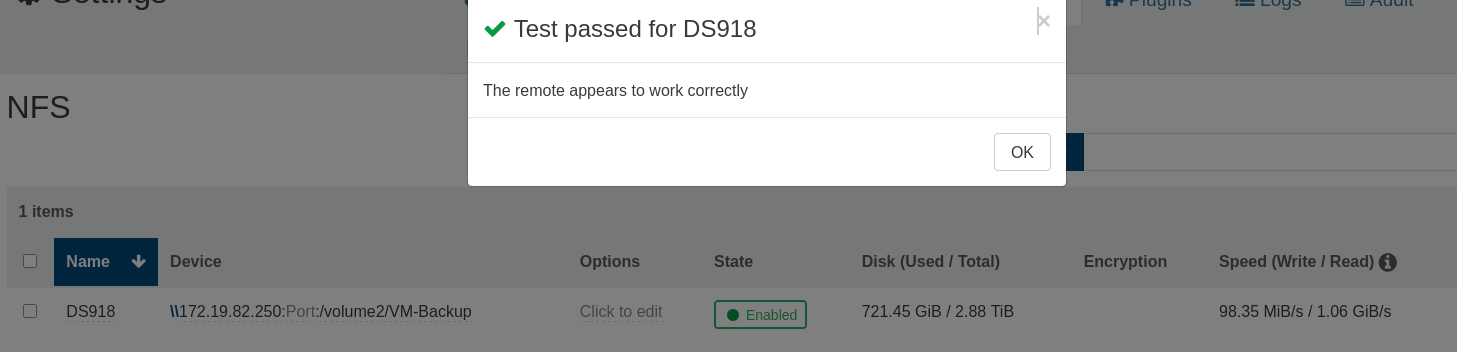
  • Recommandations about NFS Remotes maintenance ?

    Solved
    6
    0 Votes
    6 Posts
    324 Views
    olivierlambertO
    A remote is not the same thing as a SR. For a remote, it's simple: disconnect it (click on "Enabled" so it's disabled then), do whatever you need on the NFS server, re-enable.
  • UI Bug when falling back to Full Backup

    Unsolved
    5
    1
    0 Votes
    5 Posts
    862 Views
    poddingueP
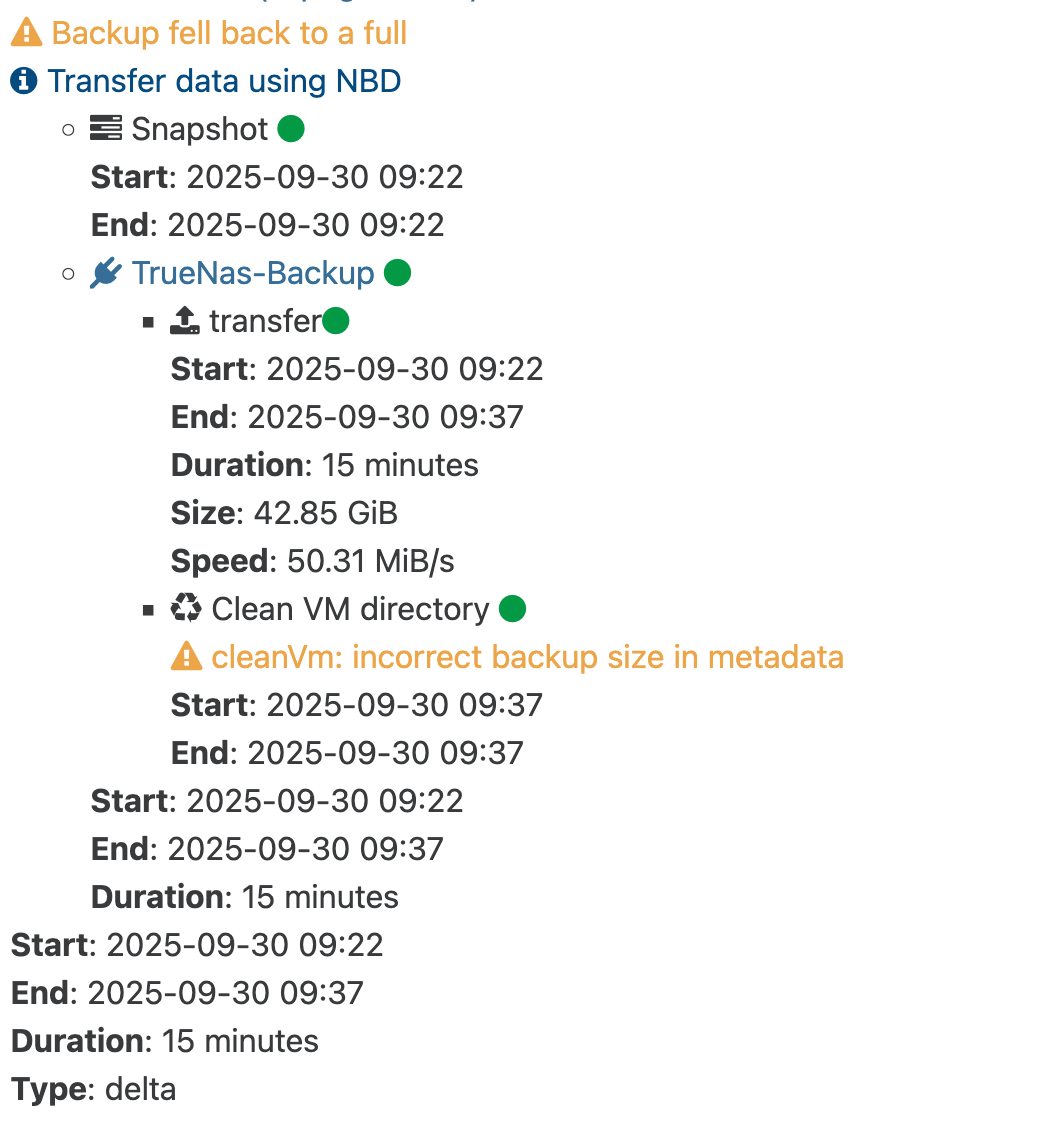
    I think this is fixed in 6.7: when a delta backup falls back to a full, the task now shows the actual reason instead of just contradicting itself the way you and Andrew both saw (PR #10148). Worth checking after you upgrade.
  • VM backup retry - status failed despite it was done on second attempt

    Unsolved
    11
    2
    0 Votes
    11 Posts
    2k Views
    poddingueP
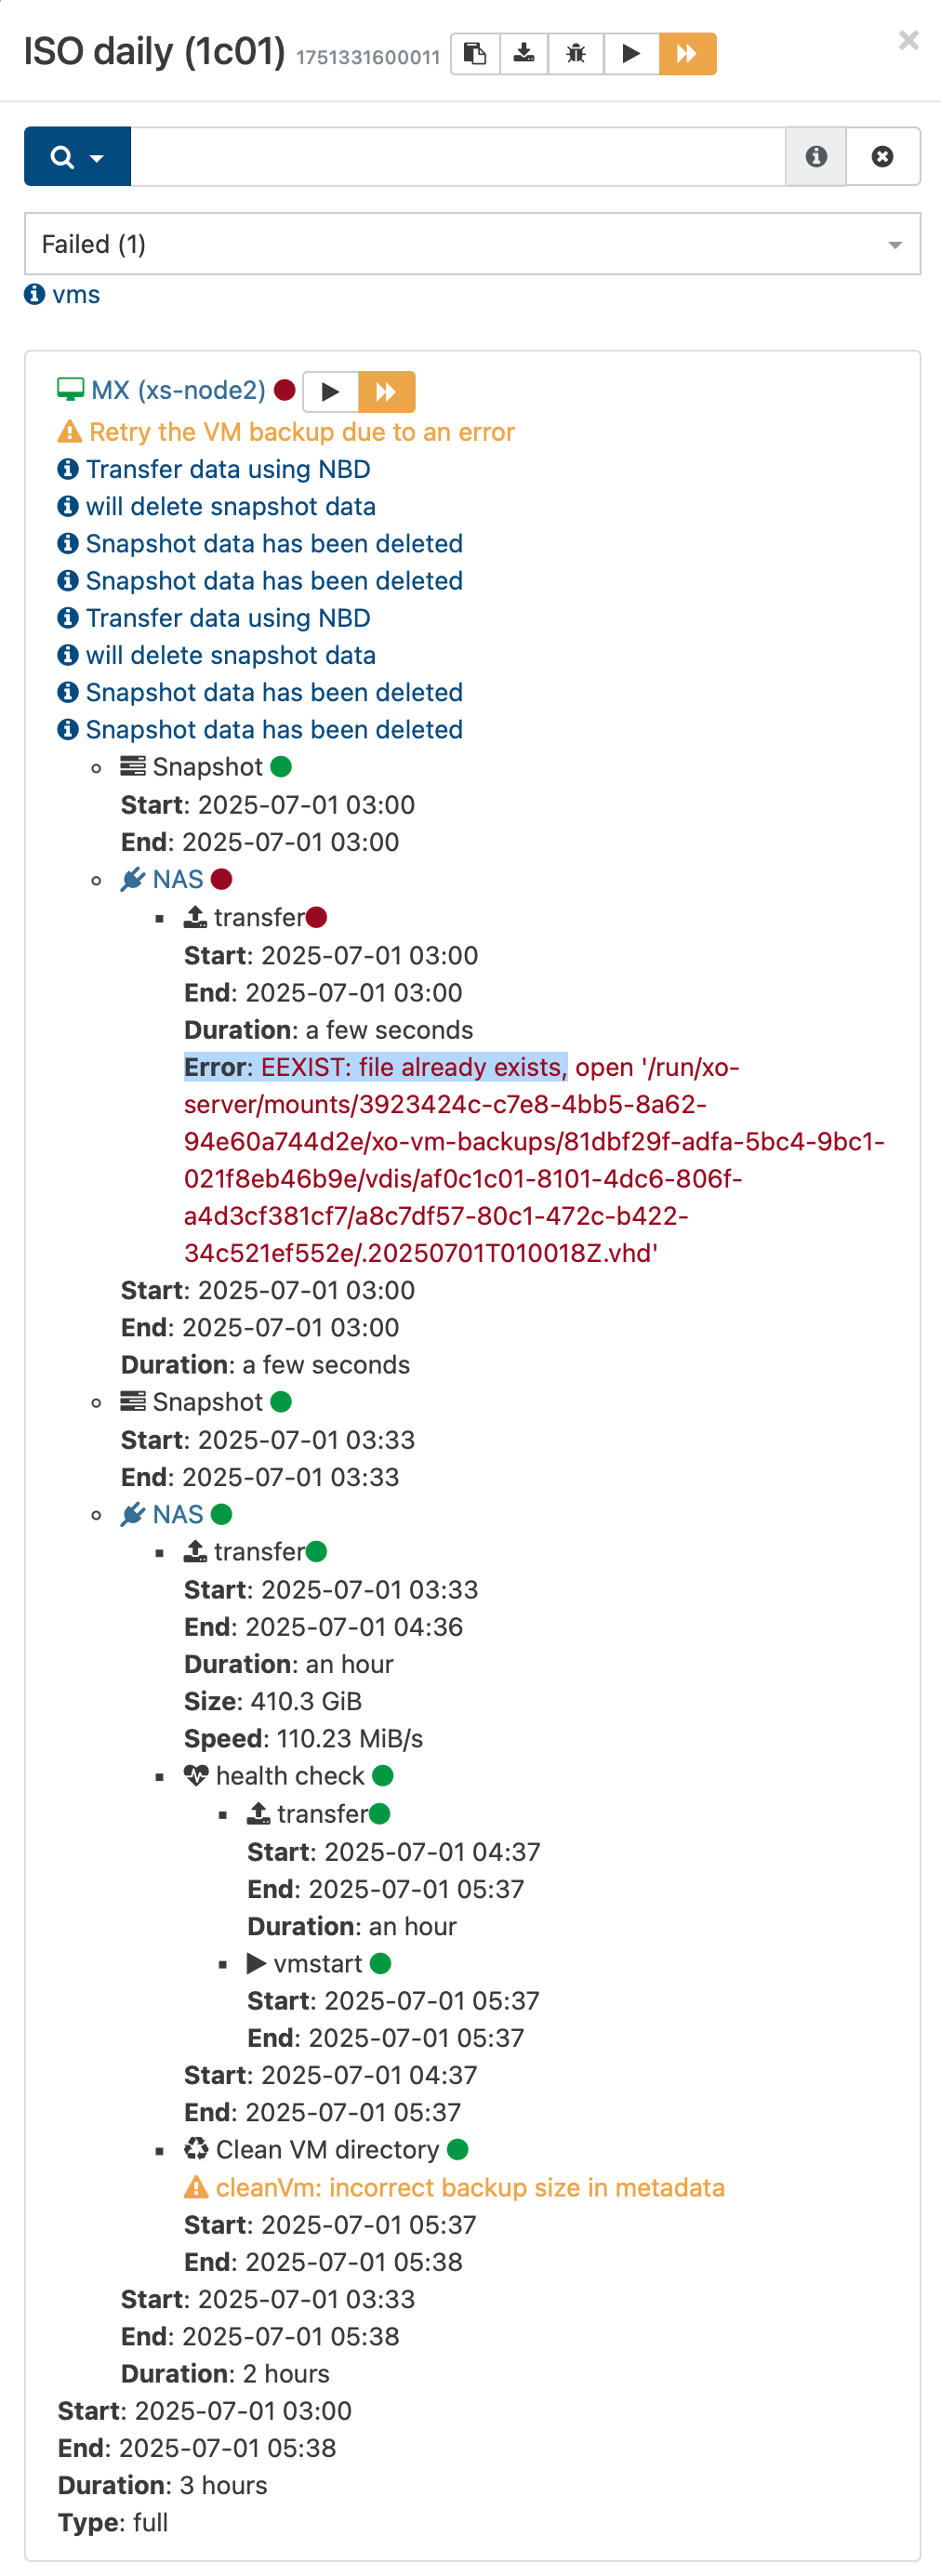
    Both things reported here look fixed in 6.7: the retry succeeding but the job still showing as failed (PR #10129), and the EEXIST: file already exists error, which happened when a job got recreated after a crash (PR #10139). Curious if upgrading clears it for you all too.
  • Backups with qcow2 enabled

    29
    3
    0 Votes
    29 Posts
    5k Views
    poddingueP
    The progress bar issue you and Florent were chasing looks fixed in 6.7 (PR #10133). Worth upgrading and seeing if it moves now instead of sitting still. Separately, since this thread is specifically about QCOW2 backups: 6.7 also fixes an offset bug that could leave incremental backups mostly empty after the first block when NBD isn't enabled. Worth a look at the release notes if that's your setup too.
  • CR - Cannot start copy because suspended

    Unsolved
    17
    0 Votes
    17 Posts
    1k Views
    poddingueP
    Good news that it sorted itself out. Both changes went in at once and the next run came back clean on the ADDS VMs too, so I don't think there's anything left to pin down here, and I'd rather say that than invent an explanation after the fact. Your question about the snapshot modes was the useful thing to come out of this thread. I went looking, they genuinely aren't documented anywhere, and that's written up on our side now If the fall back to a full ever comes back on the ADDS VMs specifically, that would deserve its own thread with the SMlog output @tjkreidl asked for, since nobody got to look at that part.
  • This topic is deleted!

    1
    0 Votes
    1 Posts
    12 Views
    No one has replied
  • Delta backup stuck on "Clean VM Directory" for a long time

    9
    0 Votes
    9 Posts
    2k Views
    olivierlambertO
    Thanks for the feedback @norpan , worth it! Ping @florent
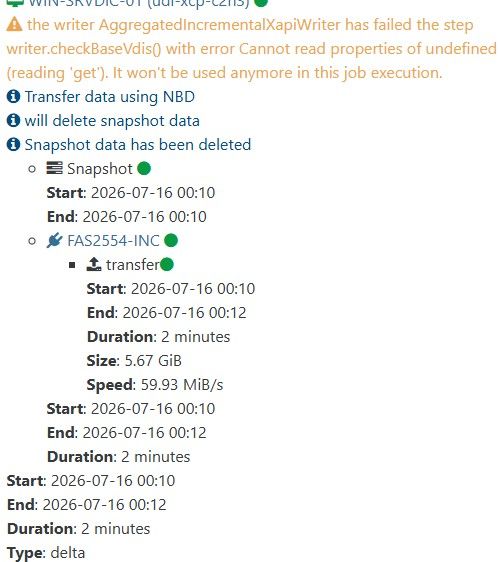
  • Continuos replication failing with "checkBaseVdis() failed"

    11
    2
    0 Votes
    11 Posts
    1k Views
    Tristis OrisT
    Got this issue since 2026-07-12.
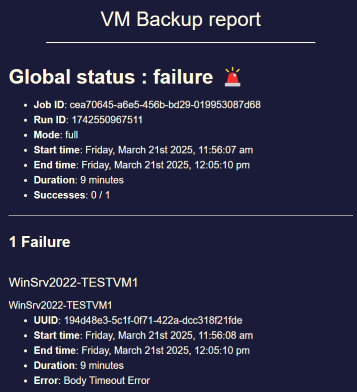
  • Potential bug with Windows VM backup: "Body Timeout Error"

    103
    3
    2 Votes
    103 Posts
    30k Views
    P
    @pierrebrunet said: Hi, just to be sure, are you saying it is working ok apart one task 8 days ago? Yes, after I adjusted the time it's working
  • XO Backup Error: VDI_IN_USE(OpaqueRef:.., destroy)

    27
    2
    0 Votes
    27 Posts
    5k Views
    itservicesI
    @simonp , thank you very much and all of your team ! ! ! Keep up the outstanding work. Regards, Marc
  • Backups failing back to Full Backups

    9
    0 Votes
    9 Posts
    739 Views
    olivierlambertO
    Indeed, it should be detected/reported correctly to avoid losing time finding the problem. Let me ping @julienXOVates
  • XO 6 > VM > Backups are not ordered

    2
    2
    0 Votes
    2 Posts
    359 Views
    olivierlambertO
    Ping @julienXOVates
  • Fail backup has a progression

    2
    1
    0 Votes
    2 Posts
    350 Views
    olivierlambertO
    Ping @julienXOVates
  • Host crash during backup

    Solved
    14
    0 Votes
    14 Posts
    3k Views
    BrantleyHobbsB
    @Pilow pretty much
  • unacceptable message conflict

    8
    3
    0 Votes
    8 Posts
    1k Views
    S
    @pierrebrunet ticket created https://help.vates.tech/#ticket/zoom/59723
  • Replication is leaving VDIs attached to Control Domain, again

    11
    0 Votes
    11 Posts
    2k Views
    A
    @poddingue Since setting NBD=1, I have not seen the problem. SR is NFS on dual 40G ethernet with a TrueNAS scale 25.10 server using all NVMe SSD, so storage performance is as good as I can make it. I'll have to enable NBD=2 again to see if it still happens and if I can find the relevant part of the logs. As this is a random problem I can't recreate it on a normal test environment.
  • VHD Check Error

    13
    1
    0 Votes
    13 Posts
    1k Views
    poddingueP
    Pilow's right that moving a VM to another SR forces one full pass while the CBT bitmap is rebuilt; that part is expected. But your screenshot actually shows the likely culprit for the all-VMs-fall-back-to-full pattern: you have Purge snapshot data when using CBT enabled, and XO's incremental backup docs flag exactly that combination as a known issue where you can occasionally get unexpected fulls: https://docs.xen-orchestra.com/xo5/incremental_backups#known-issues. It might be worth running a few jobs with that toggle off to see if the deltas hold. It is a known rough edge on the CBT side, so following the central CBT feedback thread and maybe a nudge to @Team-XO-Backend wouldn't hurt.
  • Too many snapshots

    49
    2
    0 Votes
    49 Posts
    10k Views
    julienXOvatesJ
    @henri9813 said: Hello, I see also this behavior which is "new" since few weeks. Previously, when a backup start: it stake a snapshot ( if there another one before, it delete it ). it upload the snapshot as a backup it coalesce the backup on the remote. end of the game. Now, the old snapshots are not deleted anymore which can lead easily to some disk full. Even with a retention of 1, the problem is present. I observe this only in Backup job, not DR/CR job. I just updated my XO to latest version, i will see if the issue is fixed. Hi @henri9813 , Issue should be resolved in 6.5.x, can you confirm on your side ? Thanks!