XCP-ng
    • Categories
    • Recent
    • Tags
    • Popular
    • Users
    • Groups
    • Register
    • Login
    1. Home
    2. Popular
    Log in to post
    • All Time
    • Day
    • Week
    • Month
    • All Topics
    • New Topics
    • Watched Topics
    • Unreplied Topics

    • All categories
    • J

      Using BunkerWeb and SysWarden with Xen Orchestra and/or XO Proxy

      Watching Ignoring Scheduled Pinned Locked Moved Xen Orchestra xen-orchestra xen orchestra web application firewall waf
      1
      0 Votes
      1 Posts
      148 Views
      No one has replied
    • msupportM

      Veeam 13.1 Rocky9 Linux Appliance: Potential Data Loss with CBT and Workers with Expired Tokens

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Backup
      17
      2 Votes
      17 Posts
      2k Views
      acebmxerA
      Just recieved another update from veeam... Regarding the general earlier errors: Warning : Failed to use CBT: [Task e75c4247-2ee1-7b51-088c-b970ace60f3d (Async.VDI.list_changed_blocks) failed: . SR_BACKEND_FAILURE_460. . Failed to calculate changed blocks for given VDIs. [opterr=Source and target VDI are unrelated] Our QA team did hear back from Vates support, who says its tied to a recent bug they've found with blktap calls: https://github.com/xapi-project/blktap/pull/444 Our QA engineer hasn't heard back yet on ETA when it will be pushed out in a general release yet though
    • M

      Can't init vhd directory without using alias

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Backup
      2
      0 Votes
      2 Posts
      186 Views
      poddingueP
      You already spotted this over on 12468, so this is just to close the loop here. That one's fixed: Pierre Brunet put the fix on a branch, @Andrew and @abudef both tested it, and it's merged now. Since you're running from source on master, you should be able to pull past that merge rather than wait for a release. One thing to keep in mind, though: the same error string showed up in 11875 for a completely different cause, so if it comes back after you update, it's probably not this bug again. I'd let 12468 be the thread to follow since that's where the people who fixed it are.
    • J

      VDI migration SR selection broken?

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Xen Orchestra
      4
      0 Votes
      4 Posts
      483 Views
      M
      @jacob.becker Hi Jacob, I made a fix and it should be available on the next release
    • M

      New cisco-enic driver available for testing

      Watching Ignoring Scheduled Pinned Locked Moved Hardware
      1
      2 Votes
      1 Posts
      133 Views
      No one has replied
    • J

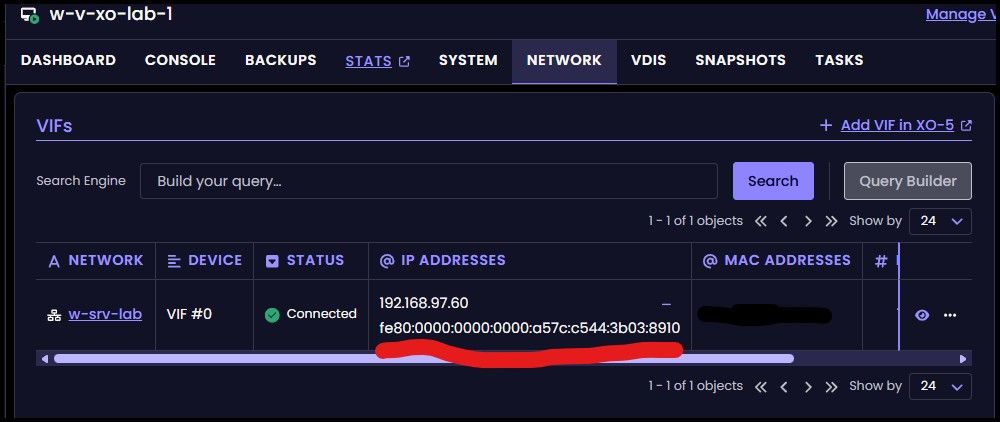
      (Windows) guest IPv6 address doesn't collapse zeroes -> Long IPv6 addresses

      Watching Ignoring Scheduled Pinned Locked Moved Solved Xen Orchestra
      21
      1
      0 Votes
      21 Posts
      3k Views
      J
      I just did a quick test to check. And it does indeed seem that this (small) issue has now been resolved. Tested on Windows Server 25, Management agent 9.2.385-0. Cheers!
    • A

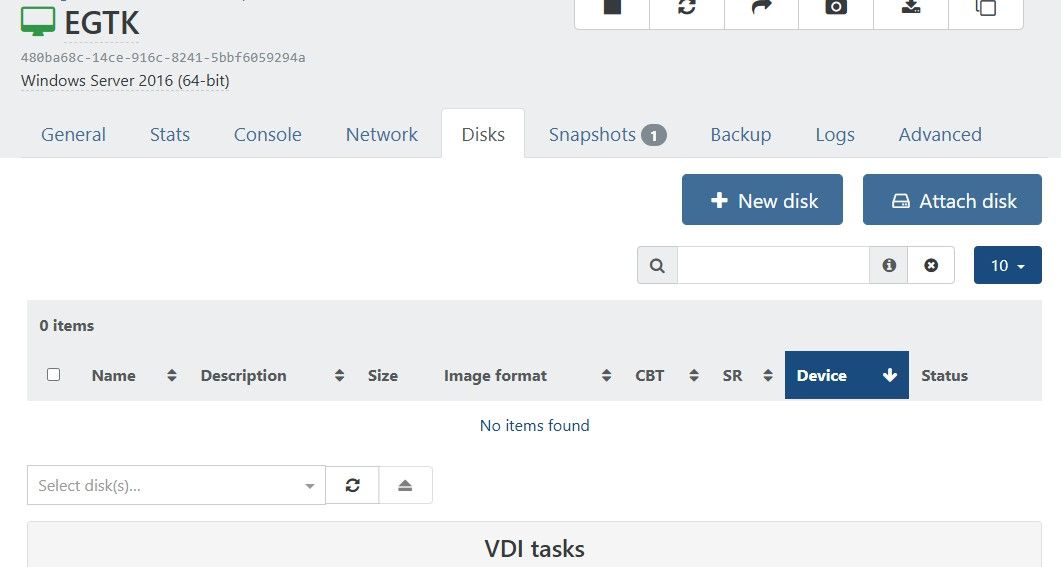
      XenOrchestra not showing VM Disks on Pool (on single Server working) - XCP-ng Center is showing them

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Xen Orchestra
      29
      2
      0 Votes
      29 Posts
      6k Views
      A
      Apologies for the long silence on my end — real life got in the way and I couldn't dig into this for a while. Finally found the time now to go through it again properly, helped a lot by the details others have already posted here in the meantime. I don't think this adds a new root cause, but it does corroborate what @kagbasi-wgsdac described — same "mass collapse onto a single anchor UUID" pattern, and in my case too that anchor is a real, still-in-use base disk, not a dangling/non-existent OpaqueRef (referencing vatesfr/xen-orchestra#9578). Environment: 2-host pool, shared NFS SR, XO recently updated to the latest version (didn't change anything regarding this issue, as expected since it's XAPI-side). Ran a read-only xe vdi-list params=uuid,name-label,is-a-snapshot,snapshot-of,snapshot-time directly against the pool master. Result: 47 of 196 VDIs match the pattern (is-a-snapshot: false but snapshot-of populated). All 47 point to the exact same single anchor UUID — which resolves to one specific, actively-used base VDI, not a missing reference. snapshot-time on most affected VDIs is the epoch default (1970-01-01T00:00:00Z), but a handful show plausible real dates (e.g. late 2025 / early 2026) — suggesting those entries originally had a legitimate snapshot-of relationship that got overwritten by whatever corrupted the metadata. Currently-running VMs affected (100% of each VM's disks affected in every case): VM OS Disks Sizes VM-1 Windows Server 2016 1 50 GB VM-2 Windows Server 2016 3 50 / 200 / 450 GB VM-3 Windows Server 2019 3 100 / 100 / 100 GB VM-4 Windows 11 Pro 2 50 / 100 GB VM-5 (decommissioned) Windows Server 2016 2 100 / 50 GB VM-6 Ubuntu 24.04 2 10 / 10 GB VM-7 Ubuntu 24.04 2 10 / 10 GB VM-8 Windows Server 2025 3 25 / 25 / 64 GB VM-9 Ubuntu 24.04 2 10 / 10 GB On top of that, ~28 more affected VDIs are orphaned/unattached objects ("base copy" leftovers, old ISO references) — same pattern, no VBD attached. Not touching any of this (no snapshot-fixer.py, no manual vdi-param-set) given the risk of severing legitimate snapshot relationships that's already been flagged here. Happy to provide a full anonymized xe vdi-list dump if that's useful for tracking down the root cause. Big thanks to everyone who kept digging into this and shared their findings here — especially @kagbasi-wgsdac for the detailed write-up that pointed me in the right direction, and of course @poddingue and the whole Vates team for staying on top of this and keeping us updated despite no clear timeline yet. Really appreciate the effort that goes into this, especially for something as tricky as a metadata corruption bug across production pools. Kind Regards and thx again Alex
    • L

      sr iso disconnect and crashed my hosts

      Watching Ignoring Scheduled Pinned Locked Moved XCP-ng
      12
      0 Votes
      12 Posts
      3k Views
      H
      @olivierlambert We are still seeing similar issues on fully updated xcp-ng 8.3 host. We do reboot every time it happens. Is there anything we can do to fix this otherwise or prevent this from happening (beside manually disconnecting the cifs iso storage before the san goes for a reboot)?