XCP-ng
    • Categories
    • Recent
    • Tags
    • Popular
    • Users
    • Groups
    • Register
    • Login
    1. Home
    2. Popular
    Log in to post
    • All Time
    • Day
    • Week
    • Month
    • All Topics
    • New Topics
    • Watched Topics
    • Unreplied Topics

    • All categories
    • stormiS

      XCP-ng 8.3 updates announcements and testing

      Watching Ignoring Scheduled Pinned Locked Moved News
      802
      1 Votes
      802 Posts
      1m Views
      R
      Thank you, @stormi , I'm happy to know that xcp-ng.repo is not touched. These three hosts haven't been rebuilt or restored recently, no hosts have been added, and I did have to make the above modification on each one of them to get them to work. I suppose it's possible I missed the step to remove "mirrors.xcp-ng.org" from xcp-ng.repo during the initial pool build about a year ago and it's just somehow been working with our outbound Internet proxy. In any event, having "mirrors.xcp-ng.org" in our xcp-ng.repo file has definitely caused us problems in the past with our proxy setup. TGIF/DMCV!
    • olivierlambertO

      šŸ›°ļø XO 6: dedicated thread for all your feedback!

      Watching Ignoring Scheduled Pinned Locked Moved Xen Orchestra
      327
      7 Votes
      327 Posts
      226k Views
      poddingueP
      @coolsport00 not in XO 6 yet as far as I can tell. For now it's still done from XO 5: Home > Pools, open the pool, then "Add Hosts" at the top right, once the new host has been added as a server (docs). I believe the XO team already has it on their list for the pool dashboard. If you want to push it, there's a close Feeder request you could vote on, which also asks for a proper add-host form: https://feedback.vates.tech/posts/75/permit-to-add-host-to-pool-with-a-real-form @Greg_E thanks for the screenshot. It looks like the parent task keeps reporting 1% once the metadata backups underneath it are done. I think that one is known too, but I'll let the XO team confirm.
    • B

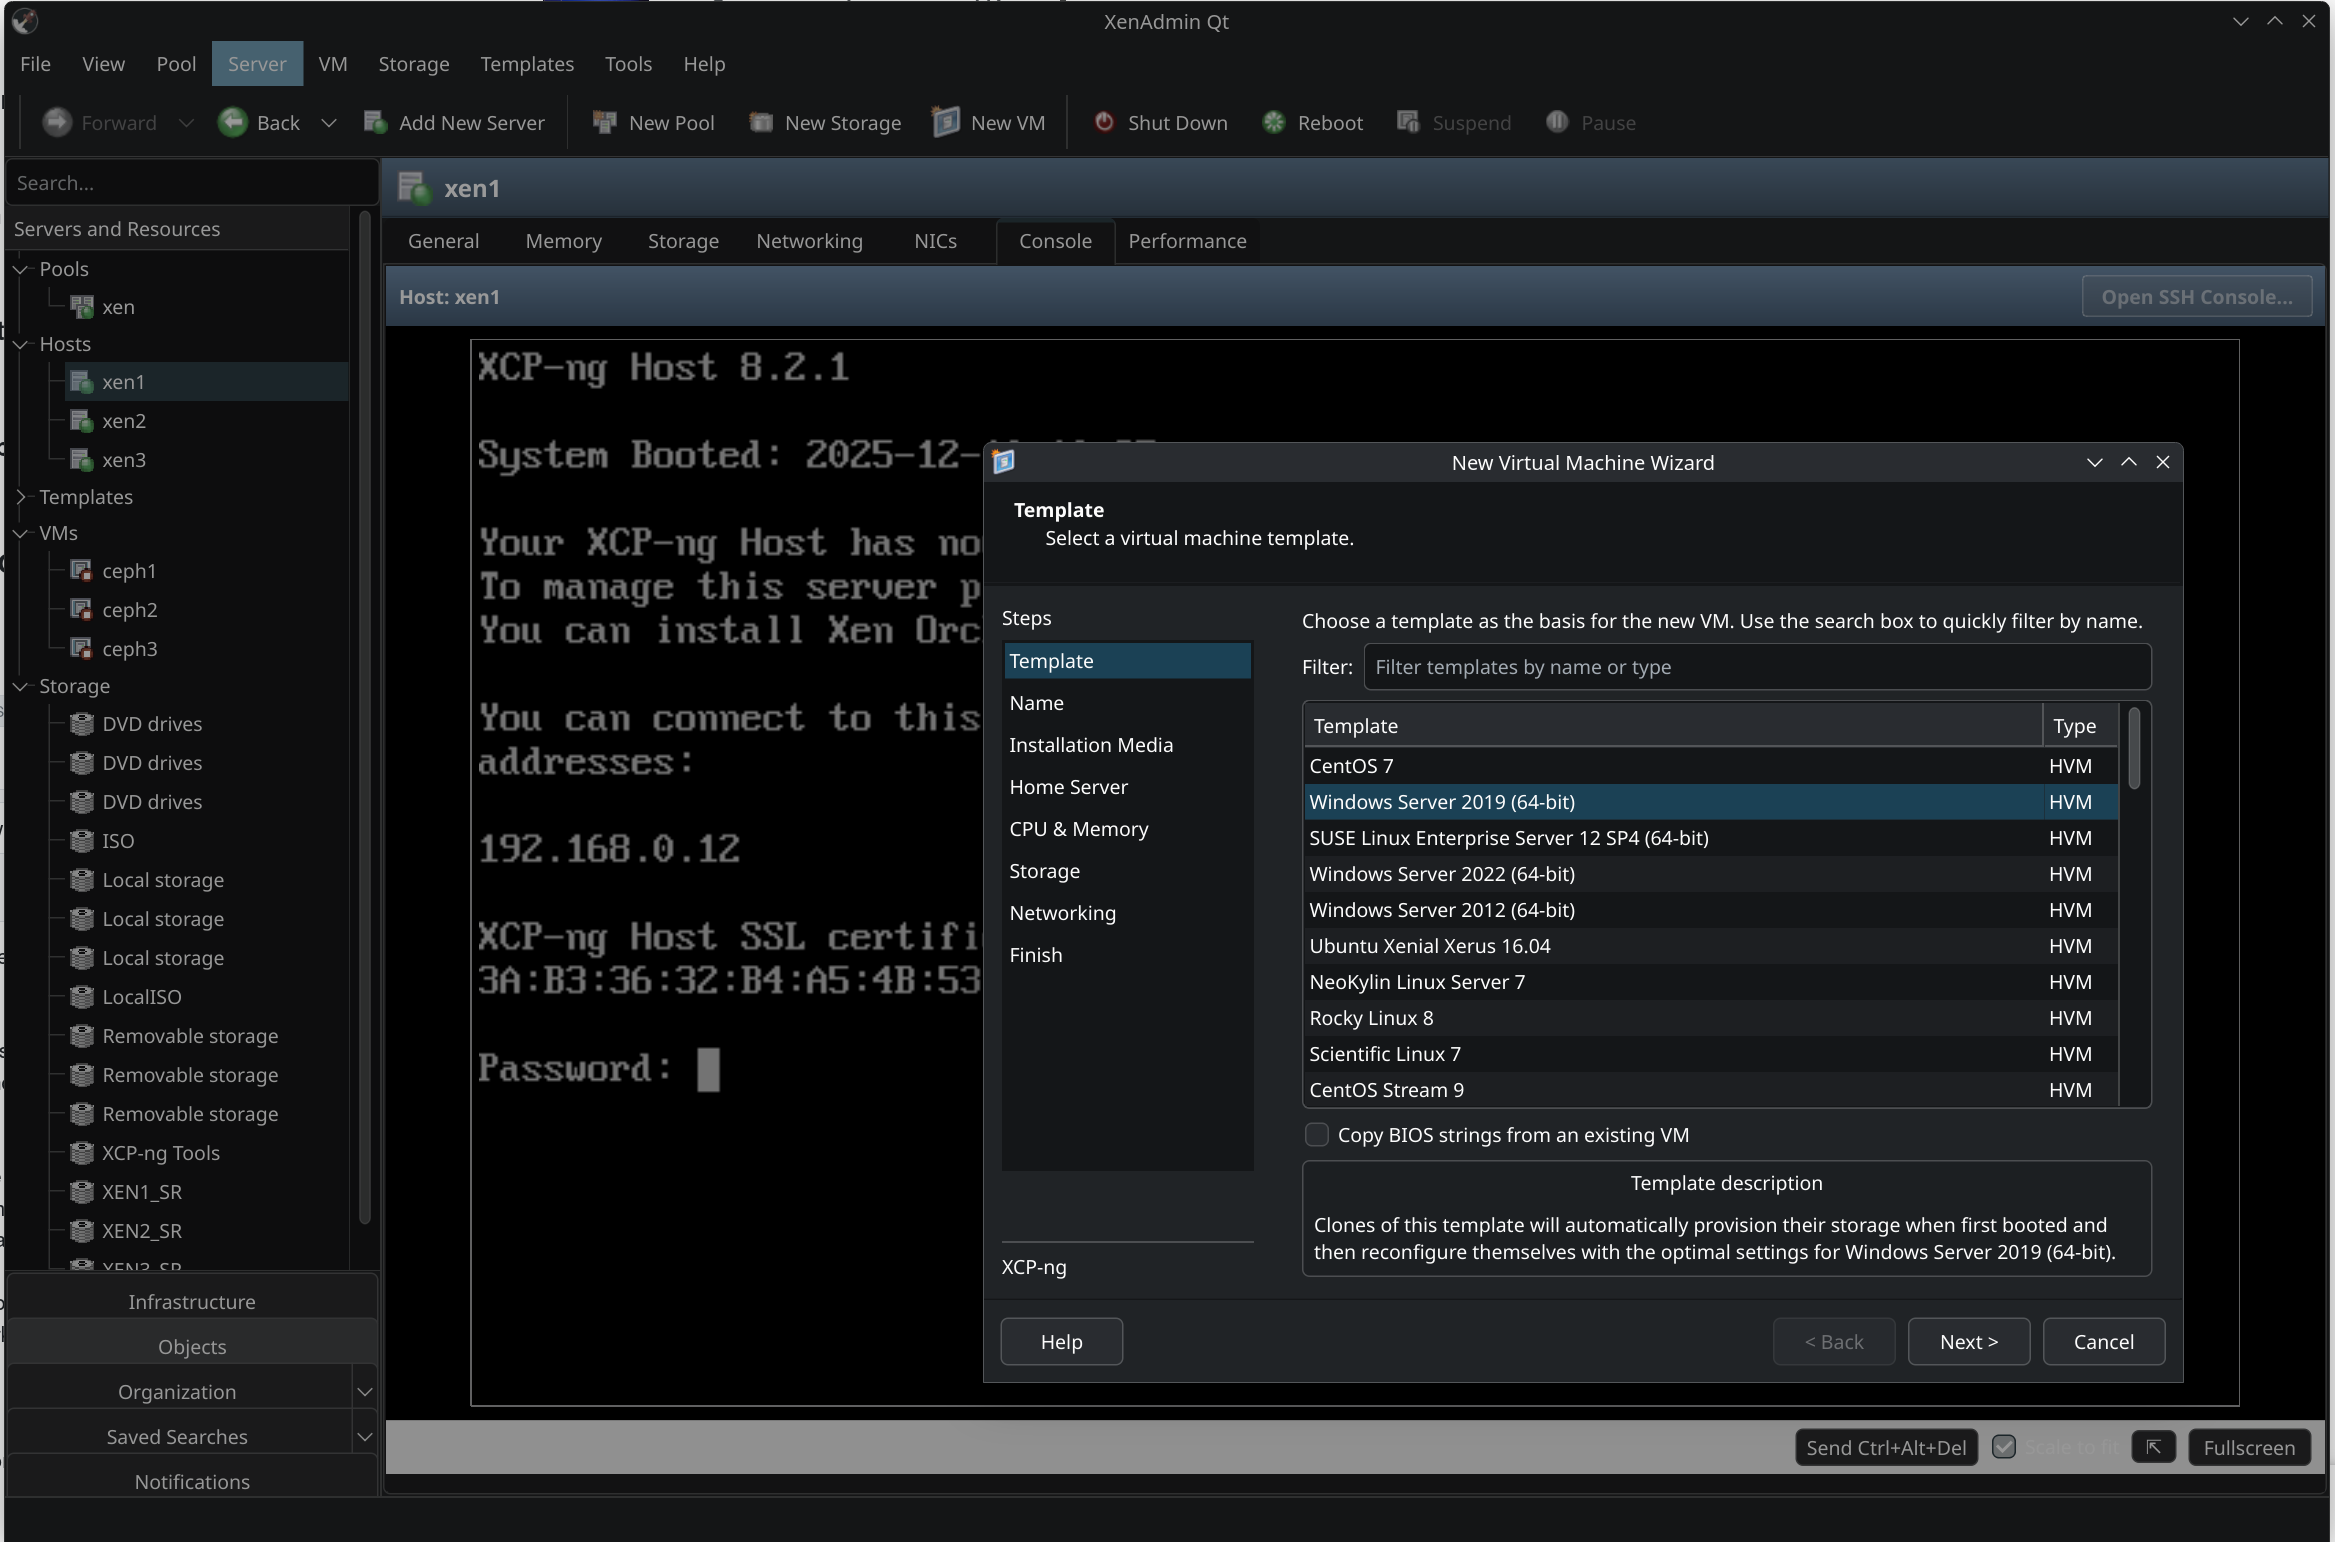
      New project - XenAdminQt - a cross-platform GNU/Linux, macOS, Windows native thick client

      Watching Ignoring Scheduled Pinned Locked Moved News
      59
      1
      9 Votes
      59 Posts
      18k Views
      B
      that horizontal scroll bar was also enabled
    • F

      Xen Orchestra web UI becomes unresponsive when an NFS backup remote goes offline

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Xen Orchestra
      18
      0 Votes
      18 Posts
      795 Views
      acebmxerA
      @poddingue added my info as well.
    • O

      Rolling pool update

      Watching Ignoring Scheduled Pinned Locked Moved Xen Orchestra
      13
      0 Votes
      13 Posts
      639 Views
      J
      @tjkreidl said: @john.c Note that a two-host pool running HA can run into the split-brain issue if one of the hosts fails; it's highly recommended to have at least three hosts in an HA pool (or look into HA-Lizard if running a pool with two hosts and HA). Right but also considering the in development Twinstor for when it goes stable and in production!
    • G

      random backups failing

      Watching Ignoring Scheduled Pinned Locked Moved Solved Backup
      13
      0 Votes
      13 Posts
      704 Views
      G
      OK, marking this solved... It was the phantom reboots causing issues because the tools were not fully installed, only thing I can't understand is why only 2 out of 3 Windows servers would quit. Any way, got the Xen Tools updated and a couple reboots later, everything is working again. Also I can now report that a bug that was fixed maybe a year ago is confirmed to work in my system. The bug was backing up a Windows VM that had a lot of empty space in the drive (over 250GB free) and turning on compression. It would time out counting zeros because it thought the process wasn't doing work. Both of these VMs are now compressing with zstd, one of them is substantially smaller now, the other only shrunk about 20GB. Because of the way Windows uses the drive, these are all full backups. The differential never seemed to be small because Windows does a lot of changes on the drive (there is a post about this somewhere in here from Olivier).
    • B

      Native Ceph RBD SM driver for XCP-ng

      Watching Ignoring Scheduled Pinned Locked Moved Development
      43
      3 Votes
      43 Posts
      12k Views
      A
      @dicode-nl Thank you for the code. I'm in testing now with ceph 20.2.5 and so far I haven't had any issues.
    • B

      Missing vdi which is a base for a delta

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Backup
      11
      0 Votes
      11 Posts
      793 Views
      poddingueP
      Thanks, that helps. Some VMs fail to the Synology but pass to S3, and some the other way round. So I think the backups on Ark are probably fine (they pass health checks, as you said at the start) and it has more to do with what each target already holds, but I could be wrong. I'd also flag the several delta jobs with different retentions all feeding Ark, I just don't know the mirror code well enough to say whether that matters. @Team-XO-Backend, posts 6 and 10 have the log and the pattern if someone gets to this one.
    • P

      Full backup failure when upgrading XOce

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Backup
      10
      0 Votes
      10 Posts
      154 Views
      P
      @florent { "data": { "mode": "full", "reportWhen": "failure" }, "id": "1794881400002", "jobId": "0ffa03e5-e750-43ad-b66c-0495405fe068", "jobName": "BCK_Running", "message": "backup", "scheduleId": "0c8bba34-e5f1-4f58-9c38-11b514358383", "start": 1794881400002, "status": "interrupted", "tasks": [ { "id": "0mwk21luf-5zyntw173ie", "start": 1794881402583, "status": "success", "tasks": [ { "id": "0mwk21mr0-y3gazw087kf", "start": 1794881403757, "status": "success", "end": 1794881405281, "result": "459e3a05-f508-e85d-5cc4-387155dc304b", "message": "snapshot" }, { "id": "0mwk21nyt-imr121bpgle", "start": 1794881405333, "status": "success", "tasks": [ { "id": "0mwk21nzt-bqf4lzdvlkt", "start": 1794881405369, "status": "success", "end": 1794881441678, "result": { "size": 3268086272 }, "message": "transfer", "data": { "progress": 0 } } ], "end": 1794881441822, "message": "export", "data": { "id": "0927f4dc-4476-4ac3-959a-bc37e85956df", "type": "remote", "isFull": true } }, { "id": "0mwk22gs1-zazmiofst3r", "start": 1794881442673, "status": "success", "tasks": [ { "id": "0mwk22h6r-uo87g3emm6", "start": 1794881443203, "status": "success", "end": 1794881499852, "result": { "size": 3268086272, "id": "8d6704b6-e005-f300-47e7-be2e9ea21a5c", "liveMounts": [] }, "message": "transfer", "data": { "progress": 100 } }, { "id": "0mwk23owd-9ik1ccu4ln", "start": 1794881499853, "status": "success", "end": 1794881504936, "message": "vmstart" } ], "end": 1794881507491, "message": "health check", "data": { "progress": 0 } }, { "id": "0mwk23ut6-ah9rc68q15o", "start": 1794881507514, "status": "success", "end": 1794881507850, "result": { "removedFiles": [], "changedFiles": [], "merge": false, "size": 0 }, "message": "clean-vm" } ], "end": 1794881507852, "message": "backup VM", "data": { "id": "a6cc5035-c18c-8f35-e197-b7e55c9cab8a", "type": "VM", "name_label": "1-pihole", "progress": 0 } }, { "id": "0mwk23v2t-gatlyfjkc7l", "start": 1794881507861, "status": "pending", "tasks": [ { "id": "0mwk23v9q-d160t2rhy9k", "start": 1794881508110, "status": "success", "end": 1794881510136, "result": "e3625624-81ba-5913-4e69-cca7f5bb5016", "message": "snapshot" }, { "id": "0mwk23wx8-x8bm3je4ztt", "start": 1794881510252, "status": "success", "tasks": [ { "id": "0mwk23wyy-cfs4vlwf58q", "start": 1794881510315, "status": "success", "end": 1794881836648, "result": { "size": 31518195712 }, "message": "transfer", "data": { "progress": 0 } } ], "end": 1794881836755, "message": "export", "data": { "id": "0927f4dc-4476-4ac3-959a-bc37e85956df", "type": "remote", "isFull": true } }, { "id": "0mwk2axif-lzd7nijq25i", "start": 1794881837607, "status": "pending", "tasks": [ { "id": "0mwk2ayix-bhm2oqxo1zc", "start": 1794881838922, "status": "pending", "message": "transfer", "data": { "progress": 62 } } ], "message": "health check", "data": { "progress": 0 } } ], "message": "backup VM", "data": { "id": "8b921e1c-5cb2-a3d8-6c13-eb9dcf73f993", "type": "VM", "name_label": "1-Romy", "progress": 0 } } ], "infos": [ { "data": { "vms": [ "a6cc5035-c18c-8f35-e197-b7e55c9cab8a", "8b921e1c-5cb2-a3d8-6c13-eb9dcf73f993", "235d2a6a-89a5-845d-9310-11938e65a95e", "6f5c2553-2150-bd34-db9e-2830820247f1" ] }, "message": "vms" } ] } Here are the 3 VMs that ran, the fourth one is XOce that did not run. [image: image.jpeg] I'l test the backups to see if they are OK, then I'l try with node 24.
    • C

      XO RBAC Granularity?

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Management
      10
      0 Votes
      10 Posts
      370 Views
      julienXOvatesJ
      Thanks @ataxyanetwork I was about to answer the same...! (but was too busy this morning )
    • A

      Are there any downsides to using CBT when doing backups?

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Backup
      10
      0 Votes
      10 Posts
      808 Views
      A
      @poddingue Thank you!
    • D

      OKD on XCP-ng

      Watching Ignoring Scheduled Pinned Locked Moved Infrastructure as Code xcp-ng okd openshift rocky fedora
      10
      0 Votes
      10 Posts
      934 Views
      D
      For anyone else who steps through this, I've also installed the latest xen-guest-agent with the below process. Repeat for each host in the environment, 1 at a time from your Helper VM. ### ssh into your helper ### oc debug node/fedora-cmp-1/2/3 chroot /host cd /var/tmp curl -LO https://gitlab.com/xen-project/xen-guest-agent/-/jobs/6041686376/artifacts/raw/RPMS/x86_64/xen-guest-agent-0.4.0-0.fc37.x86_64.rpm sudo rpm-ostree install /var/tmp/xen-guest-agent-0.4.0-0.fc37.x86_64.rpm mkdir /var/tmp/xga && cd /var/tmp/xga rpm2cpio ../xen-guest-agent-0.4.0-0.fc37.x86_64.rpm | cpio -idmv ### From your helper... DRAIN YOUR WORKERS ### oc adm drain fedora-cmp-1/2/3 --ignore-daemonsets --delete-emptydir-data ### log back into fedora-cmp-1/2/3... ### sudo systemctl reboot ### from helper ### oc adm uncordon fedora-cmp-1/2/3 ### login to fedora-cmp-1/2/3 ### chroot /host sudo systemctl enable --now xen-guest-agent And then from XO this is what your VMs will look like. [image: image.jpeg]
    • S

      Backup failures after VHD to QCOW2 conversion

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Backup
      8
      0 Votes
      8 Posts
      418 Views
      poddingueP
      Thanks for sharing those. I can't read SMlogs well enough to add anything useful myself, so this is really one for @Team-Storage. One thing though: if I read the link right, it expires on 23 November, so it would be good if someone grabbed the files before then.
    • I

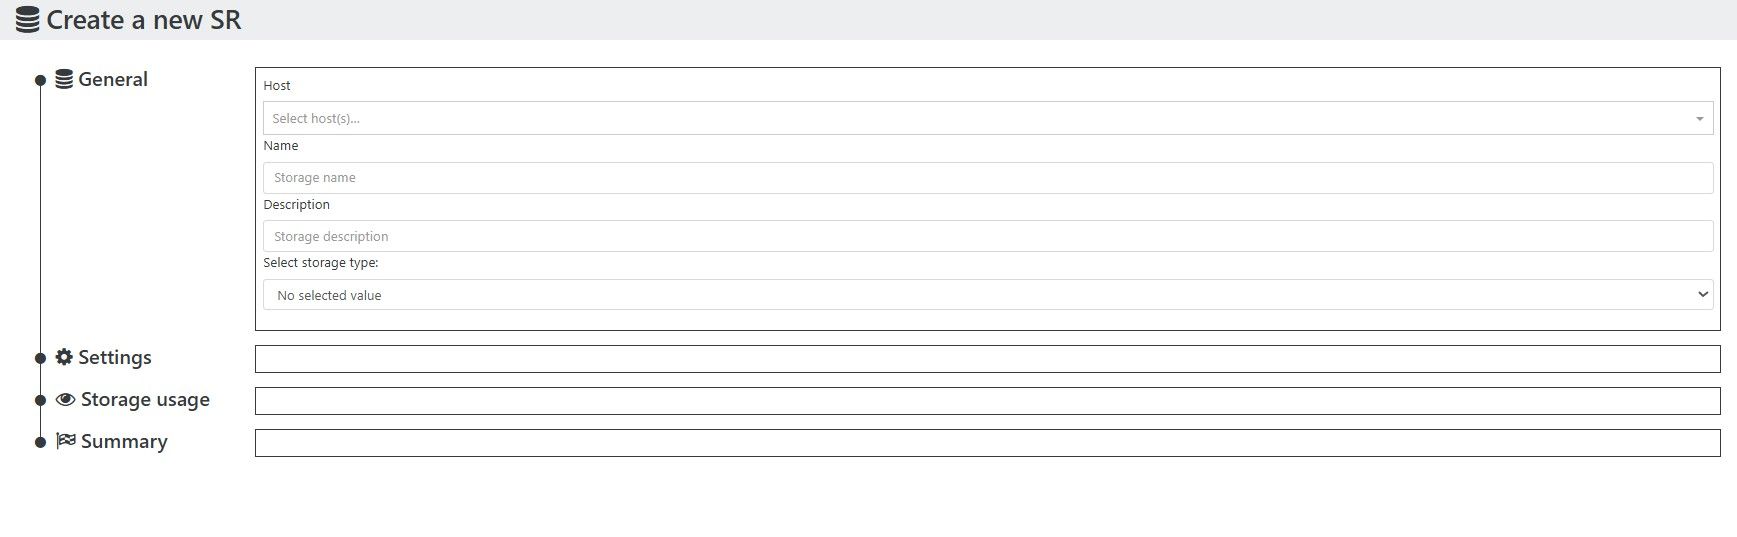
      Slow SR Creation

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Management
      14
      1
      0 Votes
      14 Posts
      1k Views
      tjkreidlT
      @irtaza9 What do you see if you run top or xtop, or "xe task-list" when you start the process?
    • Z

      Veeam and XO backup CBT. How to avoid conflict?

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Backup
      7
      0 Votes
      7 Posts
      476 Views
      poddingueP
      @zorro So with purge off, Veeam stayed clean for a few nights, which fits what I saw in the lab test. If I read the docs right, the cost is that XO's reference snapshot keeps its data on the SR again, which you'd notice more on thick-provisioned storage: https://docs.xen-orchestra.com/backups-and-dr/backup-types/incremental_backups#purge-snapshot-data-cbt. Storage hasn't said yet whether purge breaking another tool's chain is expected, so I'd still call this a workaround rather than the answer. If a CBT warning comes back when you add the other VMs, the Veeam task id and the time would probably help them. And keeping both makes sense to me, since Veeam doesn't do the cross-site replication you need XO for.
    • A

      Broadcom removed public access to VDDK download links

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Migrate to XCP-ng
      10
      1 Votes
      10 Posts
      2k Views
      olivierlambertO
      FYI, our approach with vectura is only temporary, we have other plans in few months to get rid of this potential cat & mouse game Broadcom could do by slightly change their protocol (without even talking about the potential legal risk with it).
    • olivierlambertO

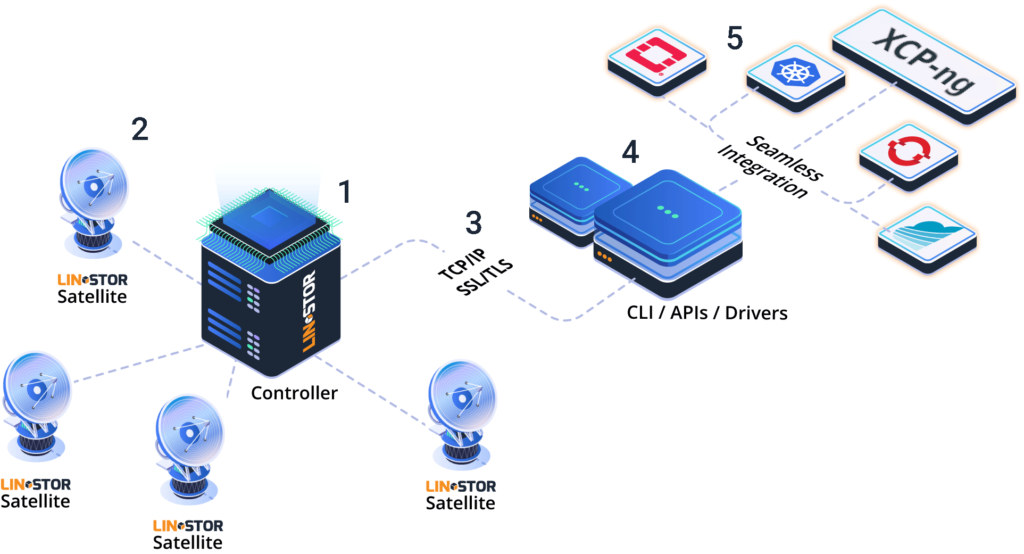
      XOSTOR hyperconvergence preview

      Watching Ignoring Scheduled Pinned Locked Moved XOSTOR
      471
      1
      6 Votes
      471 Posts
      1m Views
      Maelstrom96M
      @dthenot For anyone stuck, here is what I ended up doing: I've manually hardcoded the controller_uri in /opt/xensource/sm/linstorvolumemanager.py on the new host, restarted the toolstack using xe-toolstack-restart and ran the xe host-call-plugin host-uuid=NEW_HOST_UUID plugin=linstor-manager fn=addHost args:groupName=linstor_group/thin_device command. def _get_controller_uri() -> str: # TODO: Check that an IP address from the current pool is returned. #addresses = _get_controller_addresses() return "linstor://10.25.254.100" #return "linstor://" + addresses[0] if addresses else "" After that, you should see the addHost command return True. It should be safe to revert the change to the _get_controller_uri() function and restart to make sure everything starts properly. [10:06 van3-pprod-xen01 ~]# linstor --controllers 10.25.254.100 node l ╭───────────────────────────────────────────────────────────────────╮ ā”Š Node ā”Š NodeType ā”Š Addresses ā”Š State ā”Š ā•žā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•” ā”Š van3-pprod-xen01 ā”Š COMBINED ā”Š 10.25.254.100:3366 (PLAIN) ā”Š Online ā”Š ā”Š van3-pprod-xen02 ā”Š COMBINED ā”Š 10.25.254.101:3366 (PLAIN) ā”Š Online ā”Š ā”Š van3-pprod-xen03 ā”Š COMBINED ā”Š 10.25.254.102:3366 (PLAIN) ā”Š Online ā”Š ā”Š van3-pprod-xen04 ā”Š COMBINED ā”Š 10.25.254.103:3366 (PLAIN) ā”Š Online ā”Š ╰───────────────────────────────────────────────────────────────────╯ [10:06 van3-pprod-xen01 ~]# xe host-call-plugin host-uuid=f9d94f6c-e826-452f-b9b9-638550b209cf plugin=linstor-manager fn=addHost args:groupName=linstor_group/thin_device True [10:08 van3-pprod-xen01 ~]# linstor --controllers 10.25.254.100 node l ╭───────────────────────────────────────────────────────────────────╮ ā”Š Node ā”Š NodeType ā”Š Addresses ā”Š State ā”Š ā•žā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•ā•” ā”Š van3-pprod-xen01 ā”Š COMBINED ā”Š 10.25.254.100:3366 (PLAIN) ā”Š Online ā”Š ā”Š van3-pprod-xen02 ā”Š COMBINED ā”Š 10.25.254.101:3366 (PLAIN) ā”Š Online ā”Š ā”Š van3-pprod-xen03 ā”Š COMBINED ā”Š 10.25.254.102:3366 (PLAIN) ā”Š Online ā”Š ā”Š van3-pprod-xen04 ā”Š COMBINED ā”Š 10.25.254.103:3366 (PLAIN) ā”Š Online ā”Š ā”Š van3-pprod-xen05 ā”Š COMBINED ā”Š 10.25.254.104:3366 (PLAIN) ā”Š Online ā”Š ╰───────────────────────────────────────────────────────────────────╯
    • F

      Unable to update Windows PV driver

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved Management
      6
      4
      0 Votes
      6 Posts
      381 Views
      D
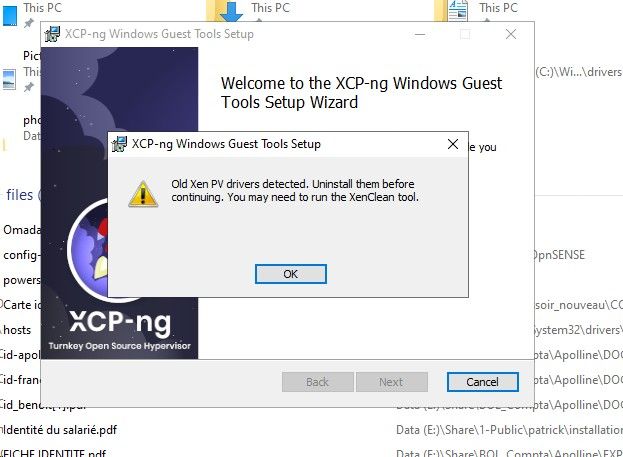
      @fred974 Hello, Could you please provide the logs produced by XenClean after its execution? If your VM couldn't boot after XenClean, XenBootFix executed from a recovery environment should get your VM working again. Instructions are available here: https://docs.xcp-ng.org/troubleshooting/windows-pv-tools/#windows-fails-to-boot-hangs-inaccessible_boot_device
    • D

      Node.js October 21, 2026 Security Releases

      Watching Ignoring Scheduled Pinned Locked Moved Xen Orchestra
      6
      0 Votes
      6 Posts
      1k Views
      poddingueP
      @acebmxer I haven't run your script, so I can't vouch for the log lines, but the systemctl status check looks like the safer of the two to me. It shows the binary the service is really running. Whichever node comes first in your shell can be a different one if more than one Node is installed. For XOA I'd go with what @Danp said above.
    • R

      RPU on XOSTOR pool: live migration fails while evacuating the host running the linstor controller, VM left unmanageable

      Watching Ignoring Scheduled Pinned Locked Moved Unsolved XOSTOR
      5
      0 Votes
      5 Posts
      271 Views
      poddingueP
      If I follow your excerpts, there are two different problems stacked here. One is the LinstorSR attach giving up on what looks like a one-second controller hiccup, which is the @Team-Storage side. The other is xenopsd leaving state behind on both hosts after the failed sync point 4, so that every later run trips over it. I think that half belongs to the toolstack people rather than storage, so I'm adding @Team-XAPI-Network too. I can't judge either part myself, so I'll leave it with them.